LLM developers and foundation model labs
The web content your model needs to train on (at scale, cleaned, and filtered to spec) without building the collection infrastructure to get it.
- Custom data feed scoped and delivered in weeks
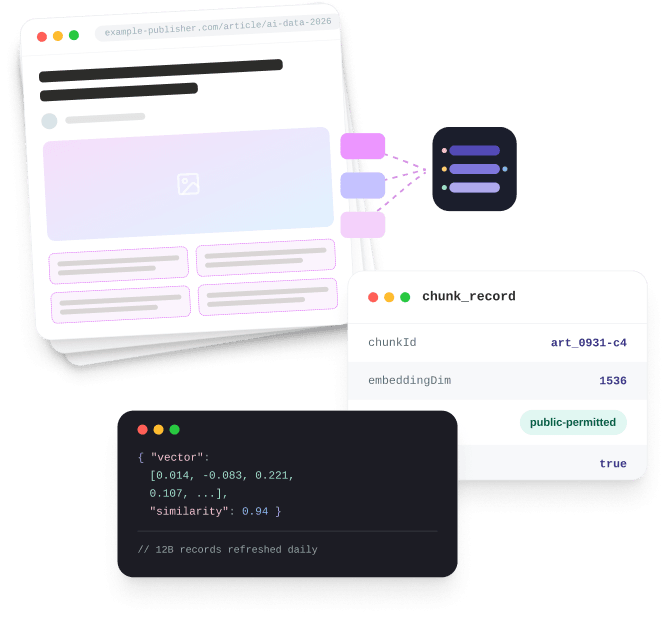
Production-ready data for training, fine-tuning, RAG, and inference, without building or maintaining data collection infrastructure. Build it yourself on Zyte API, or have it delivered to spec by Zyte Data. Same foundation, your choice of who runs the pipeline.


Data for AI is web content collected, structured, and delivered specifically to feed machine learning systems, whether for pre-training, fine-tuning, evaluation sets, retrieval-augmented generation, or agent grounding. It is sourced from public web pages across news sites, forums, documentation, e-commerce, job boards, and more, then cleaned, deduplicated, and normalized into consistent schemas. Because the same information is represented differently across thousands of sites, the value is in the transformation, not the raw page.
The same data type, put to work differently. Ordered by how directly it applies.
The web content your model needs to train on (at scale, cleaned, and filtered to spec) without building the collection infrastructure to get it.
Targeted datasets from authoritative sources in a specific vertical (legal, medical, financial, technical) for supervised fine-tuning.
Fresh, structured content from monitored sources, continuously refreshed so retrieval systems surface answers grounded in current information.
Diverse, representative web samples used to build evaluation sets, stress-test model outputs, and track performance across domains.
Reliable, governed web access for agents that need to read, navigate, or act on live web content without building access infrastructure.
Structured external data to power internal AI assistants, competitive intelligence tools, and decision-support systems at scale.
The problem is rarely a single crawl. It is keeping thousands of sources flowing, correctly, while the web underneath keeps changing, and compliance requirements keep tightening.
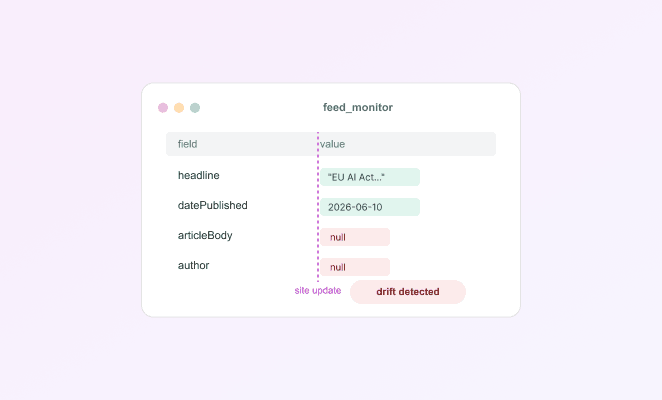
Zyte validates every dataset run against your agreed schema and detects structural drift before it reaches your training data.
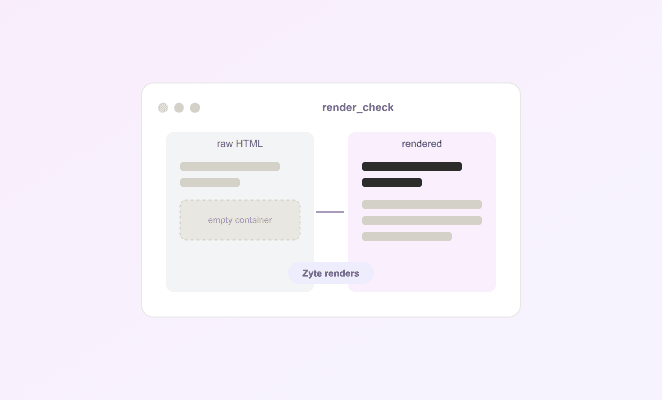
Zyte renders pages the way a real browser does, so dynamic content (forum replies, article bodies, product descriptions) is captured reliably, not truncated.
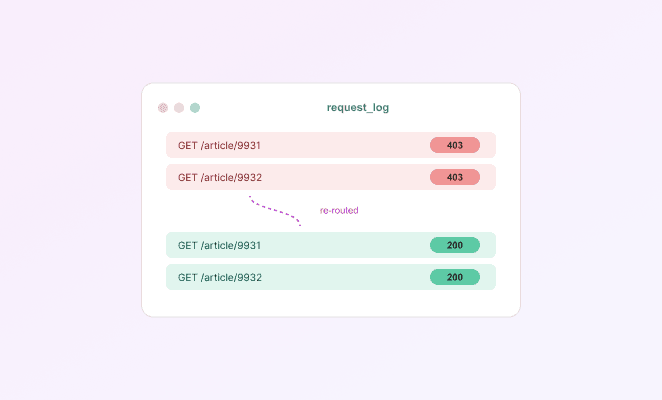
When a request is blocked, Zyte automatically re-routes and retries with a different approach. Persistent blocks escalate to the team running your feed.
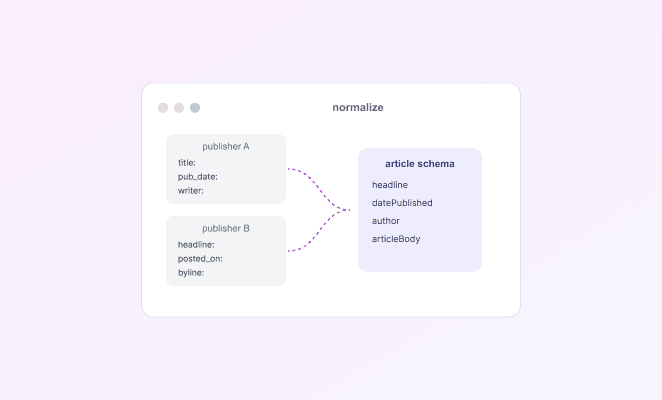
Zyte resolves each source into one consistent schema, so a news article is a news article regardless of how many publishers it came from.
Bad web data does not announce itself. It shows up later, in a model that underperforms on a benchmark that should have been easy.

A model retrained on a gappy or drifted feed degrades for weeks before anyone traces it back to the data.

Teams that retire their in-house scraping stack redirect multiple senior engineers back to building product instead of babysitting pipelines.

The EU AI Act, in force from August 2026, carries penalties of up to €35M or 7% of global turnover for non-compliant AI training data use.

AI procurement reviews stall or fail when teams cannot document where training data came from and how it was collected.
The request you send and the data that comes back. Pick the standard schema or a custom one mapped to your model, and read the response as a table or JSON.
POST https://api.zyte.com/v1/extract

{
  "url": "https://example-publisher.com/article/ai-regulation-2026",
  "article": true
}Reliable Competitor Data Partner with Stellar Support
I have been working with Zyte's team for the last few months, and their team is fantastic. I appreciate their development speed and quality, and they run a very robust platform, producing very satisfactory results. I love the ease of the initial setup with Zyte, as they took care of all the development, and we only needed to communicate what data we needed and set up the necessary processes on our end.
Zyte supports training and pre-training dataset builds, fine-tuning and domain adaptation corpora, RAG knowledge base pipelines, evaluation set construction, and web access for AI agents. Continuously refreshed pipelines are available.
Every dataset Zyte delivers includes documented sourcing — the origin URLs, collection method, extraction date, and schema version. This gives AI teams the audit trail needed for enterprise procurement reviews and, where applicable, EU AI Act compliance documentation.
Zyte delivers data in JSONL, Parquet, CSV, and custom formats, via S3, SFTP, API, or direct warehouse integration. Format and delivery cadence are scoped per project.
For continuously refreshed pipelines, cadence is defined per source based on how frequently that source actually changes. News and forum content can be refreshed daily or intraday; broader web corpora are typically refreshed on a weekly or monthly schedule.
Zyte collects only publicly accessible content and applies opt-out signal detection, copyright flagging, and personal data filtering. For enterprise customers and those subject to the EU AI Act, Zyte provides written documentation of collection methodology and governance controls.
Yes. Zyte Data projects are scoped to your schema — you define the fields, structure, and normalisation logic. Standard schemas are available as a starting point for common content types like articles, products, and job postings.
A scoped dataset with a defined schema and source list typically takes two to four weeks from kickoff to first delivery. Timelines vary with source complexity and volume.
Yes. Talk to a data specialist to request sample data from the sources you care about before agreeing to a contract.