We’re thrilled to announce to our global developer community that Zyte API now comes out of the box with all the features that power our complete solution for scraping with AI, enabling developers to build and launch spiders, unblock websites and extract data from a single UI three times faster than legacy scraping vendors and proxy APIs.
“Developers can now build new spiders and add new data sources in minutes instead of days,” said Iain Lennon, Zyte Chief Product Officer. “Eliminating the need to manually write and maintain code and infrastructure on a site-by-site basis unlocks an ocean of potential for developers and how they spend their time.”
AI Scraping comes out of the box with:
Prebuilt spider templates that take minutes to configure and run
Fork and customize our spider templates, or set up your own to spec, all within Scrapy
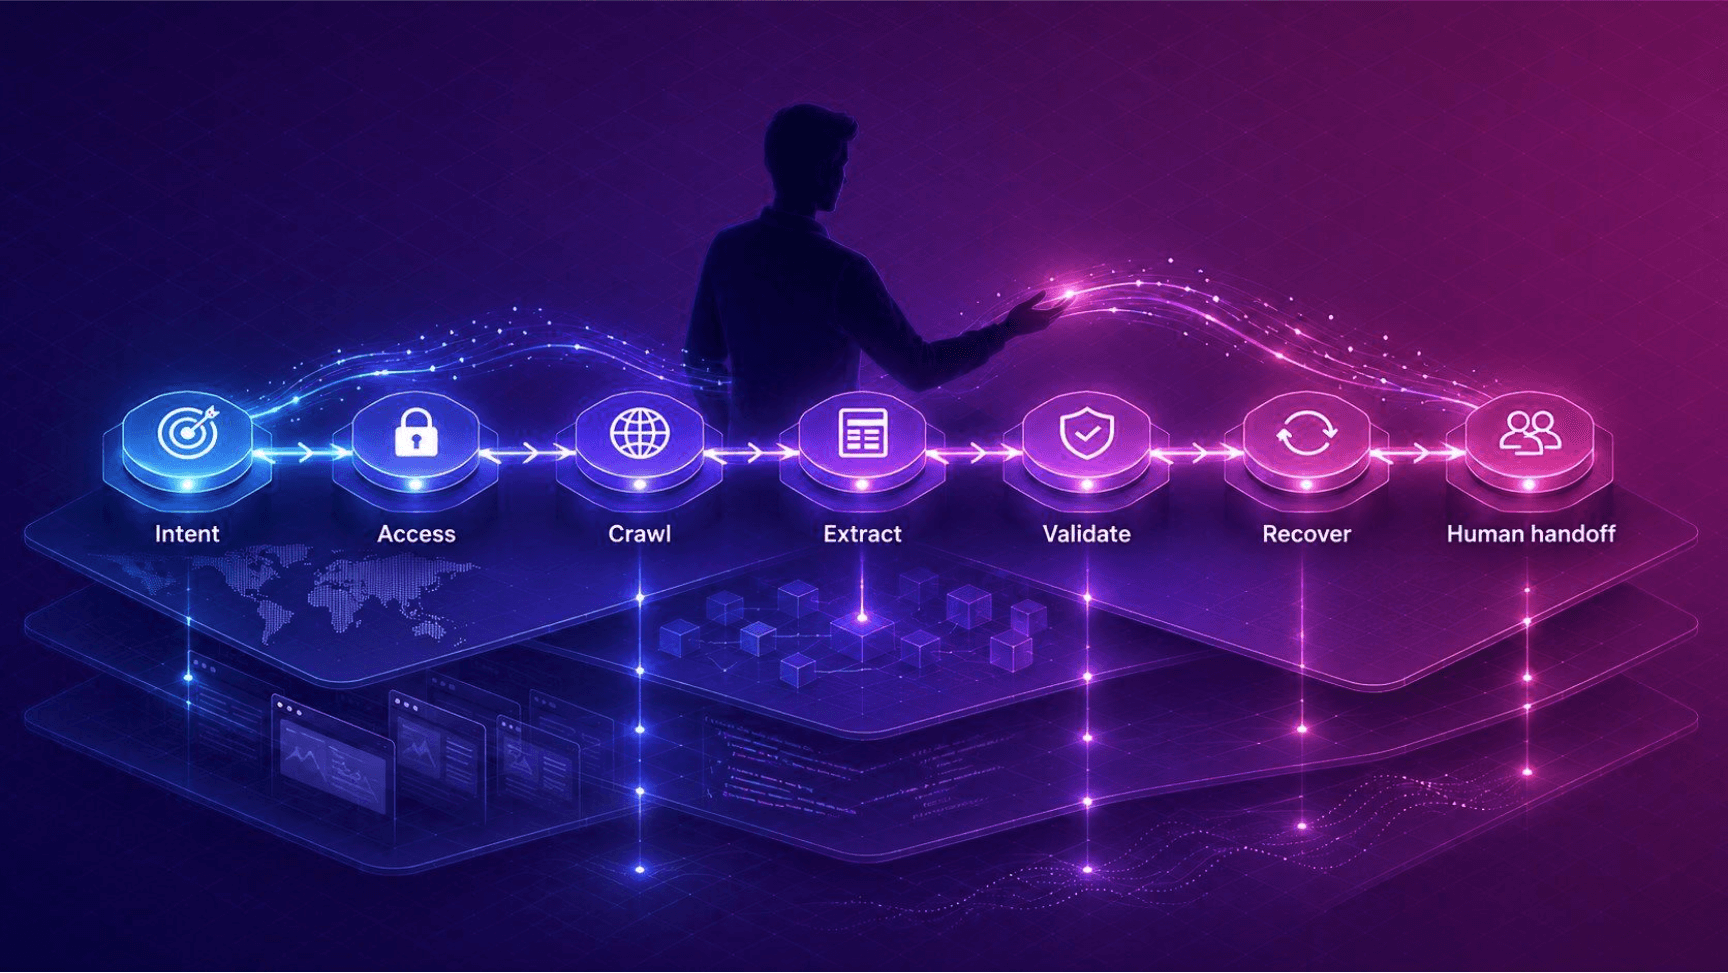
Automated unblocking and ban management that runs in the background as you extract product data from sites of all complexity levels
How it works
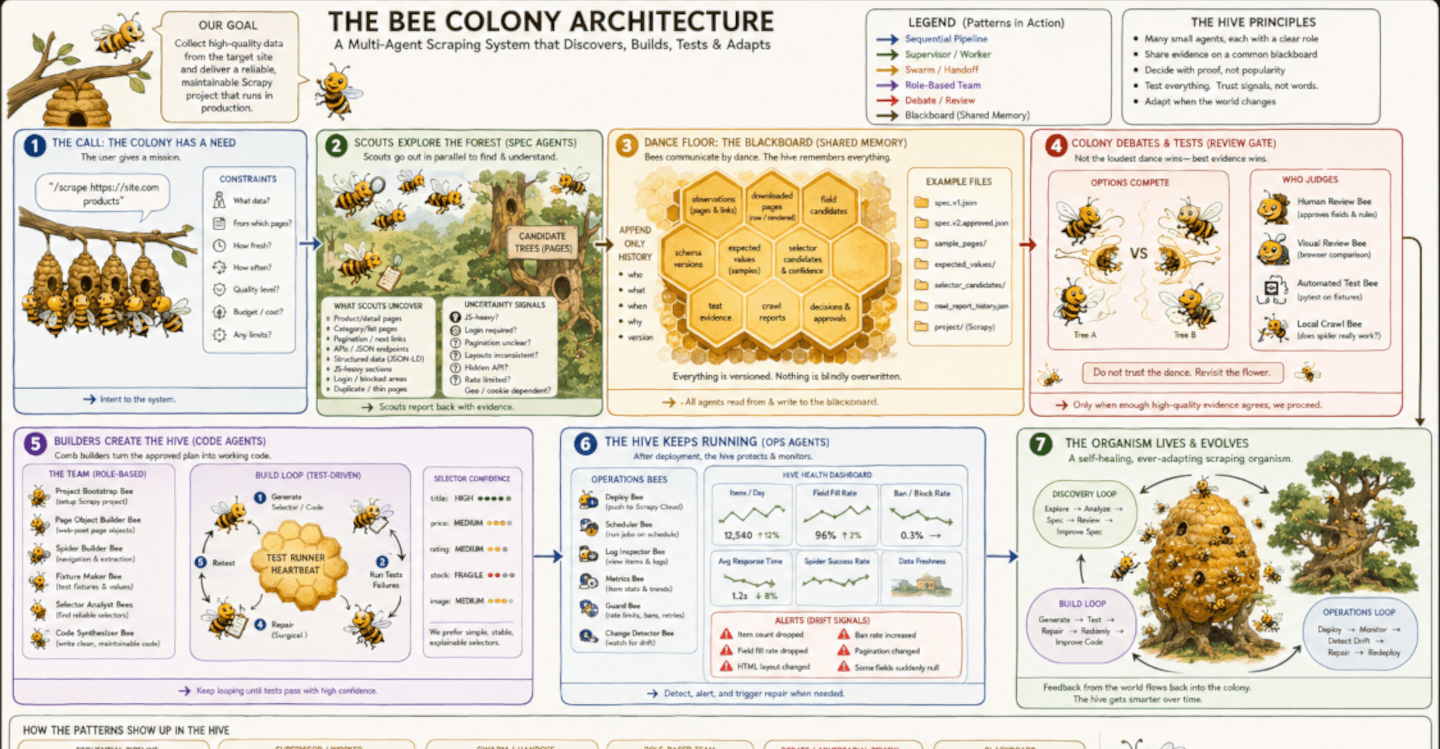
AI Scraping is built on Zyte's AI web scraping stack. The spiders are built on Scrapy, a widely used and highly regarded web scraping framework authored and maintained by Zyte. Smart Spiders leverage Zyte API for unblocking and automation. And Scrapy Cloud provides hosting and UI to host and configure reusable AI powered Spider Templates. It's the AI-first stack for web scraping that works in the background while you're collecting data.
What does AI Scraping mean for the web data extraction industry?
“Businesses and their data teams have been hamstrung by the same web scraping challenges for over a decade,” Lennon said, “and this has caused the industry at large to stagnate technologically and simply accept these challenges as realities.”
These institutional challenges are two fold:
1. Set-up and maintenance are bottlenecks and scalability killers
When developers have to manually write and maintain code and infrastructure on a site-by-site basis, adding a new site takes an average of 24 working hours, and because sites change, each new site also adds significant maintenance overhead that will prevent the company from scaling.
AI Scraping makes it possible for companies to shift the focus from manual code to more relevant tasks since the tool can interpret HTML to figure out which selectors to employ in each website, keeping a consistent data flow even when the layout changes.
2. Solving bans and maintaining access to sites manually is a scalability killer, too
If you have to figure out the most cost-efficient way to overcome a ban for a large number of sites, it’s messy, complicated and manual – full of trial and error unless you have a solution that can automate the process. Without this silver bullet for unblocking, it's a huge time and money commitment, rather than a business driver.
With AI Scraping, ban management becomes automated, and the tool can identify what technologies are necessary to unblock any website, adapting itself as anti-bot evolves.
“This ongoing cycle of inefficiency kills a business’ ability to be agile, and there’s no way to increase output without hiring more developers,” said Lennon. “Zyte API now addresses each of these institutional challenges in an end-to-end capacity.”
How to get started with AI Scraping
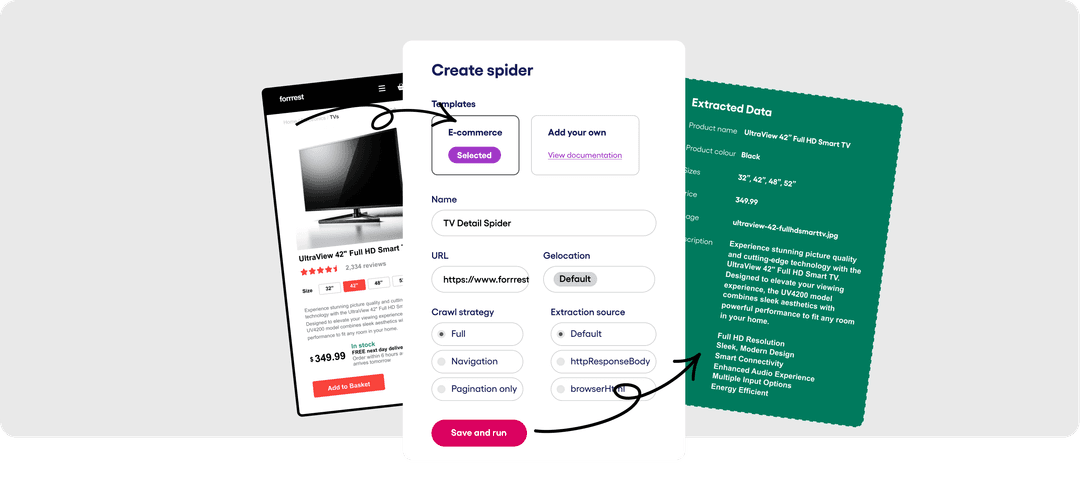
Setting up an AI Scraping project in Zyte API takes seconds. Simply choose AI-Powered Spiders, name your project, select your template, add the site, set your requests number and crawl strategy, and watch the data populate. Adding a new site takes minutes compared to the three business days it takes most teams. It’s as easy as that.
Pioneering open source and ethical web data collection
The foundation of Zyte's market leadership in web data extraction is rooted in Scrapy, a beloved and widely used open source data extraction framework that was originally authored by Zyte CEO Shane Evans. Since the beginning of Scrapy, and millions of users later, Zyte continues to actively maintain and invest resources in the thriving open source framework.
In fall 2023, Zyte co-founded the Ethical Web Data Collection Initiative (EWDCI) with industry counterparts Coresignal, Smartproxy, Rayobyte and Oxylabs. The EWDCI "seeks to foster cooperation in the web data collection and aggregation industry and leverage collective first-hand knowledge and insights to advocate for beneficial technical standards and business best practices regarding the aggregation of data".
Just the beginning of a unified web data extraction stack
With the launch of AI Scraping for product data, the Zyte engineering and product teams are hard at work building out this functionality for additional data types, slated to launch in the next few months.
We’ll also keep integrating more automation and AI-powered features into Zyte API, keeping its leadership as the go-to tool in the market for web scraping needs of all sizes.
We have several game-changing features we’ve developed and are testing with our 100-strong delivery team — from embedding natural language extraction into requests to some world-leading work with image content, as well as video content extraction.
Resources
Zyte proxies and smart browser tech rolled into a single API.