Web scraping APIs
Articles from the Zyte blog about Web scraping APIs.
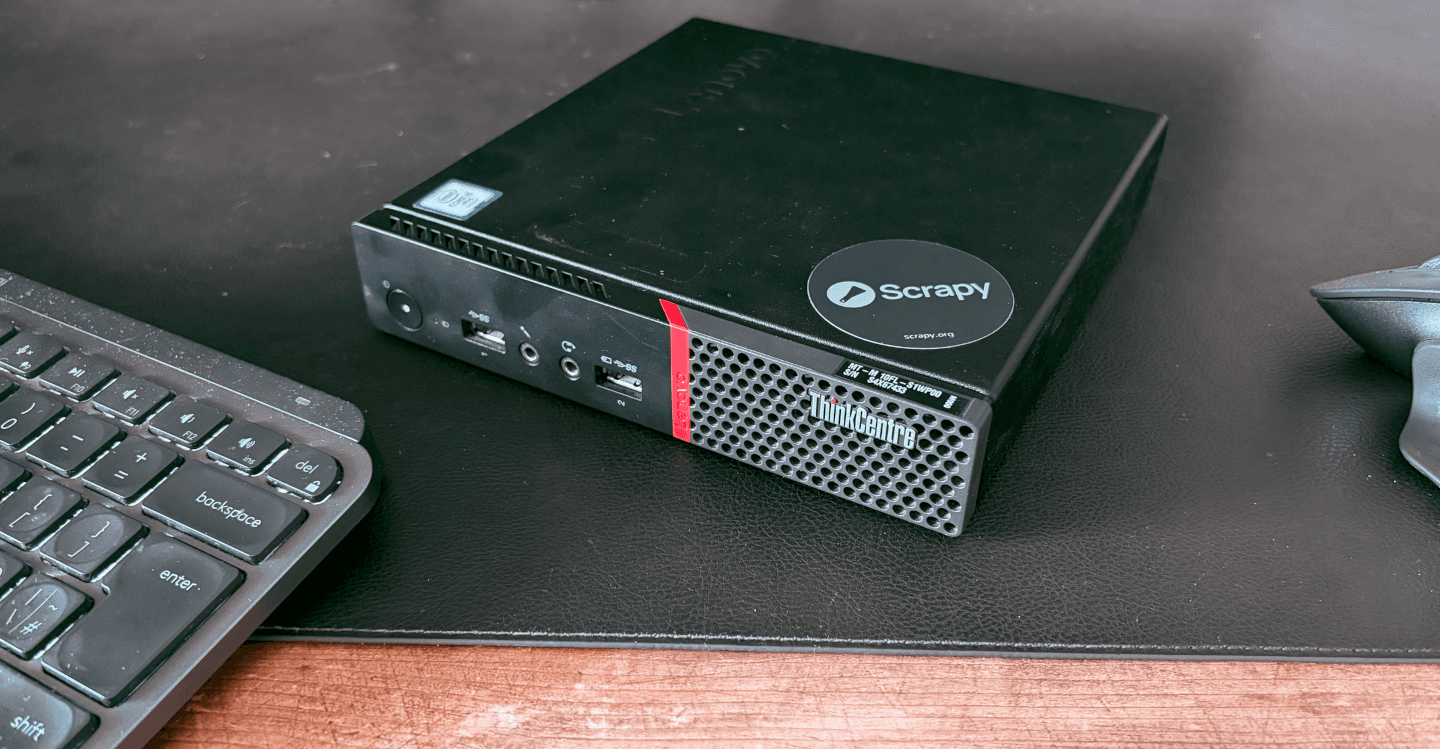
Building a self-hosted browser scraping service (is it more hassle than its worth?)
If you want to understand exactly how a browser scraping service works at the infrastructure level, or you have a steady workload that you want running on hardware you already own, building one yourself teaches you things that matter. Here's how I did it
I'm not the same developer I was before LLMs
I've been running a series of conversations with developers at Zyte to understand what's actually changed in the way they work since LLMs showed up. Not the headlines. The day-to-day. What they delegate, what they don't, what they notice, what surprises them. This one was different on two counts.
Actually, web scraping APIs are cheaper
Many data teams still think running a proxy-based scraping stack is most cost-effective. Industry pressures and our research disprove that idea.
Web scraping APIs vs proxies: A head-to-head comparison
Proxies are essential to scraping at scale. So, how do full-stack web scraping APIs compare?
Legal clarity comes with compliance demands
Explore how new regulations like the EU AI Act and California AB 2013 are reshaping AI data compliance in 2026. Learn why provenance, transparency, and lawful sourcing are now critical.
Giving spidey-senses to your web scraping spiders using Spidermon
Learn how Spidermon helps you monitor web scraping data quality in real time. Validate items, track field coverage, and get alerts before bad data impacts your pipeline.
Web traffic is splintering into access lanes
Explore how AI agents are reshaping web traffic into hostile, negotiated, and invited access lanes. Learn what this means for bots, scraping, and the future of data access.
Automation drives power in the data arms race
Anti-bot systems now evolve in minutes, not weeks. Discover why automated, self-healing scraping systems are essential to survive the 2026 data arms race and how to adapt.
Are programming practices relevant anymore?
From LLM-powered extraction to agentic pipelines, here's how AI is reshaping every stage of the web scraping workflow in 2026 -- and what it means for your stack.
AI is the new engine for web scraping
From LLM-powered extraction to agentic pipelines, here's how AI is reshaping every stage of the web scraping workflow in 2026 -- and what it means for your stack.
Data outcomes are top of the scraping stack
By 2026, scraping shifts from proxy management to API-first data outcomes. Learn why unified scraping APIs are replacing traditional stacks.

Build your own MCP server: LLMs meets web data with Zyte API
Learn how to build your own Model Context Protocol (MCP) server to connect LLMs with real-time web data using Zyte API, FastMCP, and the Docker MCP toolkit.