Web data
Articles from the Zyte blog about Web data.
Data is the new water
For 20 years, we were told “data is the new oil”. That’s no longer true. In the era of the fluid web, information is more fundamental, cleaner and abundant than that.
Brand visibility in the digital era: How web data help brands see the full picture
Discover how web data helps brands improve visibility, track competitors, monitor availability, and analyze reviews to win on the digital shelf.
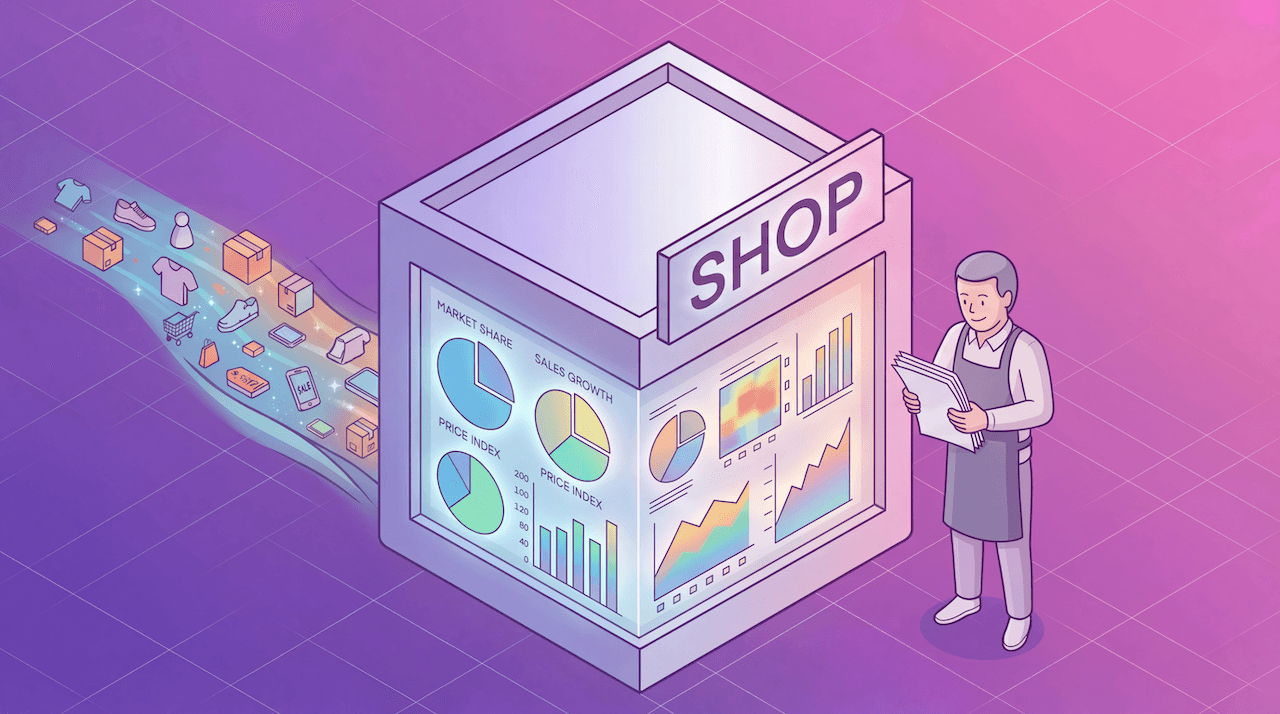
How online retailers use web data to compete on price, promotion, and availability
Discover how retailers leverage web data to optimize pricing, track competitor stock, detect trends, and improve sales performance.
The recipe for a request: Scaling data extraction through investigation
Learn how an investigative mindset helps scale data extraction from single requests to millions daily by building resilient, efficient scraping systems.
How web data turns e-commerce listings into retail intelligence
Discover how web data enables digital shelf analytics vendors to track prices, availability, and product trends at scale—fueling real-time retail intelligence and competitive advantage.
Why your API responses look like gibberish: the gzip decompression trap
The script was working. Requests were going out, responses were coming back with HTTP 200. But the response body was unreadable noise, a wall of binary characters that crashed the JSON parser and reported "no data found". No error code, no timeout, no network failure; just garbage where structured data should be.
Super-powers, toll booths and the new era of data collection
Explore how AI is transforming web scraping, the rise of advanced anti-bot systems, and what the future holds for data collection in an increasingly controlled internet.
More data, more trouble: How a perfect corpus corrupted my AI dream
A failed AI experiment reveals why adding more data doesn’t always improve LLM outputs. Learn when web scraping, RAG, and curated datasets actually make AI better.
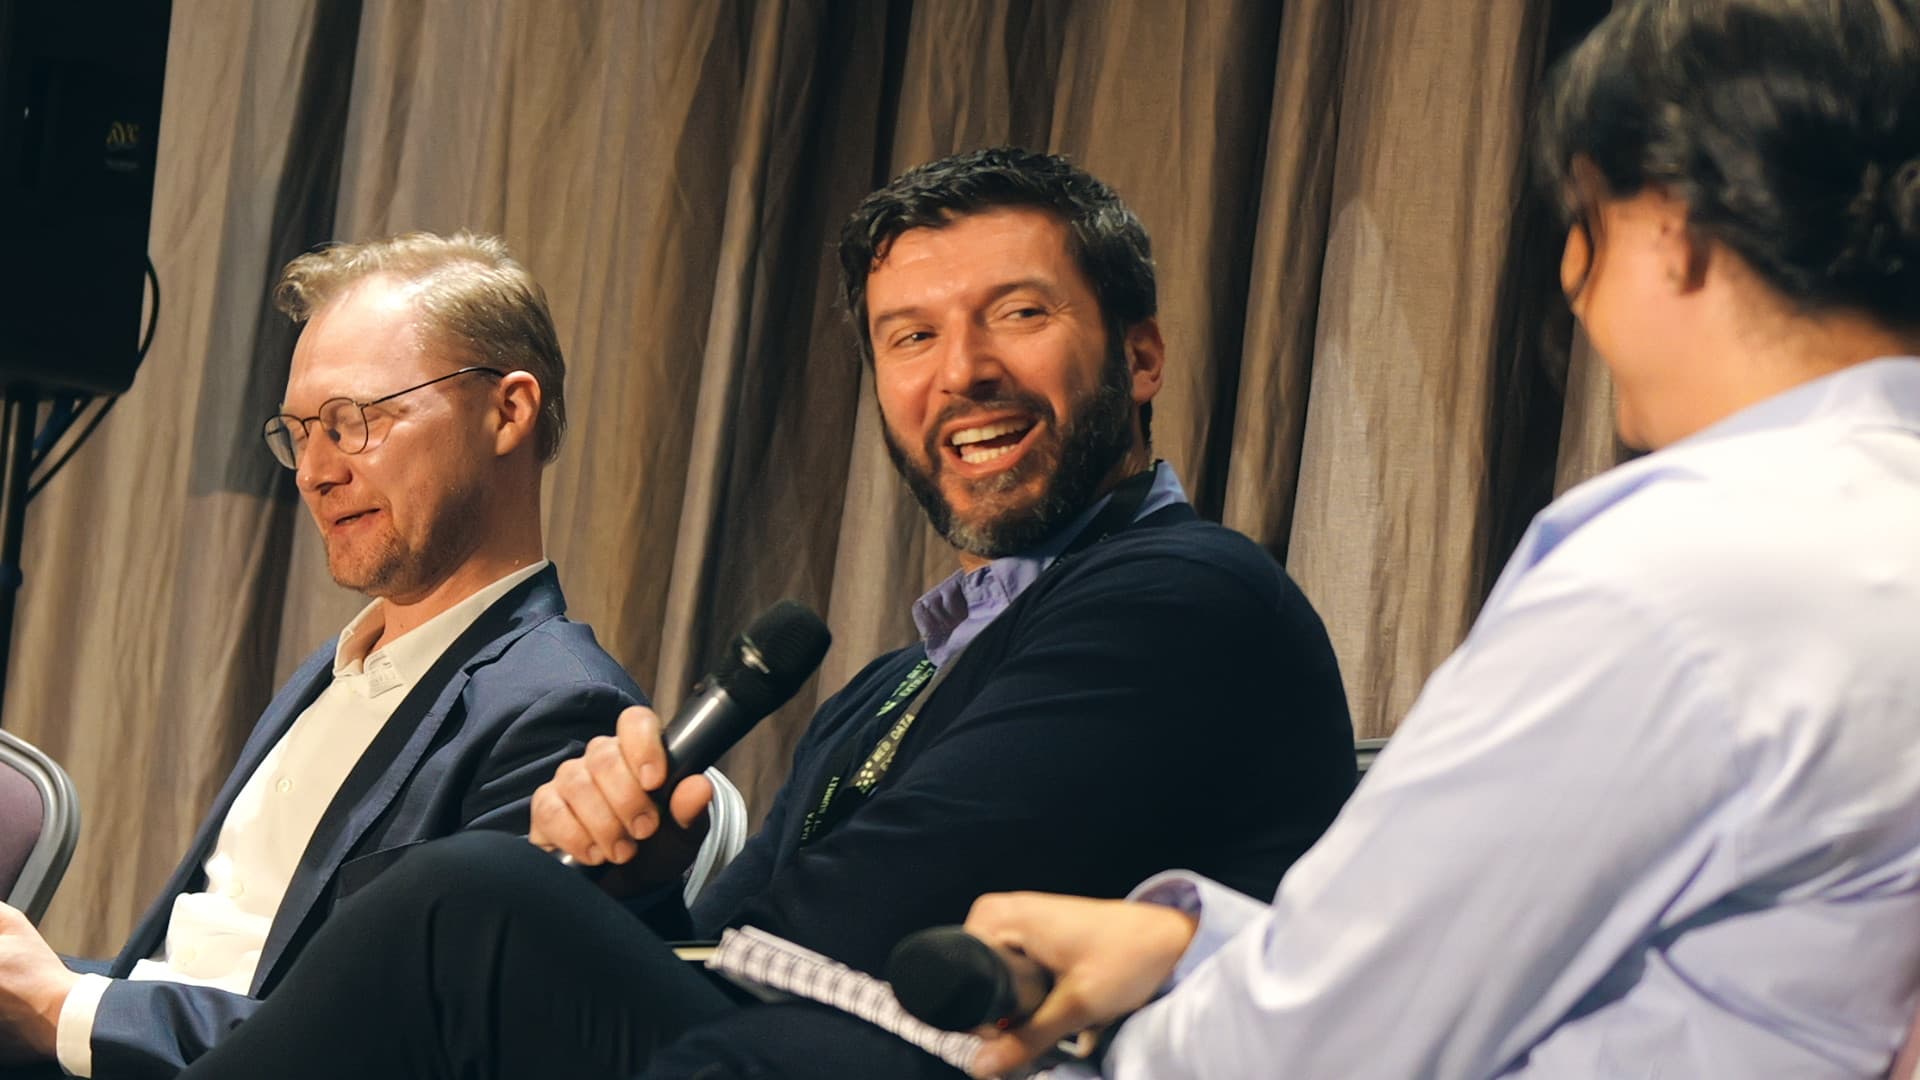
Is your AI breaking the law? Legal experts’ advice for web scrapers
Legal experts discuss how AI, web scraping, copyright law, and the EU AI Act intersect—covering fair use, data provenance, and compliance risks for businesses.
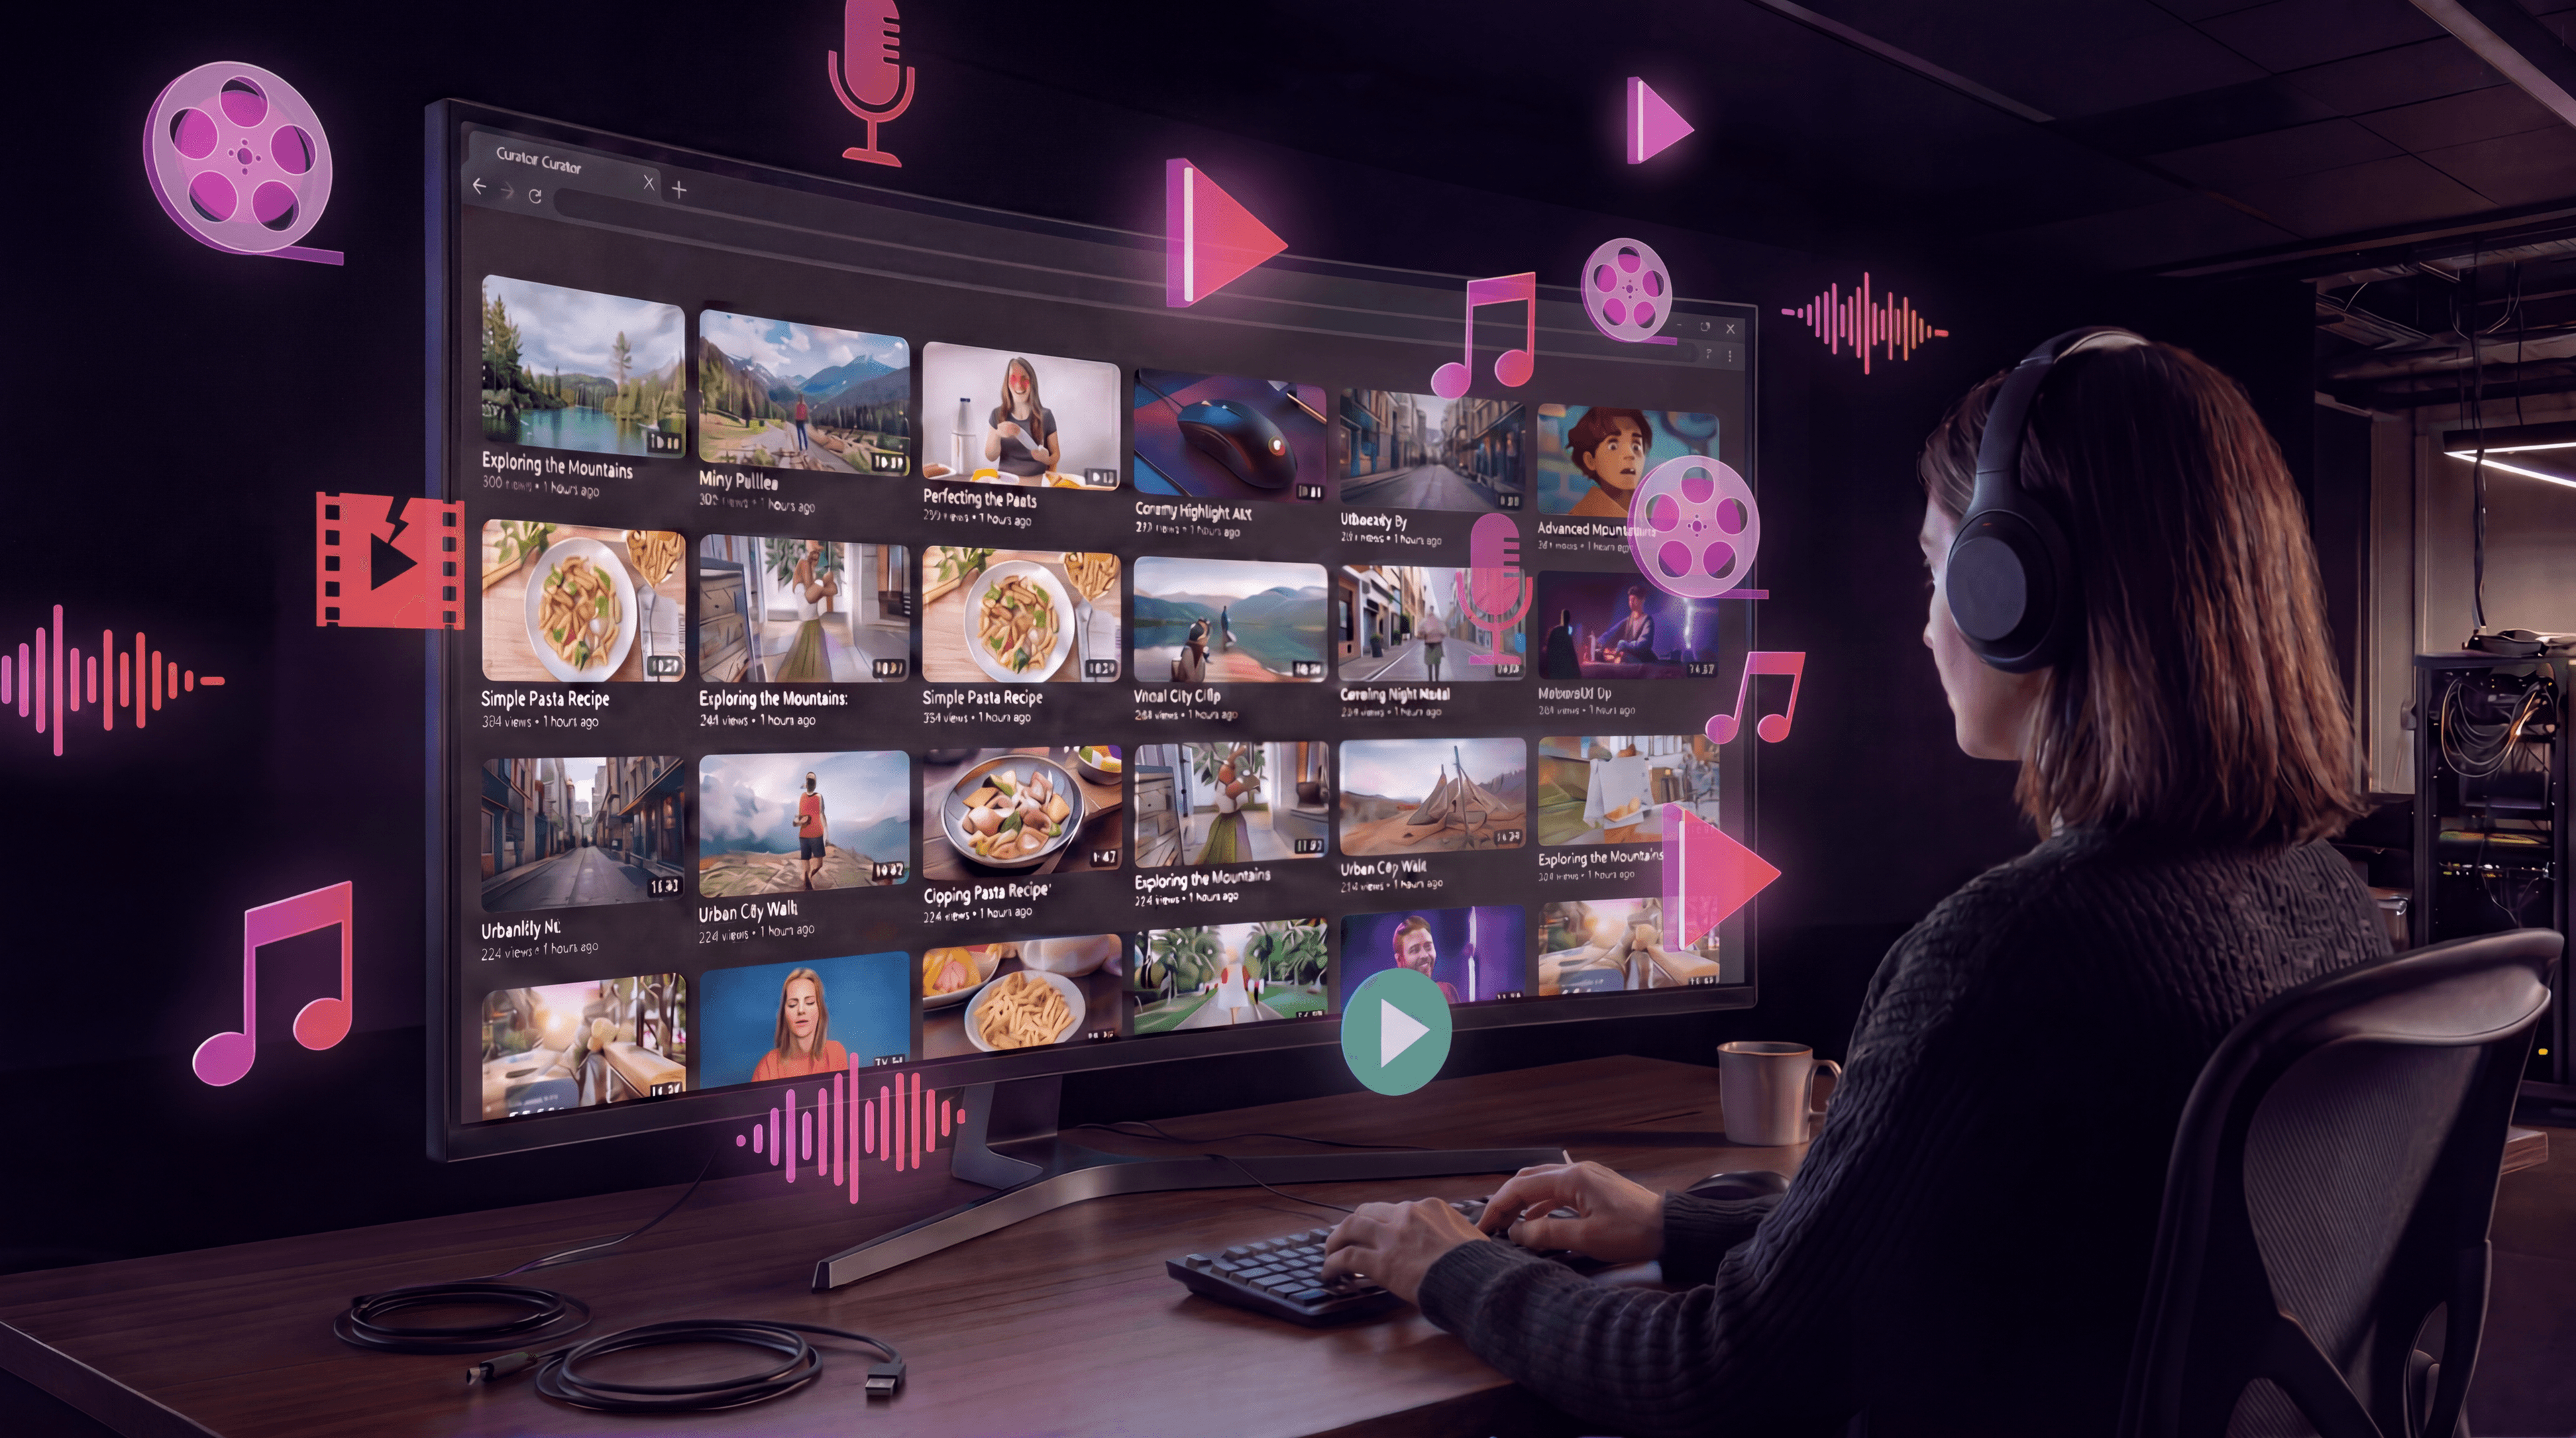
Beyond text: Unlocking value on the multimedia web
The web is about more than the written word. Why companies are racing to harness the power of video, audio and pictures.
Why Python Requests gets "403 Forbidden"
If you’ve had your HTTP request blocked regardless of using correct headers, cookies, and good IPs, there’s a chance you are running into one of the simplest forms of blocking, and one of the most confusing for beginners.
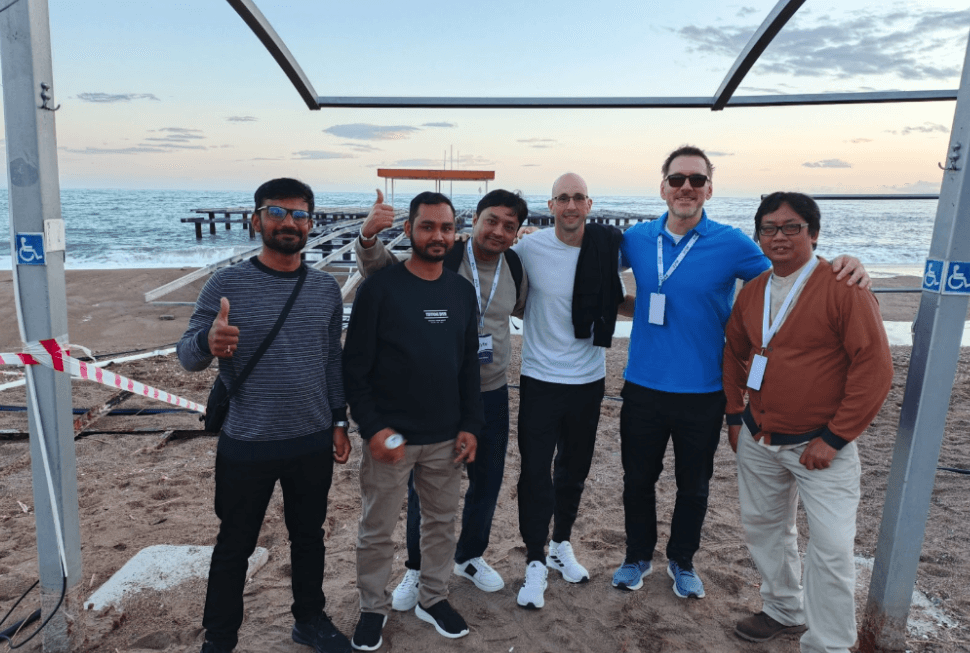
Sun, sea and code: What we built at Zyte’s API hackathon
Discover the 7 creative projects built at Zyte’s API Hackathon in Turkey, from security scanning tools to price comparison engines and smart caching systems.