Web data
Articles from the Zyte blog about Web data.
More data, more trouble: How a perfect corpus corrupted my AI dream
A failed AI experiment reveals why adding more data doesn’t always improve LLM outputs. Learn when web scraping, RAG, and curated datasets actually make AI better.
Is your AI breaking the law? Legal experts’ advice for web scrapers
Legal experts discuss how AI, web scraping, copyright law, and the EU AI Act intersect—covering fair use, data provenance, and compliance risks for businesses.
Beyond text: Unlocking value on the multimedia web
The web is about more than the written word. Why companies are racing to harness the power of video, audio and pictures.
Why Python Requests gets "403 Forbidden"
If you’ve had your HTTP request blocked regardless of using correct headers, cookies, and good IPs, there’s a chance you are running into one of the simplest forms of blocking, and one of the most confusing for beginners.
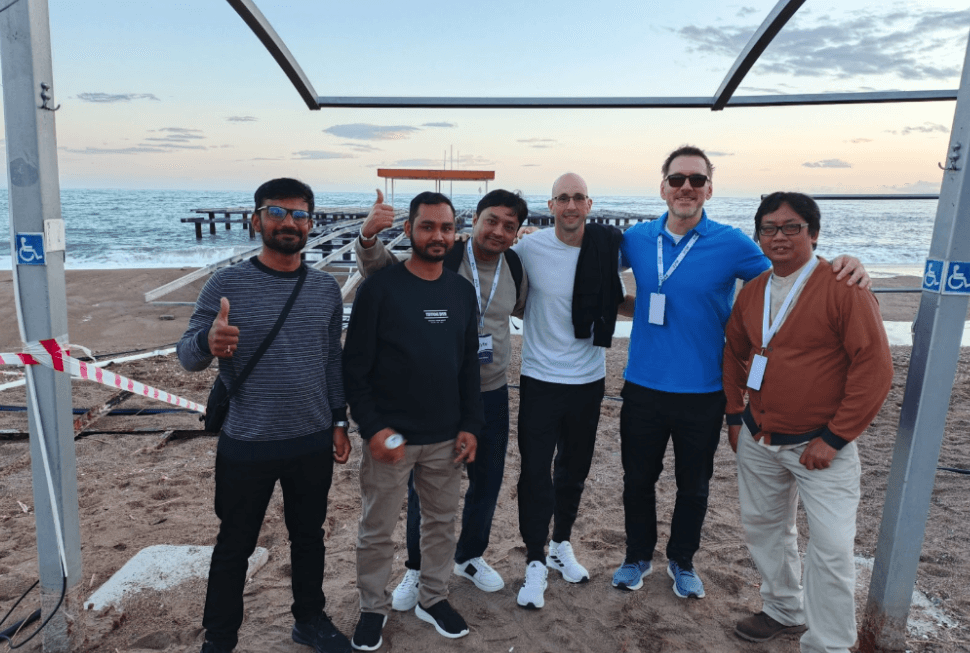
Sun, sea and code: What we built at Zyte’s API hackathon
Discover the 7 creative projects built at Zyte’s API Hackathon in Turkey, from security scanning tools to price comparison engines and smart caching systems.
Hybrid scraping: The architecture for the modern web
Learn how hybrid scraping combines headless browsers and lightweight HTTP clients to bypass JavaScript challenges efficiently. Reduce RAM usage, improve speed, and scale your web scraping pipelines with session reuse and TLS fingerprinting.
Your business doesn’t care about scraping - it cares about data
Web scraping isn’t the competitive advantage it used to be. Learn why shifting to a scraping API helps engineers reclaim time, reduce maintenance, and focus on delivering reliable data.
AI and the web: What 2025 changed and what comes next
2025 was the year AI learned to reason. From reasoning-first LLMs to autonomous agents and a reshaped web economy, this retrospective explores what changed—and what’s coming next.
AI’s legal frontier: What Europe’s privacy regulators say about scraping personal data
Explore how EU privacy regulators view AI web scraping, lawful bases like legitimate interest, risks of collecting personal data, and compliance best practices.
Beyond the block: The front line of data access
A deep dive into the evolving battle for web data access—featuring insights from Castle, Scrapoxy, and Zyte at Extract Summit 2025. Learn how AI, anti-bots, economics, and authentication standards like Web Bot Auth are transforming scraping, security, and the future of the open internet.
How to build a daily industry news digest
Learn how data analyst Anshika Khandelwal automated a daily AI funding news digest using n8n and Zyte API. Discover how to pull articles, classify funding stories, and deliver a curated newsletter that saves 10+ hours per week.
Scraping a synthetic web: Dead Internet Theory meets web data extraction
AI-generated content now dominates the web. Explore the rise of synthetic internet traffic, how bots shape online discourse, and how data experts can fight back.