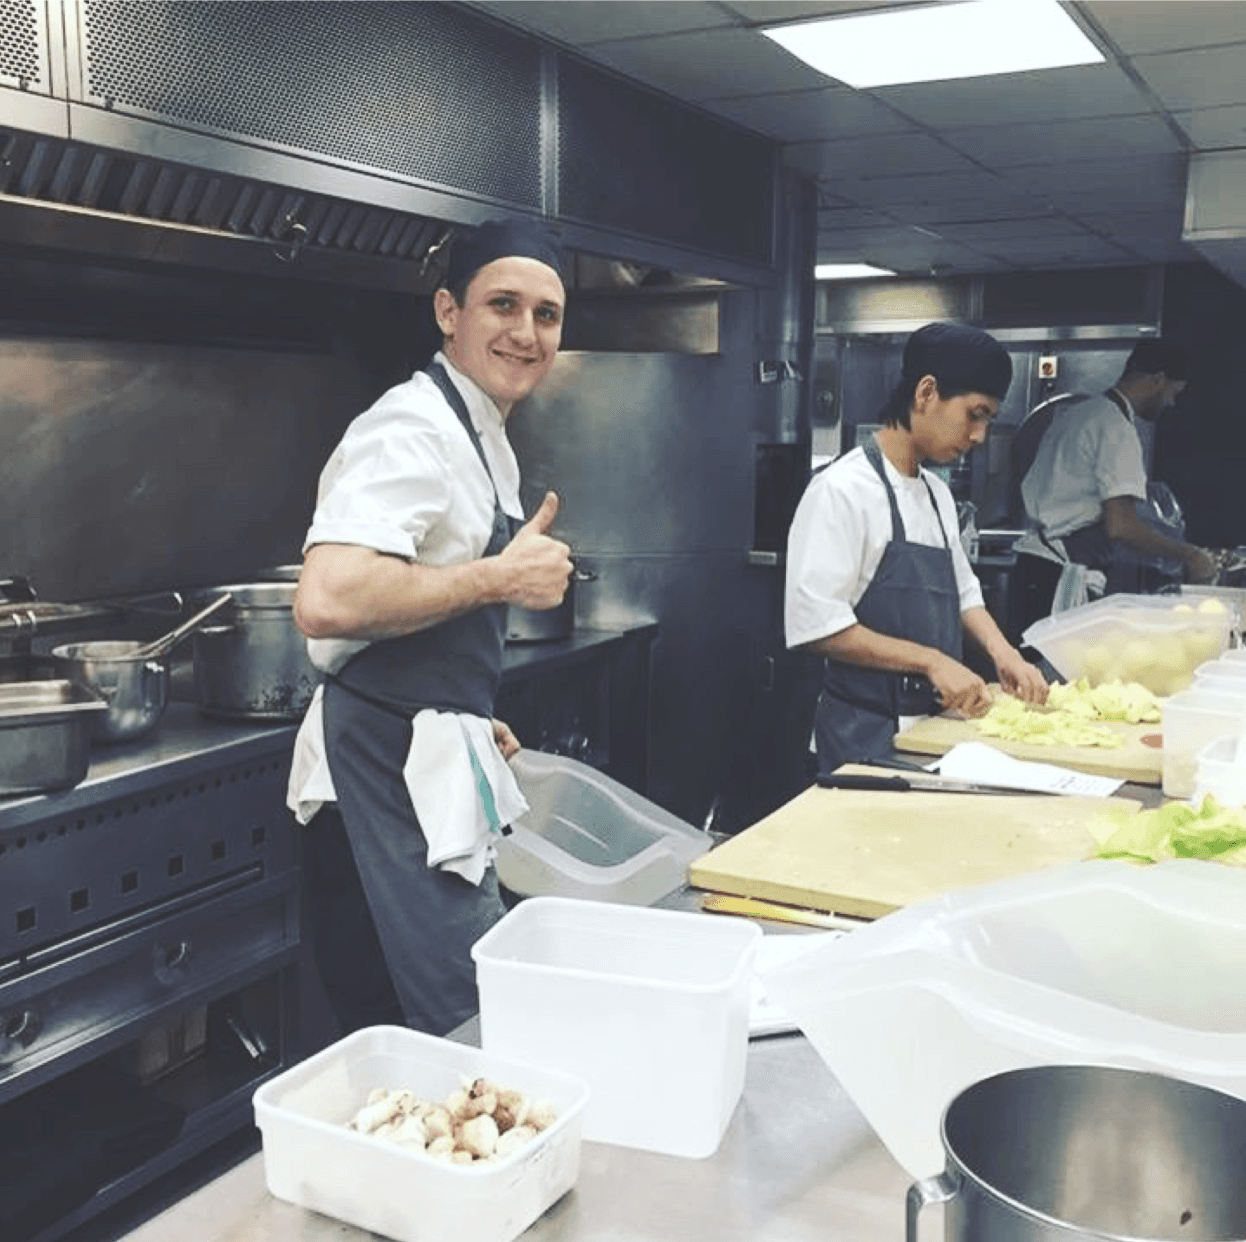
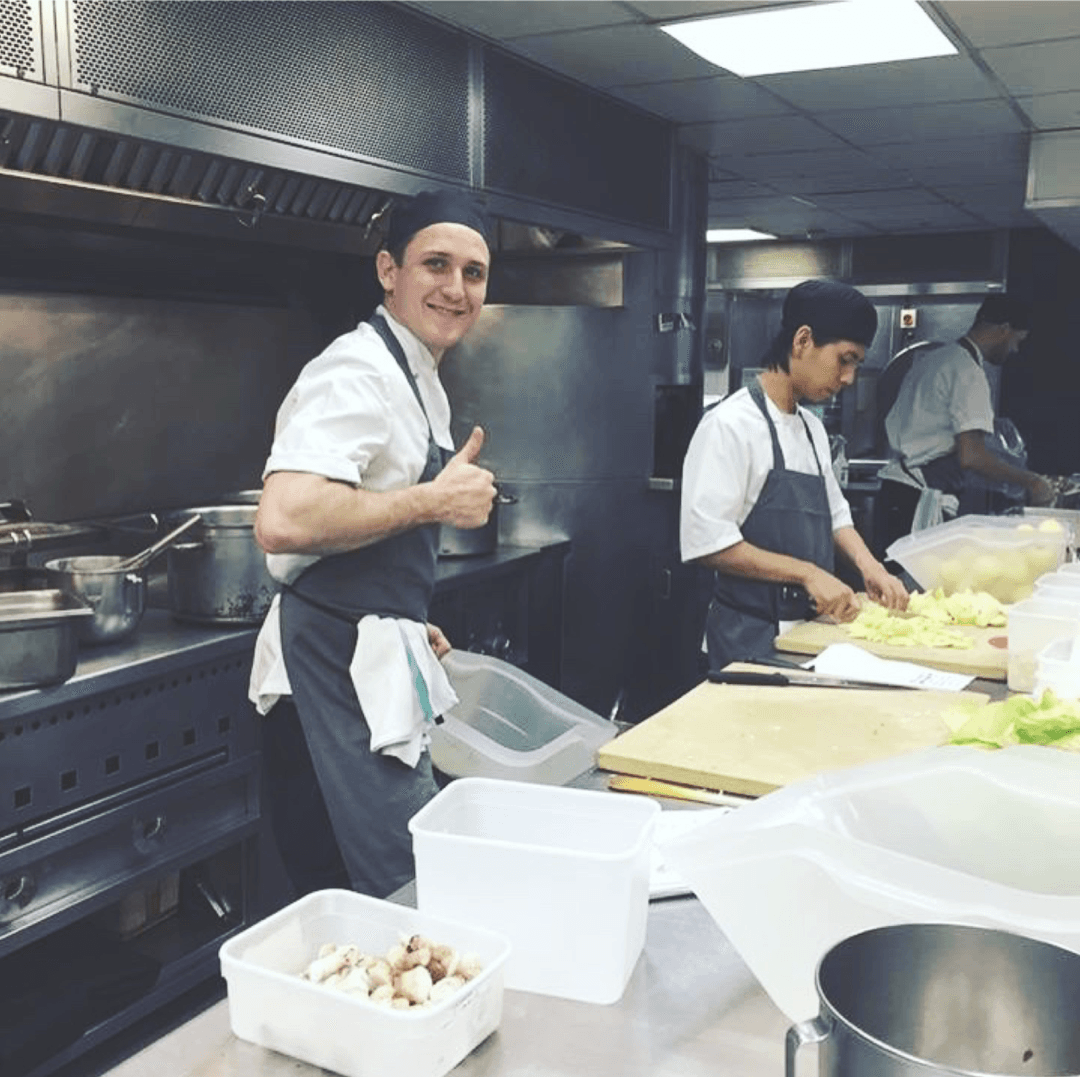
Cooking a delicious meal for your wife at the end of the night - that's super easy.
Now, try cooking 300 plates every day at a Michelin Star level. It's a completely different ball game.
The same is true when we talk about data extraction requests. Sending a single request so that it gets through without a problem is something anyone can do. But scaling that to over 1,000 requests every second changes the game completely.
At Centric Software, we operate at this level, running over 5,000 scrapers that send 130 million requests daily. At this scale, you simply cannot be fixing things every single day. You have to shift your attention from reactive fixes to perfecting the initial development process.
The chef's secret
I used to be a Michelin-trained chef, and I remember working with a colleague who had an amazing capability. He would walk in with a massive list of tasks, and it would just disappear in seconds. I had no idea how he did it. One day, over a beer, I asked him his secret. He told me, "Just take your time."
It sounds counterintuitive, doesn't it? If I work slower on one task, I'll take longer to get to the next. But eventually, it made sense. Every mistake you make is costly. Every time you rush and have to re-do something, it takes time away from you. But, if you take your time, understand the task, and do it correctly the first time, the net amount of tasks you complete is far greater.
“Every minute you spend in the investigation is 10 times that saved in the implementation”
– Kieron Spearing, Data Collection Engineer, Centric Software
This is one of many lessons from the kitchen that can be directly translated to my work today as a Data Collection Engineer.
Adopting an investigative mindset
To build resilient scrapers that can handle thousands of requests per second, you need to adopt an investigative mindset. This is a methodical process for analyzing how a website works before you write a single line of code.
It can be broken down into three key phases:
Learn how the website expects user interaction.
Break down requests to their minimum requirements.
Translate these discoveries into a resilient scraper.
This process ensures you understand the system deeply. As Albert Einstein said:
“If you can’t explain it simply, you don’t understand it well enough.”
– Albert Einstein
A practical investigation: ‘Go shopping’
Let's walk through an example. The first step is to simply "Go Shopping." Open the target website in a browser and use it. How is the data represented naturally? How is a user expected to search for and buy a product?
As you interact with the site, your goal is to find where the data is coming from. Using your browser’s developer tools, you can inspect the network traffic and identify the specific API request that fetches the data you need.
Once you’ve located the request, it’s time for experimentation. This is where the fun begins.
Take the cURL of the request. Extract the raw request from your browser.
Bit by bit, remove components with the intention of breaking the request. Remove headers, cookies, and parameters one by one.
Fix it and repeat. When the request fails, you’ve found an essential component. Add it back, document it, and continue removing other parts.
The goal isn't just to get a working cURL command; the goal is to understand what you learn as you go.
This is why I avoid tools like Postman for this initial investigation, as they can modify the request in subtle ways. A better approach is to use a reverse proxy like mitmproxy, which shows you exactly what is being sent. For performing the investigations and documenting these requests, especially in a team environment, I recommend a tool like Bruno.
During this process, you should be able to answer several key questions:
Are cookies required?
Are any headers essential?
Where are dynamic values generated?
Is proxy quality important?
Is the proxy tied to the request?
Is the header order important?
Common pitfalls vs. winning strategies
This investigative process helps avoid common pitfalls that lead to brittle scrapers and technical debt. By shifting your strategy, you build for resilience and scale from the very beginning.
| Pitfalls (The Quick Way) | Strategies (The Resilient Way) |
|---|---|
| HTML-first approach: Scraping data directly from the HTML structure. | API-first approach: Finding the underlying API that populates the page. APIs are more stable and less likely to change than front-end layouts. |
| Gathering the entire feed at once: Creating a single, monolithic process to discover and collect all data. | Decouple discovery and collection: Use one process to find all the product URLs and a separate process to collect the data for each URL. This prevents a single failure from stopping the entire operation (avoiding cascading failure) and allows for targeted retries. |
| Hitting the website without regard to latency: Sending requests as fast as possible without any delays. | Retries with Jitter and/or bounded exponential backoff: Be respectful. Implement intelligent delays and backoff strategies to avoid overwhelming the server, which also reduces the chance of getting blocked. |
| Quick-fix approach: Rushing to get a scraper working to meet a deadline, creating technical debt. | Well-documented investigations & sustainable mindset: Take your time. Thoroughly document your findings. This creates a sustainable system that requires far less maintenance in the long run. |
By documenting your discoveries, you create a blueprint for a robust scraper. You understand your framework's limitations and can build any necessary tools.
Ultimately, scale comes from building resilient systems.
So, how can we send 1,000 requests per second as easily as we send one? The answer lies in the methodical, investigative process. Every minute you spend in the investigation is 10 times that saved in the implementation.
Because every chef knows that thorough preparation is the key to fine food.