Scraping strategy
Articles from the Zyte blog about Scraping strategy.
Inside Scrapy's RemoteControl extension
Scrapy 2.19's RemoteControl extension runs a small authenticated HTTP server inside every crawl. How it starts, how it's secured, what the code you send can reach, and what you can do with it on a live crawl, plus the traps and what changes under scrapy-zyte-api.
The web is being priced, not blocked
Zyte's State of Web Access research finds new barriers making web scraping more difficult. We interview the researcher who says that doesn't mean the opportunity is over.
Rendering Javascript pages without giving up Scrapy
How to render dynamic content and work with a browser through playwright and scrapy.
A guide to Scrapy item types
Scrapy supports multiple item types, but which should you use, and why.
Podcast Ep08 - Scrapy, Python and mushroom soup
Scrapy's core handles crawling well and deliberately leaves almost everything else out: no bundled browser, no opinion about how you shape your data, no built-in answer for every anti-bot wrinkle. What it gives you instead is a clean way to add those things at the edges, exactly when you need them and never before.
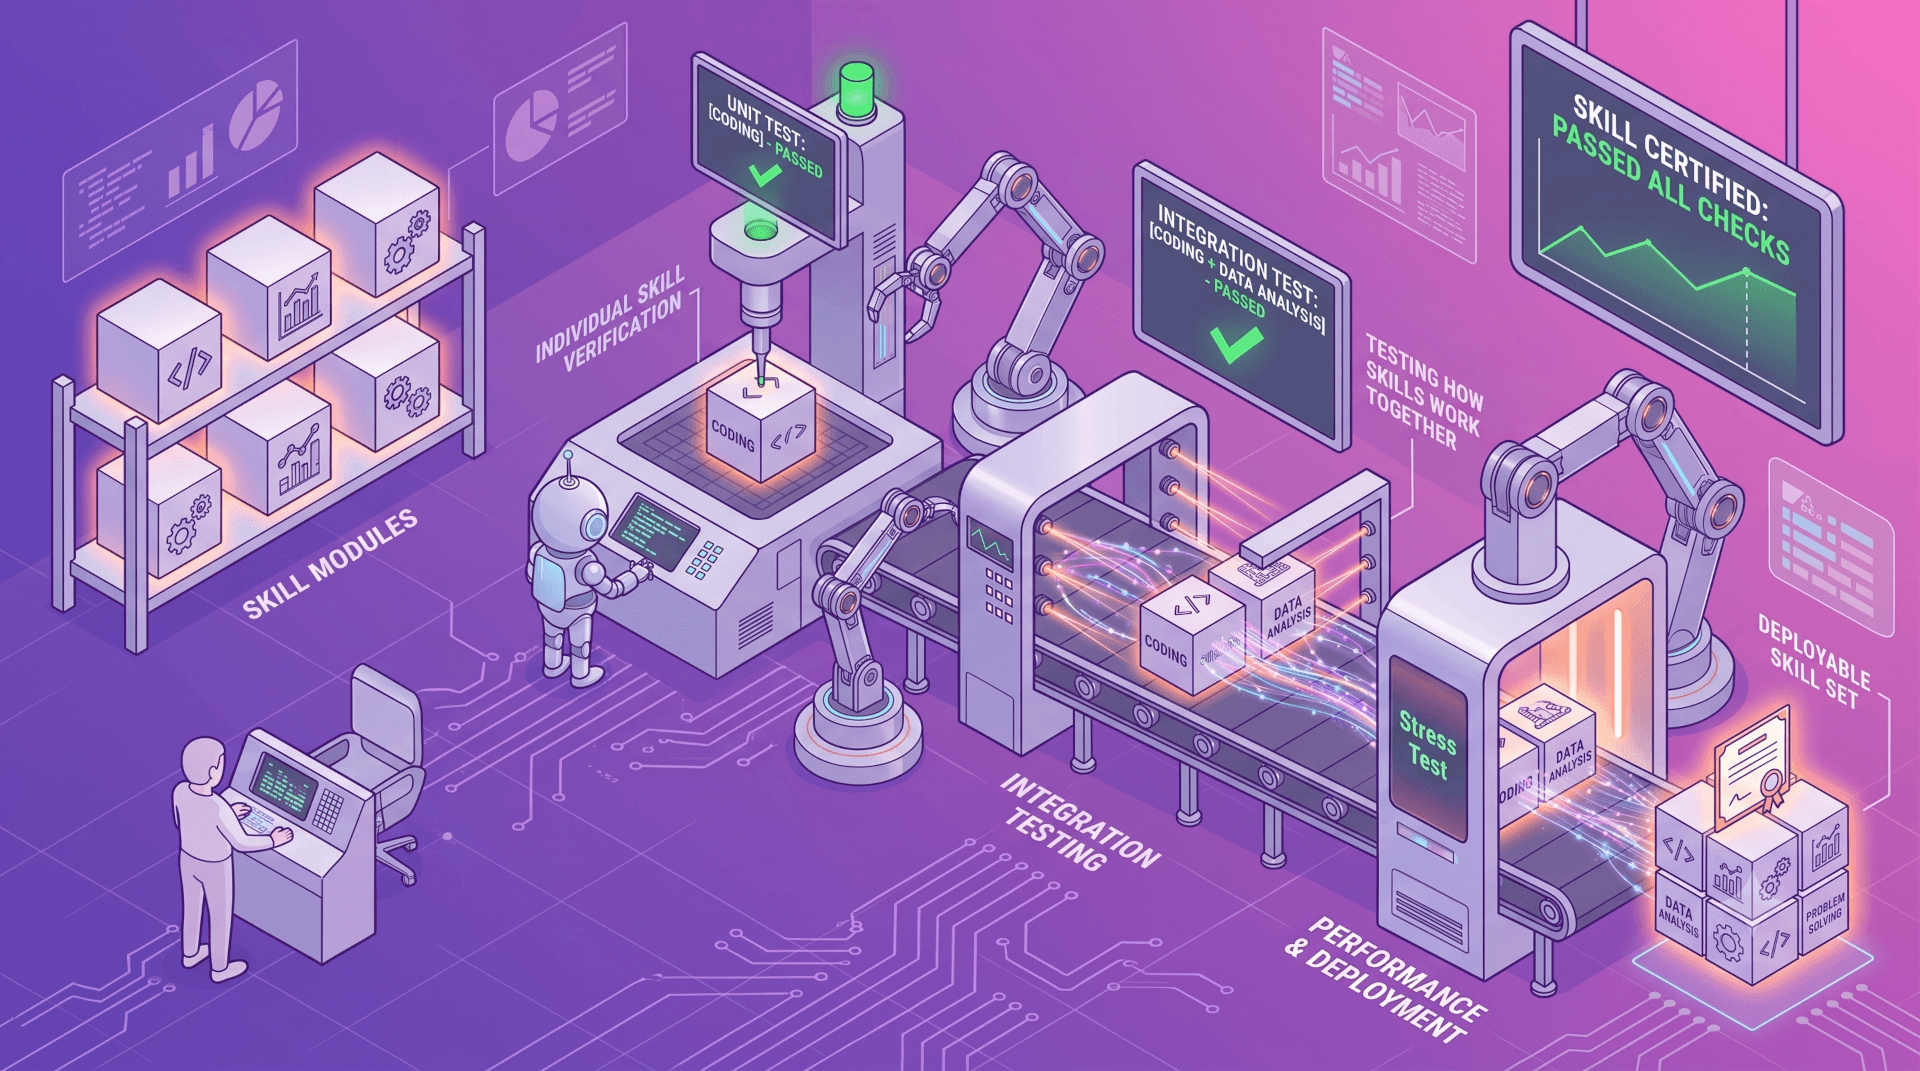
Treat your AI skills like software, starting with evals
Most AI skills are never tested — and it shows. Here's how Zyte evaluates scraping skills like real software, catching failures demos miss.
The great wall of data: The complexities of web scraping in the Asian market
While the technological arms race of web data access is universal, the battleground in Asia has its own unique rules of engagement.
Brand visibility in the digital era: How web data help brands see the full picture
Discover how web data helps brands improve visibility, track competitors, monitor availability, and analyze reviews to win on the digital shelf.
How online retailers use web data to compete on price, promotion, and availability
Discover how retailers leverage web data to optimize pricing, track competitor stock, detect trends, and improve sales performance.
How web data turns e-commerce listings into retail intelligence
Discover how web data enables digital shelf analytics vendors to track prices, availability, and product trends at scale—fueling real-time retail intelligence and competitive advantage.
The seven habits of highly effective data teams
Discover the seven habits that set high-performing data teams apart—from treating data as a product to ensuring data trust, quality, and decision impact. Learn how leading teams scale reliable data systems.
Five key takeaways from Extract Summit 2025
From AI-accelerated scraping to “dead internet” risks and rising access wars, these five takeaways from Extract Summit 2025 show where web data is heading next.
More articles on Scraping strategy
- The data quality playbook: how to measure and score the quality of your web data
- The new economics of web data: Smaller scraping just got cheaper
- How to Plan Your Web Scraping Project Like a Product Manager
- How Zyte’s extraction experts guarantee data quality
- Cheaper web data is changing strategy—are you keeping up?
- Build or Buy? Solving the web scraping dilemma
- Why are Sessions Crucial in Web Data Extraction?
- The trade-offs in crawling infrastructure in the modern anti-bot landscape
- Transitioning to Remote Working as a Company: Lessons Learned
- Handling COVID-19 as a Fully Remote Company: Zyte's Approach
- Best Recruitment Tips: How To Scout Top Talent
- Embracing The Future Of Work: How To Communicate Remotely
- A Not-So-Short Story on Getting Decent Internet Access
- Chats with Rinar Solutions: Insights into Remote Working
- Tips for Creating a Cohesive Company Culture Remotely
- Aduana: Link Analysis to Crawl the Web at Scale
- StartupChats: Embracing Remote Working for Success
- Traveling Tips for Remote Workers: Balancing Work and Adventure
- A Career in Remote Working: Embracing Flexibility and Freedom
- Zyte: A Remote Working Success Story