Scrapy Cloud
Articles from the Zyte blog in Scrapy Cloud.
Introducing Zyte MCP: Powerful web data gathering for your agent
Zyte MCP brings live web access, structured extraction and Scrapy Cloud operations into coding agents such as Claude Code, Cursor and Codex.
Is your AI coding assistant stuck in the past?
AI coding tools like Copilot can suggest outdated code and practices. Learn why this happens and how developers can ensure they use the latest standards.
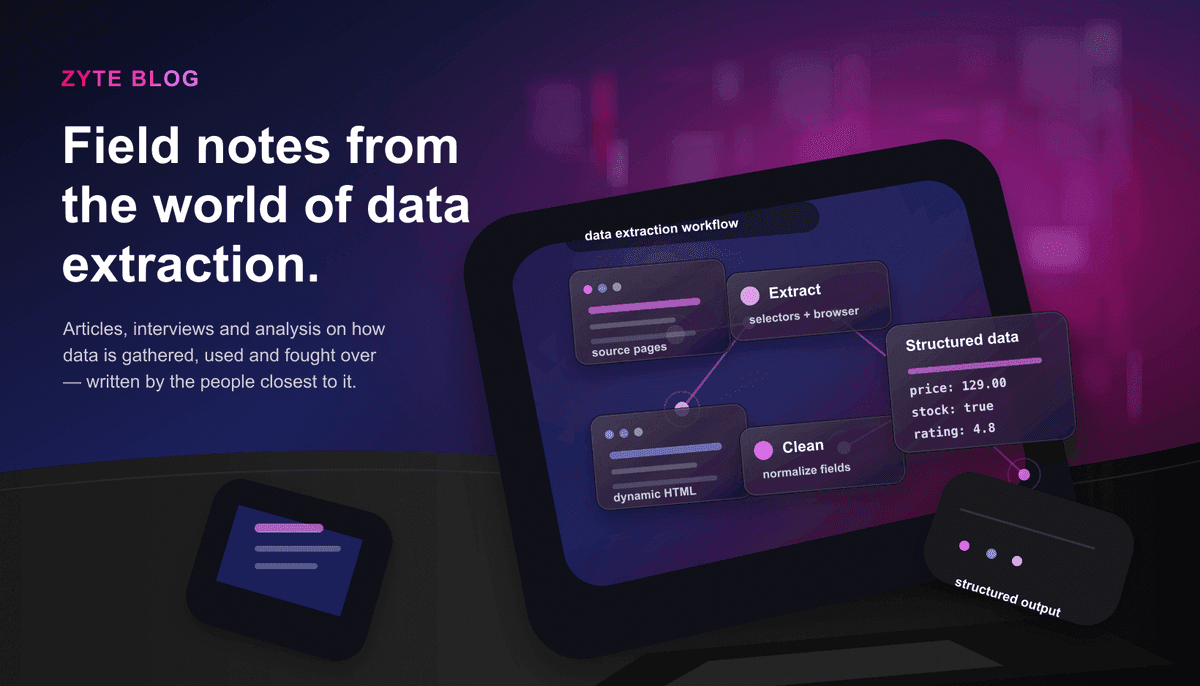
The Modern Scrapy Developer's Guide (Part 2): Page Objects with scrapy-poet
In this guide, we'll fix this by refactoring our spider to a professional, modern standard using Scrapy Items and Page Objects (via crapy-poet). We will completely separate our crawling logic from our parsing logic.
Scrapy Cloud secrets: Hub Crawl Frontier and how to use it
Our scrapy cloud secrets help you deal with real cases that put your data extraction pipeline at risk. You have to be fully prepared for every scenario.
Extract Summit 2021: Highlights and key takeaways
For the third time, Extract Summit brought together web data experts and enthusiasts to learn, share and inspire. Sessions, workshops, panels and contests.
Scrapy Tutorial: Scraping Infinite Scroll Pages With Python
In the sixth part of our Scrapy tutorial you will learn how to find and use underlying APIs that power AJAX-based infinite scrolling mechanisms in web pages.
Scrapy Cloud Secrets: Hub Crawl Frontier And How To Use It
Our scrapy cloud secrets help you deal with real cases that put your data extraction pipeline at risk. You have to be fully prepared for every scenario.
Spidermon: Zyte's secret to data quality
Unveil Spidermon's role in our data quality assurance. Elevate confidence in the reliability of your web-scraped data.
Meet Spidermon: Our battle tested spider monitoring library
Learn how to easily monitor scrapy spiders & validate data with Spidermon! Developed by Zyte Spidermon is now available as an open-source library.
Deploy Your Scrapy Spiders From GitHub | Scrapy Cloud
Starting deploying your scrapy spiders from github now. Connect your Scrapy Cloud project with a repository branch before you push changes.
How To Run Python Scripts In Scrapy Cloud
While just the tip of the iceberg, I’ll demonstrate how to use custom Python scripts to notify you about jobs with errors. If this tutorial sparks some
How To Deploy Custom Docker Images For Your Web Crawlers
Learn how to deploy custom Docker images for your web crawlers with our comprehensive guide, optimizing performance and scalability for your data extraction needs.