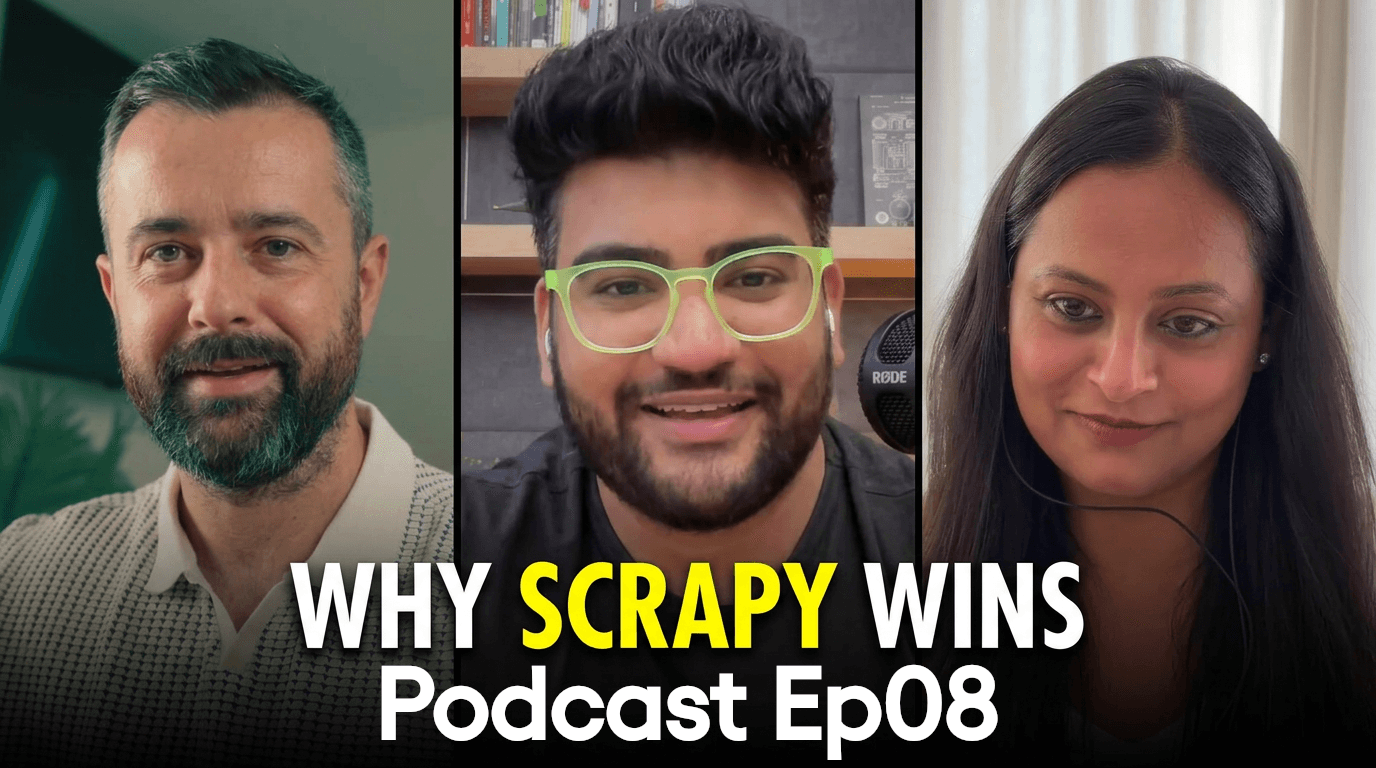
Scrapy does less than people expect, and that is the whole idea. The core handles crawling well and deliberately leaves almost everything else out: no bundled browser, no opinion about how you shape your data, no built-in answer for every anti-bot wrinkle. What it gives you instead is a clean way to add those things at the edges, exactly when you need them and never before. That decision, lean at the center and easy to extend everywhere else, is the thread John, Neha, and Ayan keep pulling on in episode 8, and it is why a framework first released in 2008 still fits the way people scrape today.
They arrive at it from three different directions, a runaway crawl at IBM, a wall of JavaScript that broke a testing script, an ecommerce automation job that quietly turned into a career, but they land in the same place. In an era of stealth browsers, TLS fingerprinting, and AI agents that write their own spiders, a small core you can extend beats a big framework that tries to decide everything for you.
The shift hiding inside the vocabulary
Somewhere in the last few years, web scraping quietly became data extraction, and the team argues the change is more than a rebrand. It reframes the whole job around the data and the pipeline it feeds rather than the act of grabbing pages. That reframing is also why John drifted away from Scrapy for a while, back when a site's back-end API was sitting right there in the network tab and a full framework felt like overkill. What pulled him back has everything to do with how cheap and how common anti-bot systems have become, and he walks through exactly where that line gets crossed. We went deeper on one piece of that puzzle in our write-up on the pluggable browser providers now in scrapy-playwright, which is the lean-core idea taken right down to the choice of browser binary, but the episode is where the reasoning behind it lands.
Moments worth pressing play for
A few of the threads the three of them get into:
- The Django comparison that finally makes Scrapy's lean, extensible design click.
- Why John reaches for exactly four plugins on every production-grade build, and which one he thinks almost nobody uses.
- The anti-bot tradeoff that looks completely different once you see it from the vendor's side, and what that tells you about where the gaps are.
- How keeping the core small is quietly what makes self-healing, agent-driven spiders possible in the first place.
- Neha on Pydantic versus Spidermon, framed as a QA engineer at the end of the line against an auditor watching the whole crawl.
- The single-file Scrapy trick that makes no sense until an agent needs it, and the decades-old Linux tool that lets a headless browser run on a server.
- A detour into food science, the "law of extraction," and why it has no business circling back to the theme as neatly as it does.
Watch or listen
Prefer audio?
Either way, the parts where the three of them disagree are usually where the useful stuff is. And if you would rather skip the fingerprinting arms race entirely and get straight to clean data, you can try Zyte API on a free trial and let the unblocking run in the background.