Web data collection
Articles from the Zyte blog about Web data collection.
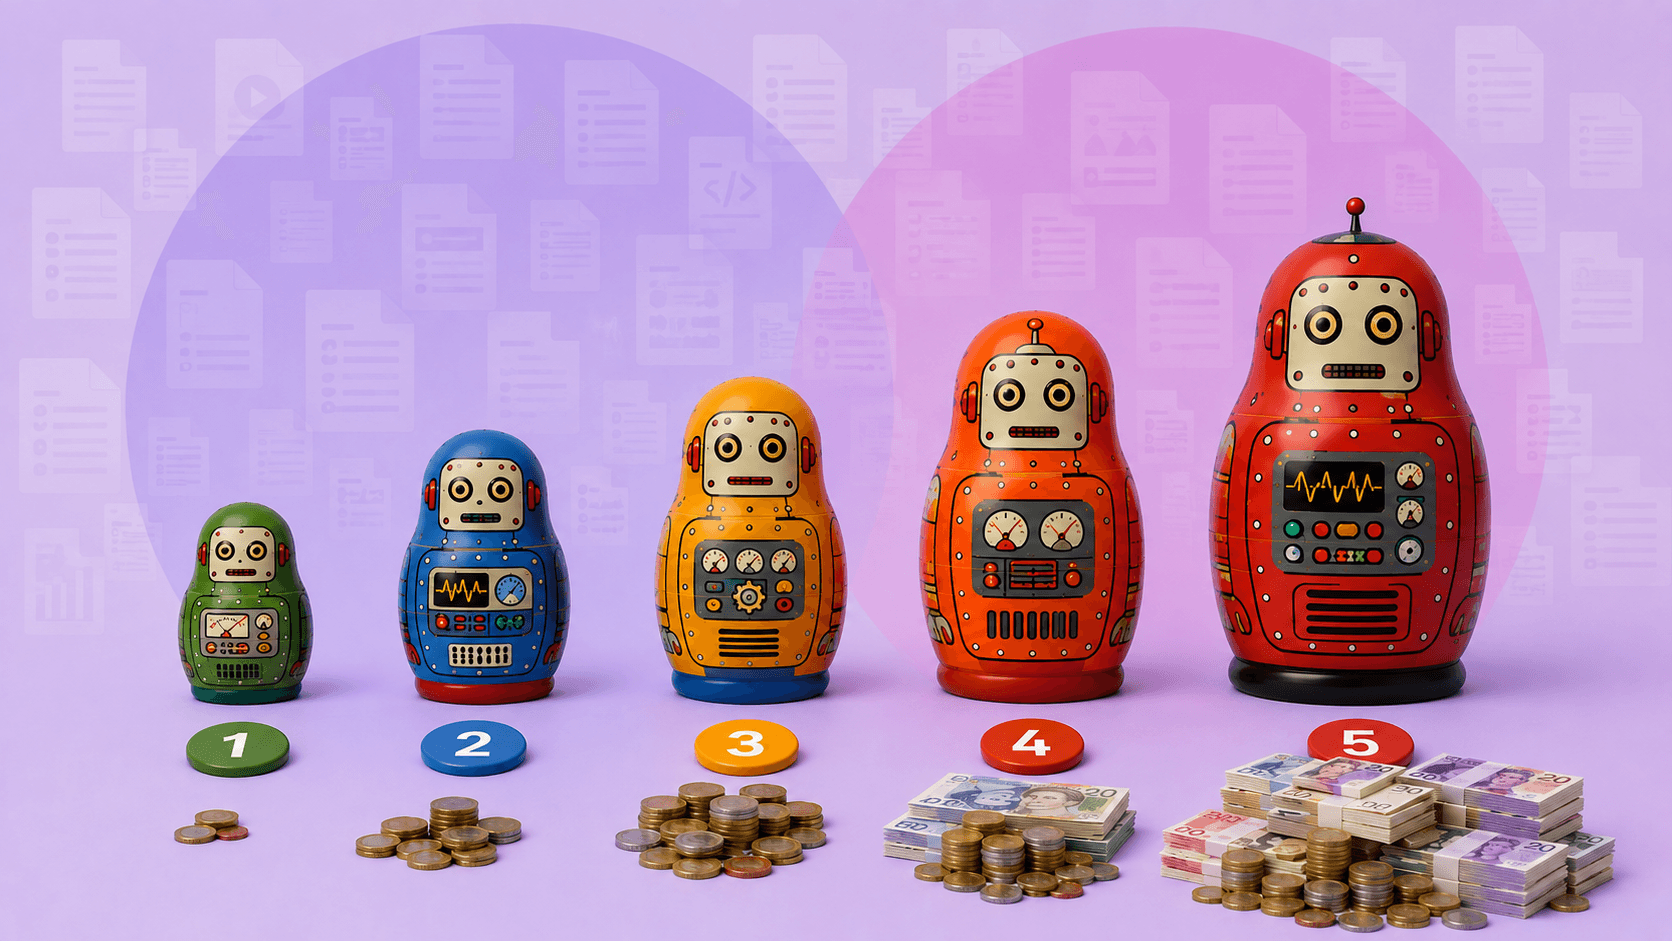
What web access actually costs - the tier picture
The barrier headlines sound extreme, but the cost data is more differentiated: 87.9% of top sites are Simple or Easy to access - and that means cost-effective.
The trouble with variants: Solving the web's infinite ecommerce explosion
Product variants can turn a straightforward ecommerce scraping project into millions of combinations. Learn how to classify, scope and control them.
Need for speed: How data inertia kills business ambition
Slow web data pipelines can hold back new markets, conversion gains and product launches.
The web's layered defences - how access barriers combine
Individual barriers may get the headlines, but it's stacked access control mechanisms that pose the biggest block.
The anti-ban arms race: Agentic traffic and the fight for the open web
As AI agents transform how we interact with the web, anti-bot systems threaten to fence off the digital open range.
TLS fingerprinting, the handshake that reveals your true intent
TLS fingerprinting fires before you have even asked for a page, and tells you nothing when it does. The least common barrier, and the hardest to diagnose.
JavaScript renders almost half of sites invisible
JavaScript renders 40.6% of top sites unreadable to a plain HTTP request, not by design but as a side effect of how the modern web is built.
Rate limiting is a roadblock, not a speed limit
Rate limiting sounds like a speed limit, but 93.7% of rate-limited sites block on the very first request. It is an identity check, not a throttle.
Introducing Zyte MCP: Powerful web data gathering for your agent
Zyte MCP brings live web access, structured extraction and Scrapy Cloud operations into coding agents such as Claude Code, Cursor and Codex.
CAPTCHA is more than just a puzzle piece
The famously awkward security mechanism has quietly become an invisible behavioral scoring system. Two vendors enable 89% of CAPTCHAs, and the smallest sites use it most.
Inside antibot, the arms race you can't see
Only 18.5% of top sites run dedicated antibot, but every one of them chose to. Why it's the most intentional barrier in the stack, and the strongest signal of a hardened site.
Firewalls run the web, just not on purpose
Web Application Firewalls run on 92.4% of the top websites, but most arrived bundled with a CDN and were never tuned to resist automated access.
More articles on Web data collection
- Spider monitoring made easy
- Data is the new water
- Brand visibility in the digital era: How web data help brands see the full picture
- How online retailers use web data to compete on price, promotion, and availability
- How web data turns e-commerce listings into retail intelligence
- Super-powers, toll booths and the new era of data collection
- Beyond text: Unlocking value on the multimedia web
- Sun, sea and code: What we built at Zyte’s API hackathon
- How to build a daily industry news digest
- Scraping a synthetic web: Dead Internet Theory meets web data extraction
- Partial autonomy, full control: Why we built Web Scraping Copilot
- Five key takeaways from Extract Summit 2025
- Introducing Web Scraping Copilot - A rocket boost for data extractors
- How to Plan Your Web Scraping Project Like a Product Manager
- 7 Myths About Web Scraping APIs – Busted
- When DaaS met SaaS - the new hybrid data economy
- Kill your product - why sacrificing your cash cow can be the path to growth
- From script to system: 10 building blocks to scale web scraping
- New in Zyte: Scroll Control, Lower Costs, and More
- Rise of the Data Vendor: How Outsourcing is Transforming Supply and Fuelling Businesses
- Quality, focus and scale: Three ways data outsourcing benefits businesses
- What’s your data type? Solving the procurement problem
- Why AI is changing the game for data buyers in 2025
- Buy or Build? The Four Roads to Acquiring Web Data
- Has Your Google Scraper Stopped Working? Here’s What You Need to Know
- Essential insights for developers to lead in 2025
- Best web scraping methods for JavaScript-heavy websites
- What is Web Data Harvesting? 1 key description will help you
- Web Scraping vs Data Mining | What's the Difference?
- Zyte Crawls The Deep Web