Zyte’s new AI-powered Automatic Extraction API for e-commerce & article extraction
Today, we’re delighted to announce the launch of the beta program for Zyte's new AI-powered Automatic Extraction API for automated product and article extraction.
After much development and refinement with alpha users, our team has refined this machine learning technology to the point that the data extraction engine is capable of automatically identifying common items on product and article web pages and extracting them without the need to develop and maintain individual web crawlers for each site.
Enabling developers to easily turn unstructured product and article pages into structured datasets at a scale, speed, and flexibility that is nearly impossible to achieve when manually developing spiders.
With the AI-enabled data extraction engine contained within the developer API, you now have the potential to extract product data from 100,000 e-commerce sites without having to write 100,000 custom spiders for each.
As result, today we’re delighted to announce the launch of the Zyte Automatic Extraction API's public beta.
Join the beta program today
If you are interested in e-commerce or media monitoring and would like to get early access to the Zyte Automatic Extraction API then be sure to sign up for the public beta program.
When you sign up for the beta program you will be issued an API key and documentation on how to use the API.
From there you are free to use the Zyte Automatic Extraction API for your own projects and retain ownership of the data you extracted when the beta program closes.
What's even better, the beta program is completely free. You will be assigned a daily/monthly request quota which you are free to consume as you wish.
The beta program will run until July 9th, so if you’d like to be involved then be sure to sign up today as places are limited.
How to use the API?
Once you’ve been approved to join the beta program and have received your API key, using the API is very straightforward.
Currently, the API has a single endpoint: https://developerapi.scrapinghub.com/v1/extract. A request is composed of one or more queries where each query contains a URL to extract from, and a page type that indicates what the extraction result should be (product or article).
Requests and responses are transmitted in JSON format over HTTPS. Authentication is performed using HTTP Basic Authentication where your API key is the username and the password is empty.
To make a request simply send a POST request to the API along with your API key, target URL, and pageType (either article or product):
1curl --verbose --user '[api key]':'' --header 'Content-Type: application/json' --data '[{"url": "https://blog.scrapinghub.com/gopro-study", "pageType": "article"}]' https://developerapi.scrapinghub.com/v1/extractOr, in Python:
1import requests response = requests.post('https://developerapi.scrapinghub.com/v1/extract', auth=('[api key]', ''), json=[{'url': 'https://blog.scrapinghub.com/gopro-study', 'pageType': 'article'}]) print(response.json())To facilitate query batching (see below) API responses are wrapped in a JSON array.
Here is an article from our blog that we want to extract structured data from:
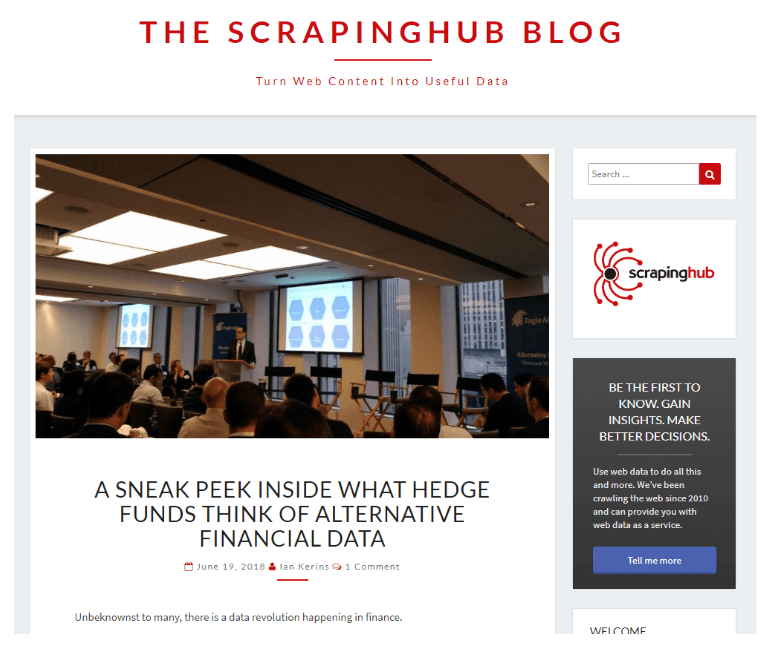
And the response from the article extraction API:
1[ { "article": { "articleBody": "Unbeknownst to many, there is a data revolution happening in finance.nnIn their never ending search for alpha hedge funds and investment banks are increasingly turning to new alternative sources of data to give them an informational edge over the market.nnOn the 31st May, Scrapinghub got ...", "articleBodyRaw": "<span id="hs_cos_wrapper_post_body"" class=""hs_cos_wrapper hs_cos_wrapper_meta_field hs_cos_wrapper_type_rich_text"" data-hs-cos-general-type=""meta_field"" data-hs-cos-type=""rich_text""><p><span>Unbeknownst to manyTry Automatic Extraction for free, or get in touch to discover custom data extraction solutions that work for your business.
Zyte Automatic Extraction, powered by AI, makes data extraction easy and fast. This way you get back quick and reliable data in a structured format.
As a result you can make better decisions on how you want to improve your products and services, and grow your business.