Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.

Tired of handling site bans? Learn how to automate it and free your time with Zyte API
Learn how to automate anti-bans and free your time with Zyte API.
The Art of Using Data to Make Decisions in Business
Flipping a coin, going with your gut, closing your eyes and begging the universe for guidance on how to proceed — these all have their place, sure. But using data to make decisions is a far more reliable approach in business.
Scrapy Cloud secrets: Hub Crawl Frontier and how to use it
Our scrapy cloud secrets help you deal with real cases that put your data extraction pipeline at risk. You have to be fully prepared for every scenario.
How Web Scraping and Graph Databases Can Power Recommendation Engines
I recently had the pleasure of participating in the third episode of Graphversation, a monthly live stream series that brings together graph experts and Neo4j enthusiasts for engaging and enlightening discussions about the captivating world of graphs.
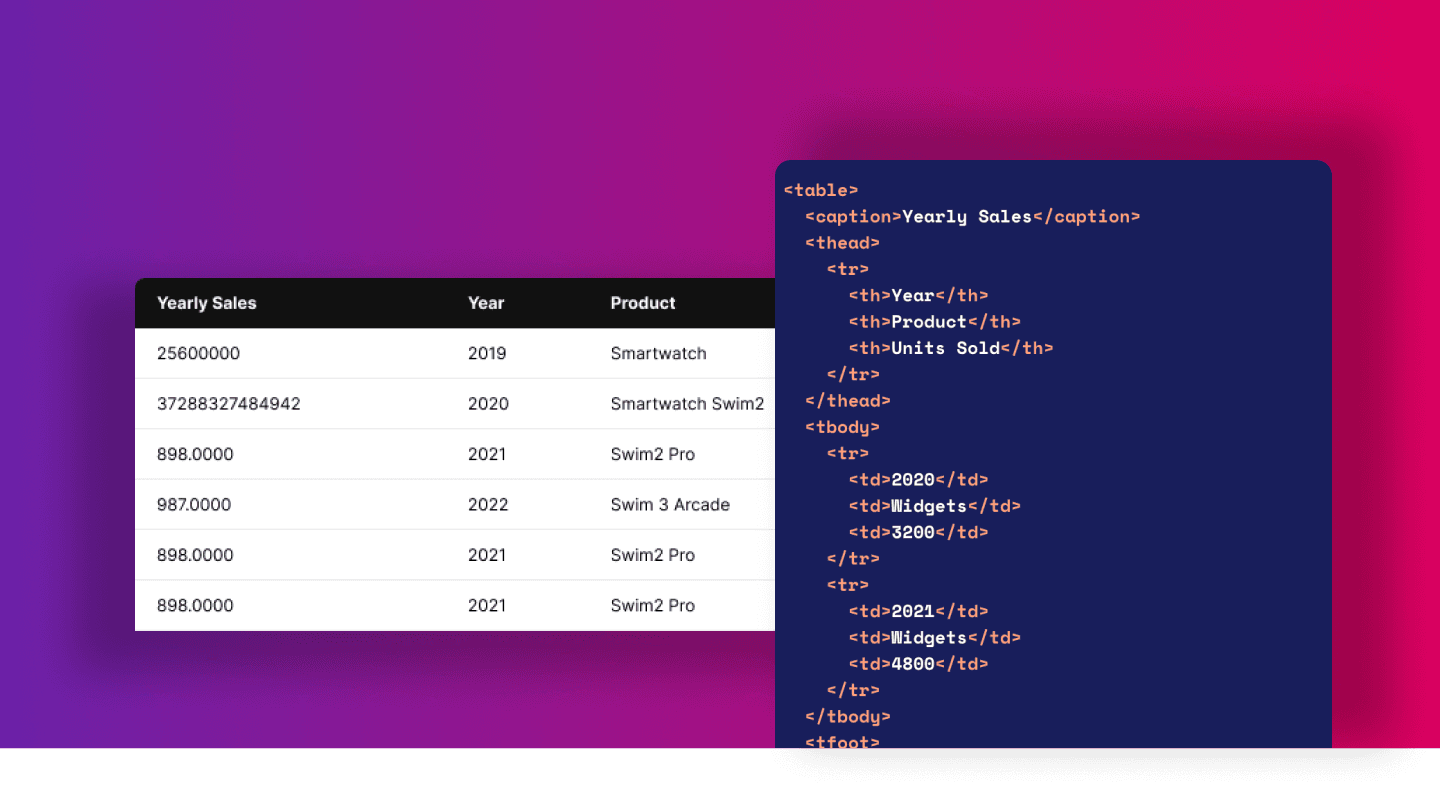
How to Extract Data From HTML Table
Learn how to extract data from a HTML table with step-by-step instructions. Get all the tips on extracting data from an HTML table in Python and Scrapy.
OnDemand: How to integrate Zyte data with +60 services, databases or APIs using YepCode
Learn how to use Zyte and YepCode together to quickly create automations and test new ideas.
Storing and Curating Your Web Crawling Data
Web crawlers are becoming increasingly popular in the era of big data, especially now with the advent of Large Language Models (LLMs) such as ChatGPT and LLaMA. The sheer amount of data that is publicly available from the web has a wide variety of applications including market research, sentiment analysis, and predictive modeling.
The Zyte Web Data Maturity Model
Learn more about Zyte's Web Data Maturity Model.
The complete guide to accessing web data - Webinar series
Join us to understand how Zyte’s proven Web Scraping Project Management framework can help your organization.
How to integrate Zyte data with +60 services, databases or APIs using YepCode
Learn how to integrate Zyte data with +60 services, databases or APIs using YepCode.
Navigating compliance, bans and maintenance to supercharge your web data extraction team
In this webinar learn navigating the compliance, bans and maintenance to supercharge your web data extraction team.
Residential proxies vs. data center proxies in web scraping
Learn the differences between residential proxies vs. data center proxies in web scraping.