Looking back at 2014
One year ago we were looking back at the great 2013 we had and realized we would have quite a big challenge in front of us in order to have as much growth as we had during last year. So here are some highlights of the things we’ve been up to during this year, let's see how well we did!
2014 was quite the travelling year for Zyte! We sponsored both the US PyCon in Montreal and the spanish PyCon in Zaragoza. We’ve also been to Codemotion in Madrid and PythonBrasil. We hope to hit the road during 2015 too, bringing some spider magic to even more cities!
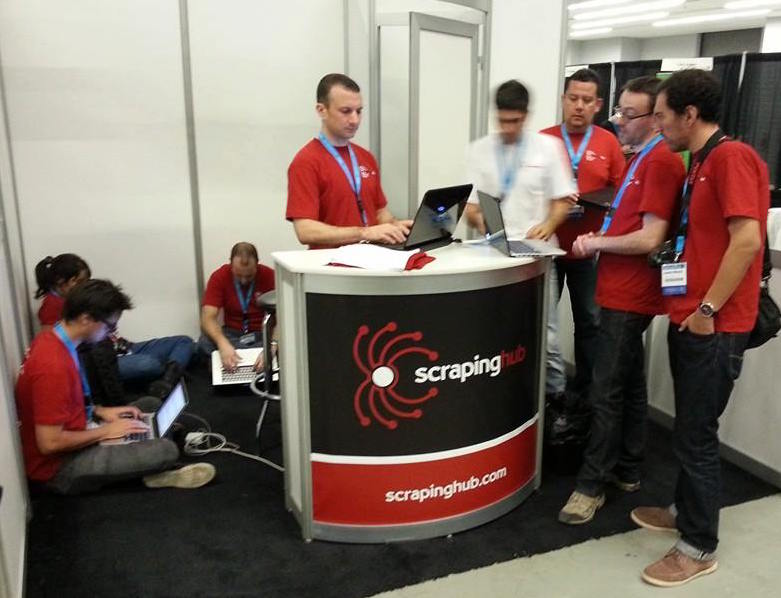 PyCon US Zyte booth
During this year we’ve also continued to work on both new and ongoing Professional Services projects for clients all around the world and we’re glad to see that our efforts are paying off, we have increased our customer base while maintaining the same quality standards we’ve had since we were just a few guys, back in 2010.
Our platform has grown too! There’s been steady effort in getting it to the point where we’ve been able to accommodate the ever increasing volume of scraping we and our customers have been doing. In 2014 alone Scrapy Cloud has scraped and stored data from over 10 billion pages (more than 5 times the amount we did in 2013!) and an extra 5 billion have passed through Smart Proxy Manager .
We are excited to see our revenue tripling from last year, and it makes us very proud to have grown organically so far. We can only imagine what we could do with some funding, but we won't do anything that could jeopardize the way we run the company, which has proven very successful.
Open Source
In the open source front, we’ve been spending a lot of time improving our annotation based scraping tool Portia. Our main focus has been on integrating it into our Scrapy cloud platform, and soon Zyte users will be able to open their Autoscraping projects in Portia. This will eventually be our successor to our Autoscraping tool. If you just cannot wait to try Portia you’re in luck, we open sourced it sometime ago (it was trending Python project on Github for a month!) so you can try it locally if you wish!
We also have a number of new and interesting open source projects: Dateparser, Crawl Frontier and Splash.
Dateparser is a parser for human readable dates/ which is able to detect and support multiple languages. It can even read text such as “2 weeks ago” and determine the date relative to the current time! The project already has over 300 stars and 17 forks on github.
Crawl frontier is a framework for building the frontier part of your web crawler, that’s the bit of a crawling system that decides the logic and policies to follow when a crawler is visiting websites such as what pages should be crawled next, priorities and ordering, how often pages are revisited, etc. Although originally designed for use with Scrapy, Crawl frontier can now be used with any other crawling framework or project you wish to use!
Splash is an API for JavaScript rendering. It’s currently our in-house solution for crawling Javascript powered websites, and we’re hopeful that usage will begin to grow outside of Zyte.
Of course, all our other existing open source projects such as Scrapy, webstruct and others have seen major improvements, something that will keep on going during 2015 and beyond.
We’re glad to be able to share all these experiences, numbers and new projects with you, but we know very well that behind every single one of those stands the hard work done by all members of our team, saying that this wouldn’t have been possible without them is an understatement. And the team has grown, 2014 marks the second year in a row that our team has doubled, we’re now 85 Zytans (formerly Zytebers)! (and we'll be over 90 by the end of January)
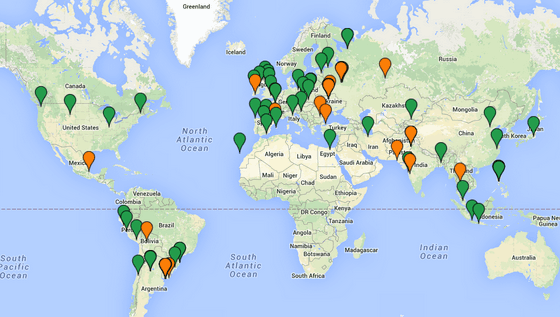
Green markers represent 2014 new hires. Click for an interactive map of our full team.
So here’s a sincere thank you from the Zyte (formerly Zyte) team to all of our customers and supporters. Thanks for an amazing 2014 and watch out 2015, here we come! Happy New Year!