Looking back at 2018
What a year 2018 has been for Zyte !!
It’s hard to know where to start…
This year has seen tremendous growth at Zyte , setting us up to have a great 2019.
Here are some of the highlights of 2018…
Data, data and more data
Data continues to be an important element of our customers business strategy and to support this we saw continued growth in the amount of data we help them extract from over 108.6 billion pages in 2018, an average of over 9 billion pages per month.
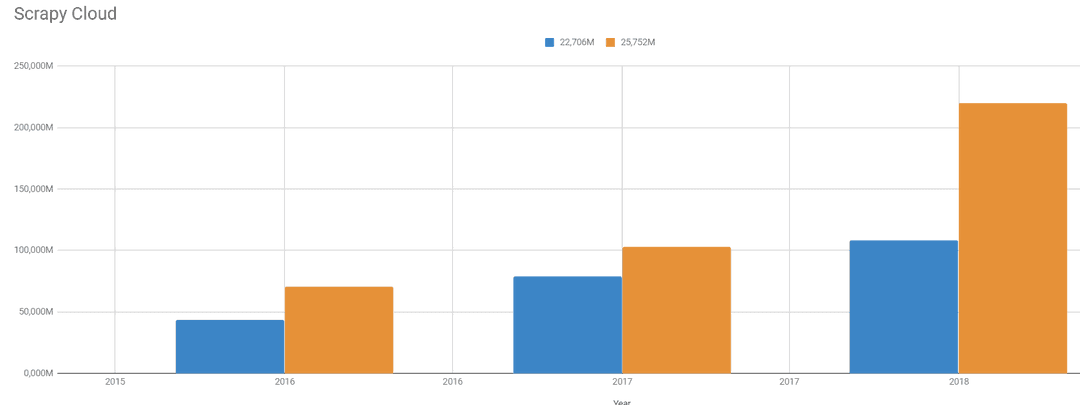
What is more, the number of items we extracted from those pages rose by 102% from 103 billion in 2017 to 209 billion in 2018. Signifying the growing appetite for every more new data types amongst our customers.
To deliver this level and scale of service for our customers we continued to invest heavily in our core technologies ensuring continued reliability and robustness of Scrapy Cloud and Smart Proxy Manager .
Scrapy Cloud - to deploy and run your web crawlers
Building on the improvements we made in 2017, we again focused on improving the technical capabilities of the platform to ensure the 1M Developers who rely on our tools can get the data they need.
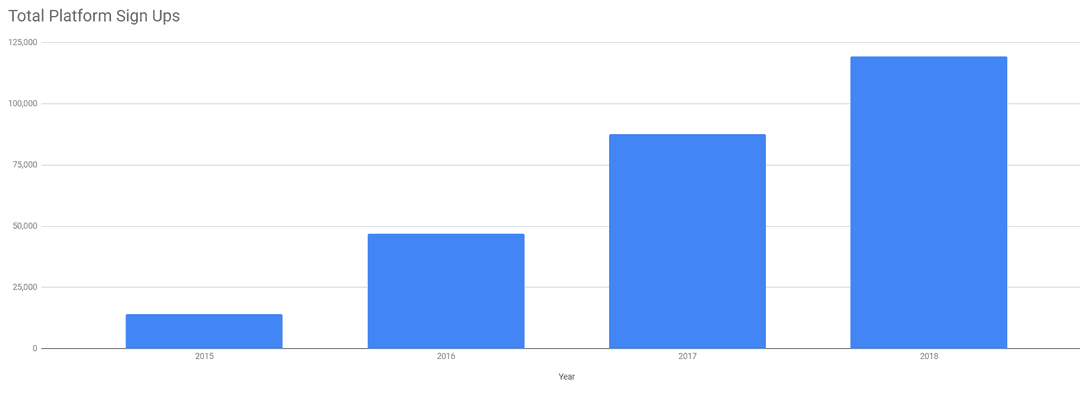
Putting this into numbers we saw another year of growth in the platform with nearly 120,000 developers signing up to use Scrapy Cloud.
What’s more behind the scenes we’ve been working on an overhaul of the platforms user interface which will be released in early 2019. We’re super excited!!!
Smart Proxy Manager
Smart Proxy Manager has gone from strength to strength in 2018. This year Smart Proxy Manager processed over 90 billion successful requests, up from 60.5 billion in 2017.
Zyte making waves
This year, Zytans (formerly Shubbers) were active as ever in the open source, remote working and developer communities.
Zyte participated in and were sponsors of the Running Remote conference in Bali and attended the Grow Remote conference in Ireland, along with attending numerous other remote working conferences and meetups.
Sanaea Daruwalla, Zyte's Head of Legal, was invited to speak at the annual IAPP Europe Data Protection Congress in Brussels, to share her legal insights on how to safely scrape the web in the era of data protection and GDPR.
And always, our developers were active participants and contributors to the open source community along with attending countless developer conferences and meetups throughout the year.
So many Zytans (formerly Shubbers)!!!
It seemed like not a week went by without us welcoming a new member to the team on Slack. Which is actually not an exaggeration, as over the course of 2018 the number of Shubbers has grown 47%.
An increase of 69 people, which is more than one per week. So it was no wonder it felt like we were welcoming new people to the team every day!
Meaning that we are positioned to support our ever growing customers base in 2019 and continue to advance the technologies for web scrapers around the world.
But doesn’t mean we’re planning on stopping here...
We are still looking to hire world-class people in all areas of our business, from developers and data scientists, to salespeople, marketers and support functions. So if you’re interested in working with one of the best remote working companies around then check out the open positions we’re hiring for at the moment.
Culture & team spirit
With such a fast growing fully distributed team, we continued our efforts to ensure our culture and company values were alive and well across the organisation.
We re-launched our values after much collaboration and input from fellow Shubbers, expanded our Shubber praise and recognition programme, created cross functional teams to support global collaboration within a remote environment, set up the Shubber Voice to allow people to voice their ideas for the company, and WaterCooler channels to enable Shubbers to talk and gossip whilst being thousands of kilometres apart.
But no year is complete without our signature Shubber GetTogethers…
{% video_player "embed_player" overrideable=False, type='scriptV4', hide_playlist=True, viral_sharing=False, embed_button=False, width='1920', height='1080', player_id='6848504722', style='' %}
This November 120 Shubbers travelled from all over the world to Lisbon to meet up, make new friends and discuss the company direction.
We held a two-day Town Hall where every Scrapinghub team got a chance to share the progress they’ve made over the last year and their plans for the coming year.
And of course, it wasn’t all work and no play. There was plenty of time for workshops and team bonding to strengthen the Scrapinghub team.
Senior leadership
2018 was the year we completed our senior leadership team, putting experienced leaders in charge of each aspect of Scrapinghub’s key areas. Our leadership team is:
And we welcomed...
- Oonagh Killeen, as Head of Finance
- Sanaea Daruwalla, as Head of Legal
- Suzanne Hassett, as Head of Professional Services
- Marie Moynihan, as Head of Marketing
Ensuring we have a 50/50 gender split amongst our Senior Leadership team. All in all, having our SLT in place gives Zyte a solid foundation to grow and expand in the years to come.
Looking ahead to 2019
With the ever-increasing use of big data and artificial intelligence by the world’s leading companies there is a huge appetite for reliable sources of high-quality web data, so 2019 is shaping up to be a great year for Zyte .
Not only that, we also have numerous new products and product enhancements in the works that will increase our capabilities and ensure we can better serve our customers in 2019.
If you’d like to be part of this journey then we’re Hiring, so see if any of our open roles takes your fancy. Until next year...Happy Scraping!