Looking back at 2019
2019 was an exciting year for Zyte . We created things we have never created before and did things nobody in our industry had ever done before. Let’s revisit what happened in 2019!
The first-ever web data Extraction Summit
We organized the first industry event focused on Web Data Extraction in Dublin, Ireland. With more than 140 attendees, 16 speakers covering topics from technical deep dives to business use cases, 12 presentations, a customer panel discussion, and unlimited Guinness. It was an absolute success.
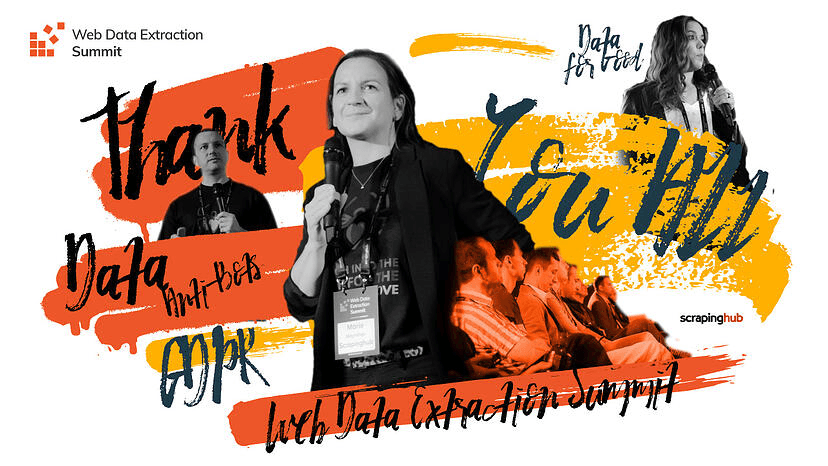
It was an awesome event. We loved it and the people who attended loved it, with 94% of attendees giving it an overall rating of Excellent/Good. So we are going to do it again! We’re going to make sure Extract Summit 2020 is going to be even bigger and better. Watch out for our call for speakers which we will launch in February.
Shaping the future of web scraping
We launched Automatic Extraction API our AI-enabled automatic web scraping Product. At the core of the Automatic Extraction is an AI-enabled data extraction engine able to extract data from a web page without the need to design custom code. Through the use of deep learning, computer vision, and Smart Proxy Manager , Zyte's advanced proxy management solution, the data engine is able to automatically identify common items on product and article web pages and extract them without the need to develop and maintain extraction rules for each site.
Other verticals will be added to the API in the coming months such as job postings, real estate, automotive, product reviews, blogs and discussions, to name a few, will be among the verticals that we plan to roll out in 2020. It’s going to be exciting! We are always looking for Beta customers to join so get in touch if you’re interested in any of the verticals mentioned above.
Zyte Smart Proxy Manager
2019 was a big year for Zyte Smart Proxy Manager . We made huge advancements on the backend side of things, improving reliability and robustness. The success rate Zyte Smart Proxy Manager provides is unmatched in the industry but still, we found ways to make it stronger and more powerful to provide our customers with the best web scraping proxy solution in the market.
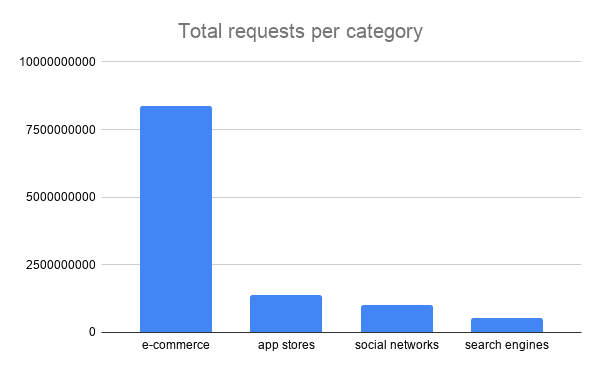
Looking at the type of successful requests our Zyte Smart Proxy Manager customers rely on us for, a huge portion of the requests are eCommerce websites followed by app stores, social networks, and search engines. E-Commerce web data extraction for price intelligence was one of the top solutions requested by customers in 2019.
Open source
Open source is something we believe in and put a lot of effort into last year. In 2019, we open-sourced two libraries to help Scrapy developers scrape the web. Spidermon is a Scrapy extension to monitor your spiders, get statistics, notifications and validate data. Arche is a tool for verifying scraped data. These two repositories together got 264 stars on GitHub.
EY Entrepreneur of the year
Shane Evans our CEO made us all extremely proud when he was nominated for EY Entrepreneur of the year, Ireland. This is a unique global program that recognizes entrepreneurial achievement among individuals and companies that demonstrate vision, leadership, and success - and work to improve the quality of life in their communities, countries, and around the world. You can read about his story in an interview with the Irish Times.
{% video_player "embed_player" overrideable=False, type='scriptV4', hide_playlist=True, viral_sharing=False, embed_button=False, width='1920', height='1080', player_id='25059995550', style='' %}
Events
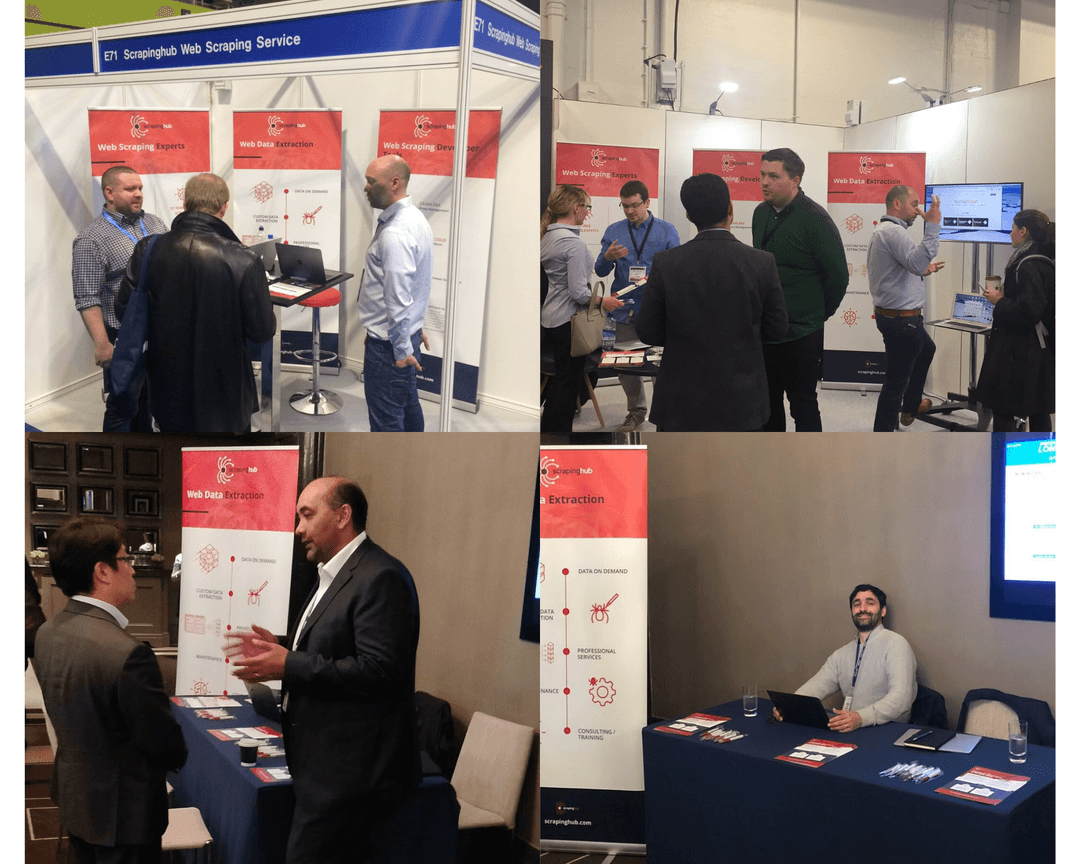
Other than holding our own event, last year we also visited Battlefin, the Internet Retailing Expo (IRX), and the AI and Big Data Expo, in London. It is always great to spread the word of the power of web scraping and show people what it can do for them.
Remote working and team meetups
We love remote working. It’s in our DNA. In 2019 we got involved with initiatives such as GrowRemote and RunningRemote to help educate others on how to run a successful remote-first company. Our Head of Marketing, Marie Moynihan was invited to speak on national radio on The Home Show with Sinead Ryan to chat about what it’s like to work remotely. It’s a great podcast episode, you can listen to it here.
Team meetups
 As a fully remote company, it’s important to find the time and place to get together and meet each other in person. This year we decided to run regional team meetups instead of a larger company retreat. The meetups were a great success and allowed functional teams to co-working time together and the ability to get that all-important face-time together as a team and of course have some fun. Meetups were held in Dublin, Montevideo, Madrid, and Kuala Lumpur.
Looking forward to 2020
We have ambitious goals for the year and this year is going to be exciting!. We are seeing increasing demand plus new use cases for web data and are excited to continue to provide solutions to our current and future customers. We will also be celebrating our 10 year anniversary!
If you would like to be part of our journey, have a look at our open roles. If you want to know how web extracted data can help your business, contact us for a free consultation. In 2020, let’s grow together