Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
The 2025 Web Scraping Industry Report - Industry Players
This report helps business leaders and data buyers validate ROI from purchased data by aligning decisions with their stage in the data journey—exploration, discovery, or definition.
The 2025 Web Scraping Industry Report - Business Leaders
This report explores how industry players can balance ethical compliance and operational excellence to build trust and achieve sustainable growth in the AI era.
Inside Zyte's System Design Process: How We Build Scalable, Reliable Solutions
Explore Zyte’s approach to building scalable and reliable systems through PRDs, technical requirements, solution evaluation, and real-world design insights.
A Deep Dive into Zyte's Open-Source Libraries
Discover how Zyte’s open-source libraries like ClearHTML, Extruct, Chomp.js, and more simplify web data extraction and processing.
Analyze web data quickly with Jupyter Notebooks and Zyte API
With AI Scraping in Zyte API, you can pull data from any e-commerce website straight into your Jupyter notebooks.

Advanced session management with Scrapy
Master advanced session management with Scrapy-Zyte-API. Learn techniques to optimize efficiency, streamline workflows, and gain full control over your web scraping processes.
Building a Web Crawler in Python
Learn to build a Python web crawler using libraries like BeautifulSoup, Requests, Scrapy, and Selenium.
Overcoming web scraping challenges of Puppeteer and Playwright
Explore issues like browser farm management, IP rotation, and anti-scraping measures that can complicate large-scale operations.

JSON Parsing with Python [Practical Guide]
Learn how to parse JSON data with Python. This guide covers libraries, methods, and advanced tools like JMESPath and ChompJS.
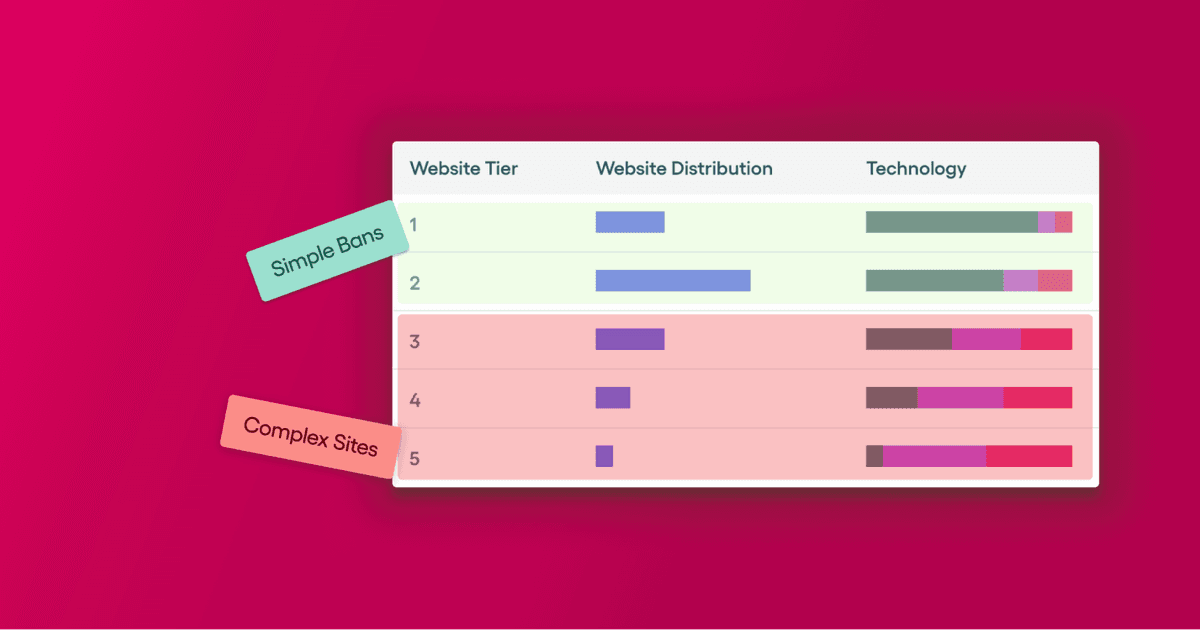
Designing a fair and predictable pricing model for Web Scraping APIs
Discover how Zyte practices performance-based pricing and a customer-first approach to reshape web data extraction services.

Exploring Customer-Centric Pricing in Web Scraping APIs: A Fireside Chat
Discover how Zyte’s leaders envision performance-based pricing and a customer-first approach reshaping web data extraction services.
Using Data Extraction Tools for Efficient Website Scraping
Using data extraction tools makes web scraping challenges possible to overcome. Explore more in this article.