Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
A Deep Dive into Zyte's Open-Source Libraries
Discover how Zyte’s open-source libraries like ClearHTML, Extruct, Chomp.js, and more simplify web data extraction and processing.
Analyze web data quickly with Jupyter Notebooks and Zyte API
With AI Scraping in Zyte API, you can pull data from any e-commerce website straight into your Jupyter notebooks.

Advanced session management with Scrapy
Master advanced session management with Scrapy-Zyte-API. Learn techniques to optimize efficiency, streamline workflows, and gain full control over your web scraping processes.
Building a Web Crawler in Python
Learn to build a Python web crawler using libraries like BeautifulSoup, Requests, Scrapy, and Selenium.
Overcoming web scraping challenges of Puppeteer and Playwright
Explore issues like browser farm management, IP rotation, and anti-scraping measures that can complicate large-scale operations.
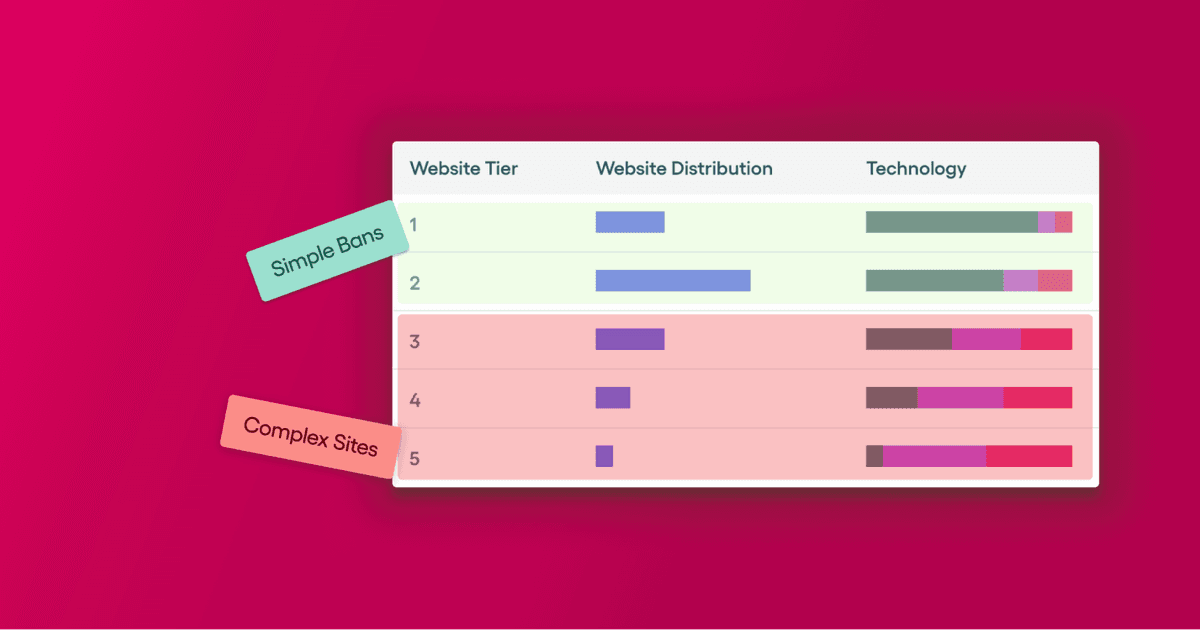
Designing a fair and predictable pricing model for Web Scraping APIs
Discover how Zyte practices performance-based pricing and a customer-first approach to reshape web data extraction services.

Exploring Customer-Centric Pricing in Web Scraping APIs: A Fireside Chat
Discover how Zyte’s leaders envision performance-based pricing and a customer-first approach reshaping web data extraction services.
Using Data Extraction Tools for Efficient Website Scraping
Using data extraction tools makes web scraping challenges possible to overcome. Explore more in this article.
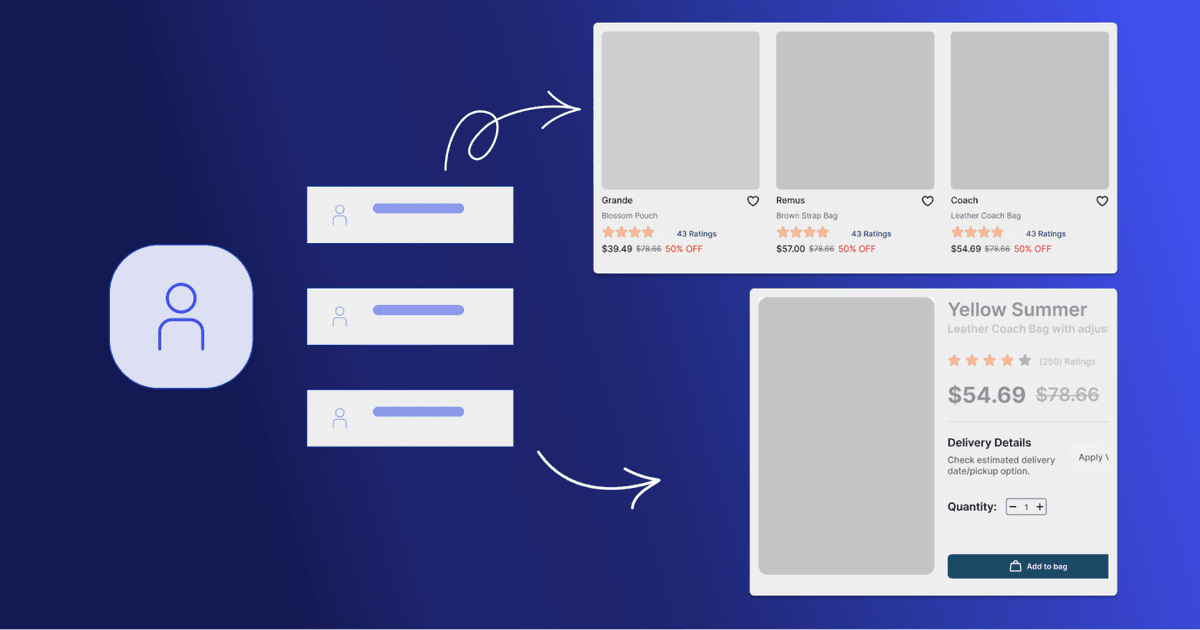
How Session Management Minimizes Bans and Enhances Data Quality in Web Scraping
Learn how managing user sessions in web scraping can help overcome website bans, handle IP rate limits, streamline cookie management, and avoid detection.

Efficient Web Scraping with LLMs
In this hands-on workshop hosted by Iván Sánchez, you'll learn how to harness the incredible power of Large Language Models (LLMs) to tackle your toughest scraping challenges.

No wait, no upfront costs: How Zyte transformed its data delivery business with AI
Zyte has just launched a service that reshapes how businesses source web data feeds. With zero setup fees and a scalable, on-demand model, companies can now add data sources from any website without traditional wait times or high upfront costs.

How to Simplify and Reduce Costs with Web Scraping APIs
Discover how Web Scraping API reduces infrastructure costs and automates resource allocation for efficient, scalable web scraping.