Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
Scaling and Maintaining Crawling and Extracting Solutions
A robust, responsive and reliable web scraping tech stack is key to scaling.

How to eliminate setup and maintenance on your headless browser fleet for web scraping
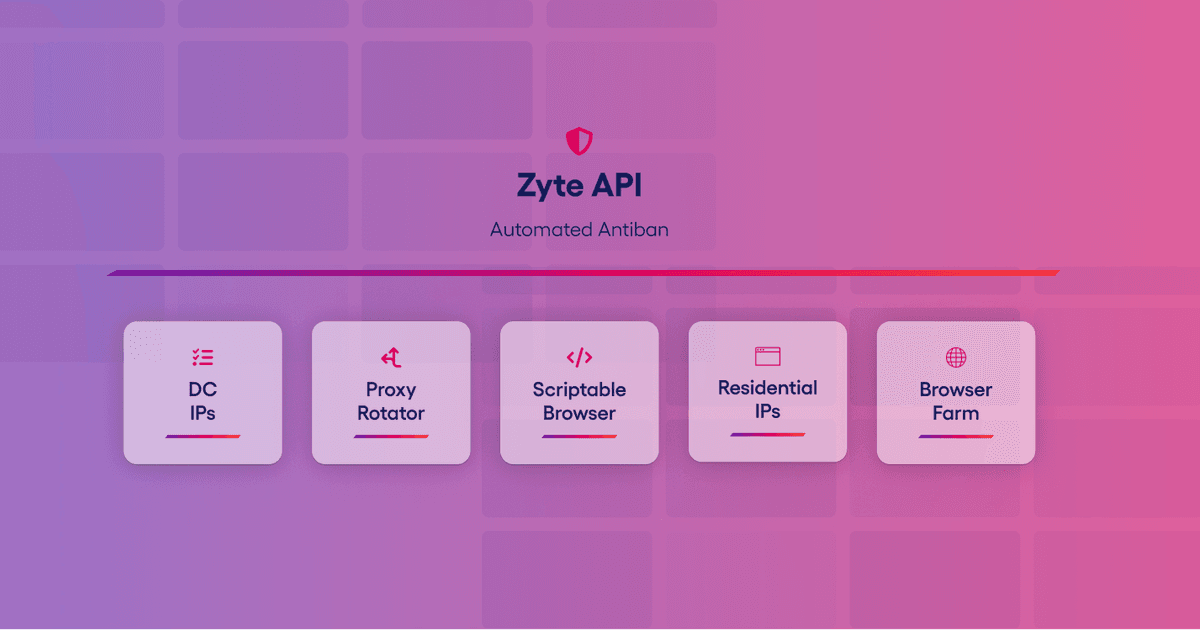
From Data to Decisions: Transforming Digital Shelf Analytics with Zyte API
Maximize DSA with Zyte API Web Scraping: Leverage Zyte API's advanced web scraping technology for your DSA needs. Extract precise, scalable data for product positioning, pricing strategies, and market trends analysis. Stay ahead with our legally compliant, flexible, and cost-effective solutions.
Use Powerful Ban Management With Zyte API’s Scripting API
You encounter so many different anti-bot systems as a developer working on custom projects for Zyte Data clients. This cat and mouse game requires your time, persistence and deep knowledge of web scraping.
Scrape from anywhere with Geolocation settings
Use geolocalized requests in Zyte API and increase your data quality and success rates, while keeping costs under control
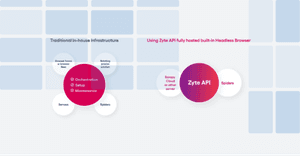
The Most Complete Headless Browser for Web Scraping
Replace all your headless browsers and proxies with one single tool that will save you time, money and yield better results for web scraping.
The trade-offs in crawling infrastructure in the modern anti-bot landscape
Insights on web scraping challenges in the anti-bot landscape and strategies for balancing cost, speed, and success.

Using Page Objects for Web Data Extraction

Inside Zyte's playbook for tackling complex web data extraction challenges
What is Web Data Harvesting? 1 key description will help you
Web data harvesting collects structured web data in an automated fashion. It is extremely simple and works by through 2 parts - a web crawler and a web scraper.
Global Retailer Enlists Zyte for Data-Driven, AI-Powered Pricing Intelligence
Is Web & Data Scraping Legally Allowed?
Is Web & Data Scraping Legal? Discover essential legal considerations for web scraping. Ensure compliance before starting your web scraping journey.