Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
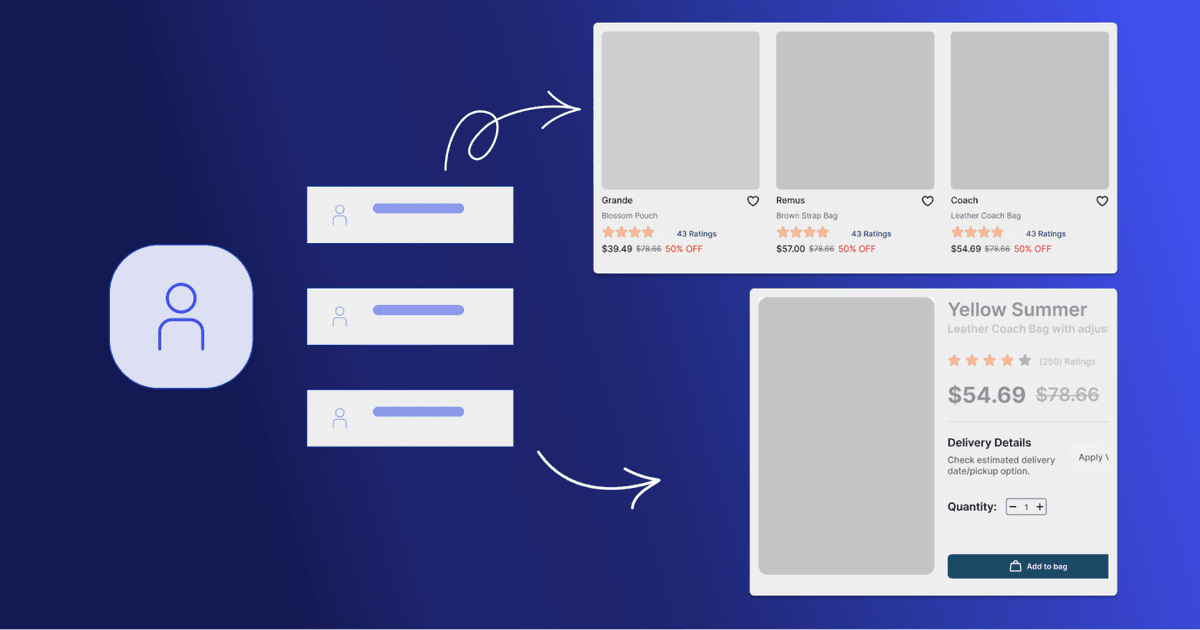
Why are Sessions Crucial in Web Data Extraction?
Sessions help maintain state, handle cookies, boost efficiency, and bypass anti-scraping measures, making your web scraping projects more robust and effective.
Static vs Rotating Proxies: A Comprehensive Guide
The decision between static and rotating proxies can significantly impact your success rates in data extraction activities.
Guide to Web Scraping APIs: Key Features and Benefits
A web scraping API is a full-stack tool designed to automate the collection of data from websites, from managing proxies to extracting data.

Mastering data extraction from complex websites with web scraping APIs
Let's explore the most common types of complex and dynamic content and when web scraping APIs fit well.
Seamlessly Transition from Zenrows to Zyte API
If you're currently using Zenrows, we understand the importance of a smooth transition to a new platform. That's why we are here to help you migrate seamlessly to Zyte API.

Zyte: Transforming AI web scraping for Digital Shelf companies
Let's explore why Zyte API has become the go-to solution for businesses seeking high-quality data.

The Power of Web Data for the Food Delivery Sector
A Guide to Web Scraping With Java
Java is a robust and versatile language that is well-suited for building modern web scraping systems.

Web scraping APIs — what they are and how they're revolutionizing data collection
4 essential Scrapy plugins for building efficient and effective spiders
Here are four essential Scrapy plugins we use to build efficient web crawlers for our customers.

Past, present and future of session management
