Large Language Models (LLMs)
Articles from the Zyte blog about Large Language Models (LLMs).

Four in 10 sites block AI bots with robots.txt
Nearly four in 10 of the world's top sites are now closed to well-behaved AI crawlers. Here's what operators actually do with robots.txt, and which AI agents they block or welcome.
Claude Fable 5 is the new best model for writing scrapers
We ran nine models, including the new GPT-5.6, through our Zyte Scraping Code Benchmark. Claude Fable 5 puts Sol and others in the shade - but it’s pricey, and the best extraction code still depends on the best infrastructure.
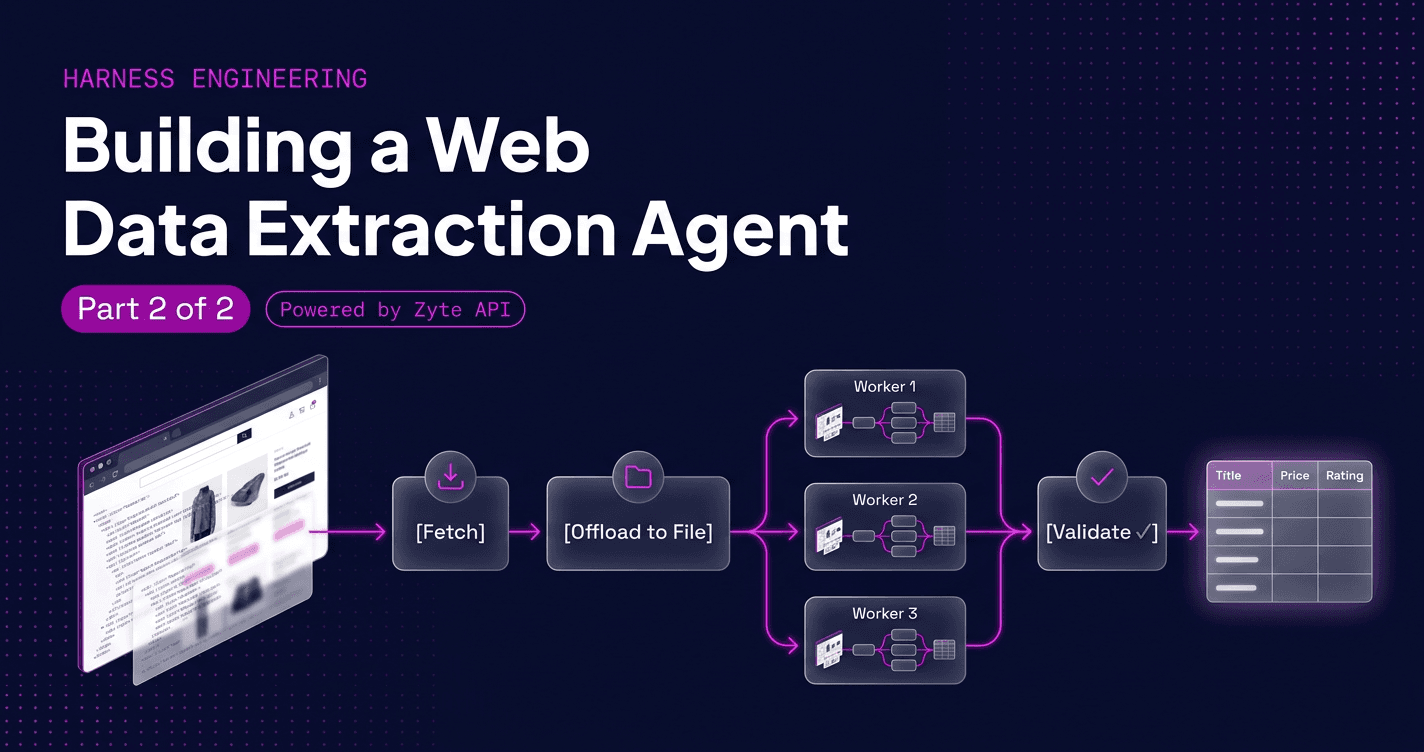
Harness Engineering, part 2: harnessing a data extraction agent
Point it at a website, tell it which fields you want, get back clean structured records. That's the agent we're designing in this post — and the interesting part isn't the model, it's the harness decisions that make it actually reliable at scale.
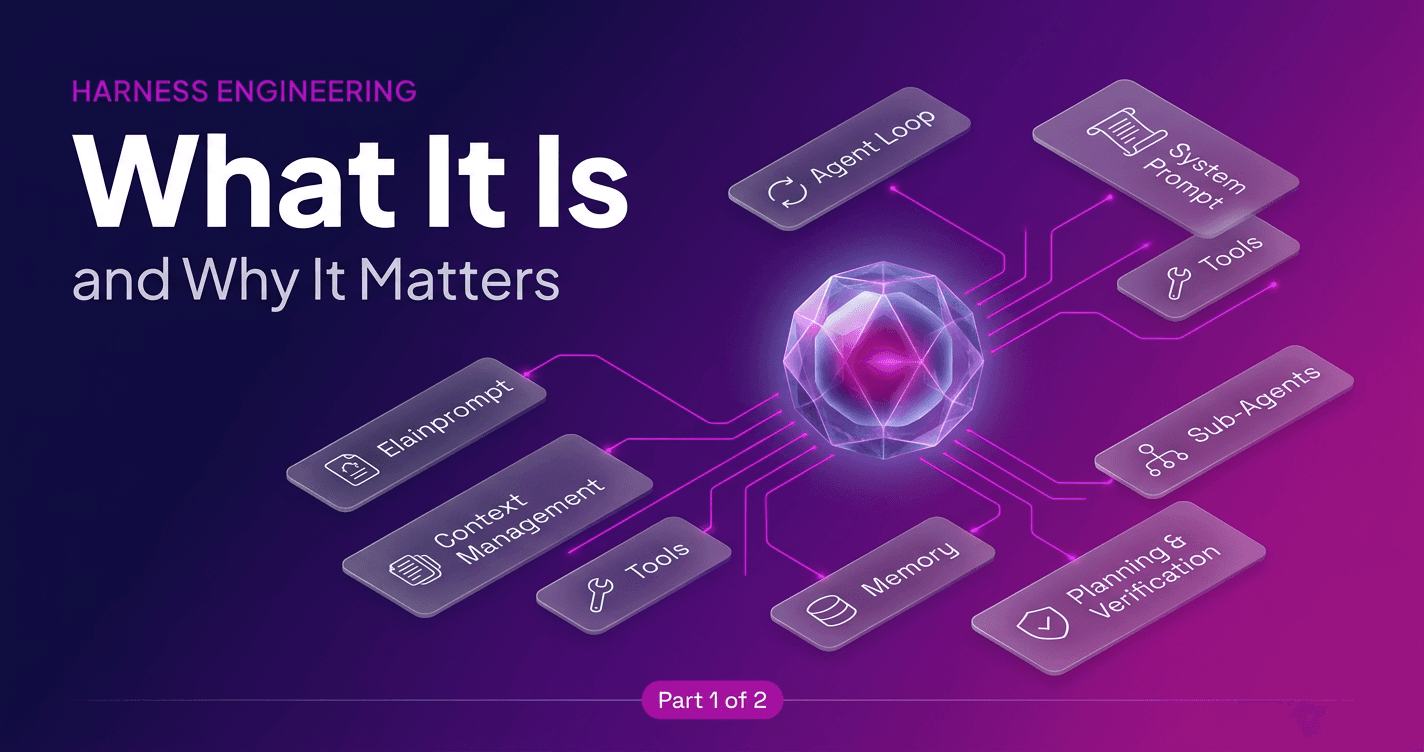
Harness Engineering, part 1: what is an agent harness and why it matters
Same model, same weights, zero retraining — LangChain changed nothing but the scaffolding around a coding model and jumped it from 30th place to the top five on a benchmark. That scaffolding has a name: the harness. And it's the part you actually control.
The harness matters more than the model - Podcast EP07
"The model is the engine — but the harness is everything else." In Episode 7, we dig into why the infrastructure layer around your AI model matters more than the model itself, rank the best models available right now, and ask whether the open-weighted revolution is about to make frontier subscriptions obsolete.
The best agent skill is the one that says the least
More instruction, worse output. Zyte's head of R&D on why telling your agent exactly what to do can blind it to the obvious answer.
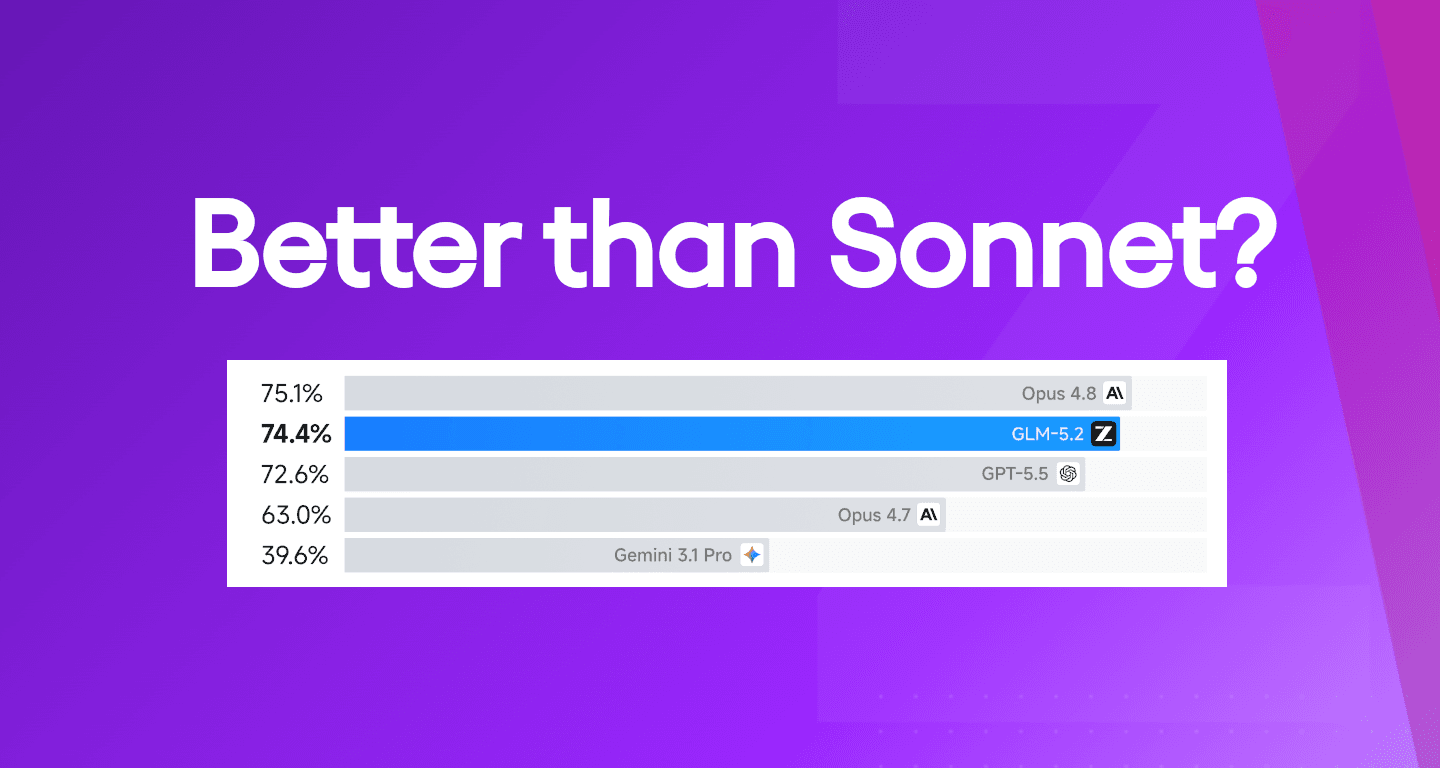
Why I'm adding GLM-5.2 to my agentic coding arsenal
Is GLM-5.2 really closing the gap to Anthropic - and at just a fraction of the cost - or is it just more AI hype? I think so, and let me show you why.
My personal agent setup: the architecture that runs my household and my DevRel work
"Four people, four diets, two work schedules, and a baby who answers to nobody. That's what finally made me build a personal agent." A walkthrough of the actual architecture I run to hold my household and my DevRel work together — profiles, skills, memory, and the web-data layer that makes it all reach the live web.
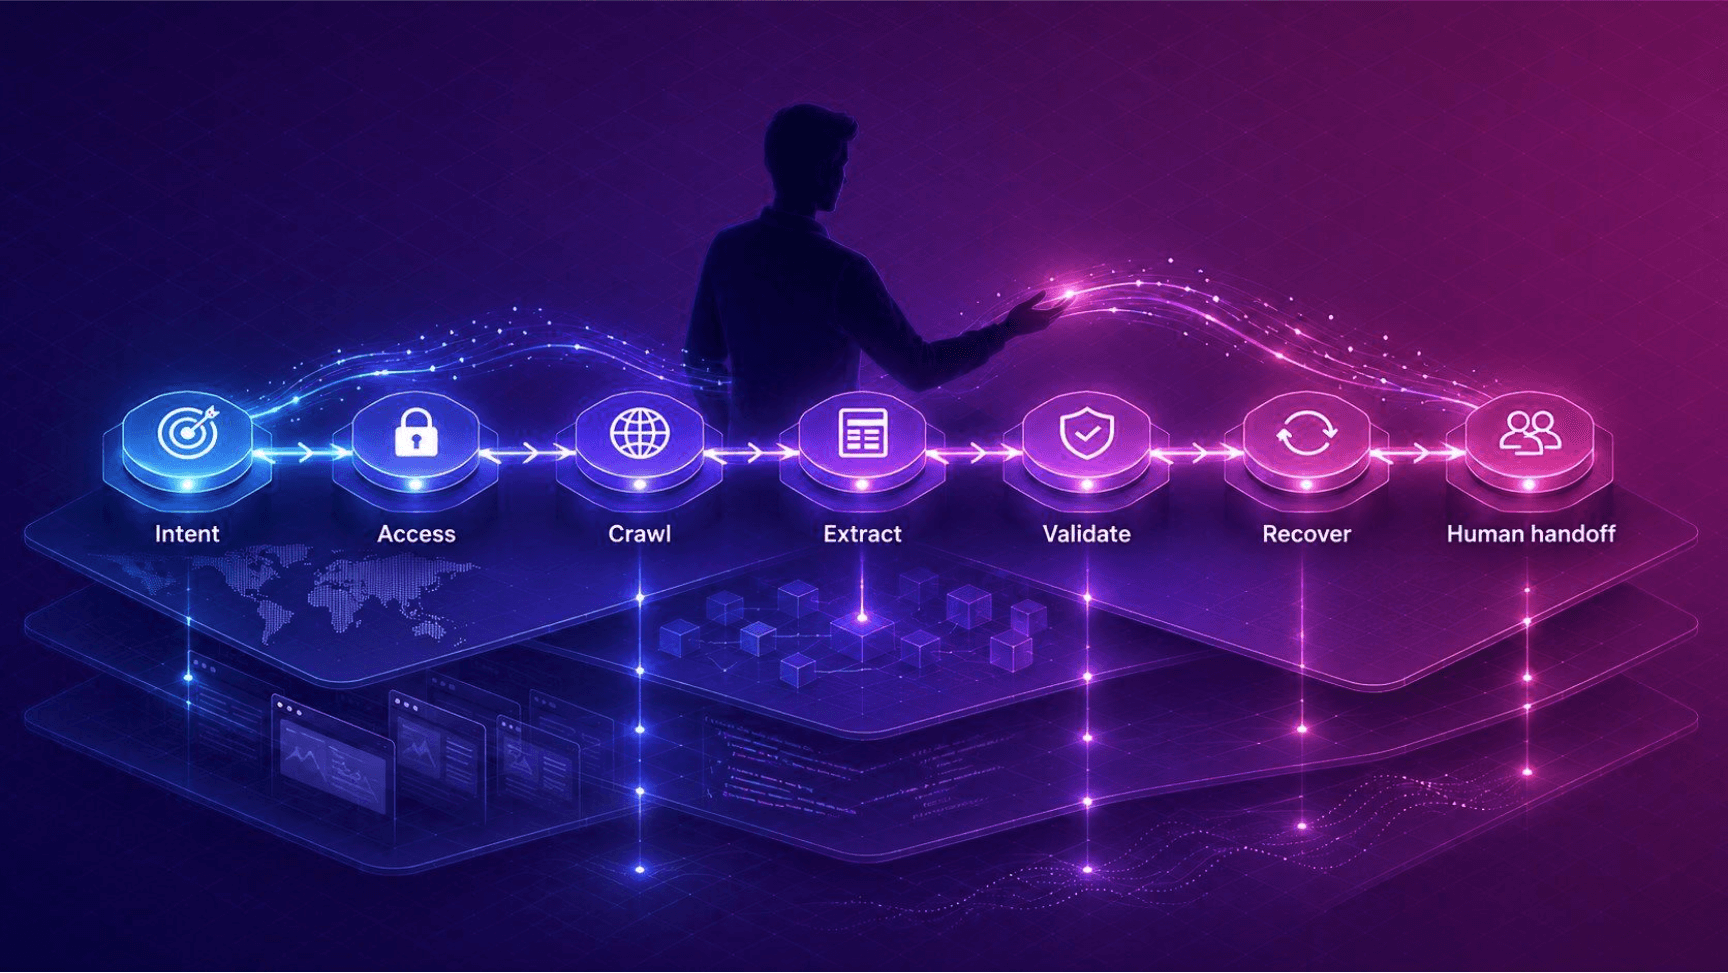
What's becoming of web scraping developers in the age of AI agents?
AI agents can generate code, suggest selectors, and draft crawl logic. What they can't do is design the system that decides when to stop, what to trust, and how to recover when the web pushes back. That job still belongs to a human.
Four sweet spots for AI in web scraping
Discover how AI and LLMs are enhancing web scraping with smarter crawling, fuzzy data extraction, automated spider generation, and intelligent QA.
What AI Builders Need to Know About the Training Data Copyright Debate
The generative AI gold rush is upon us, with astounding new products and capabilities that are fuelled by web data and raising questions about AI copyright.

Data on command: The natural-language web scraping revolution
Unlock the future of web scraping with natural language—making data extraction faster, easier, and accessible to all.