PINGDOM_CHECK
ArticleInsight and analysisDeveloper interest

Web Data Extraction Summit 2020: Empowering Data-Driven Decisions

Web Data Extraction Summit 2020 - Relive the highlights of the Web Data Extraction Summit 2020, where industry leaders shared insights into cutting-edge web data extraction techniques.

Himanshi Bhatt

3 min read ·

Web Data Extraction Summit 2020: Empowering Data-Driven Decisions

Announcing the Web Data Extraction Summit 2020

Web data extraction has become one of the most important tools for businesses to grow and stay ahead of the competition. From developing better pricing strategies to identifying hidden risks and building better products, web data extraction provides the power to transform infinite web data into a structured format that can help you make profitable decisions.

However, as the number of websites continues to grow, data extraction has become increasingly complex. Constantly changing website structures, antibot practices and scaling requirements add to the difficulty.

To overcome the ever-increasing challenges, the web data extraction industry has gone through impressive innovations and transformations in recent years that enable extracting accurate data in an efficient manner. During this revolutionary time in the industry, we are delighted to announce that Zyte will be once again hosting the Web Data Extraction Summit this year on Tuesday, November 10th, 2020.

This year, however, things will be a little different. Given we are living in strange times, this year the Extract Summit is going to be a completely free-to-attend and virtual event making it accessible for data enthusiasts all over the world to network and learn from each other! All you need is a laptop or a phone to get instant access to lots of amazing talks and connect with hundreds of other data lovers like you.
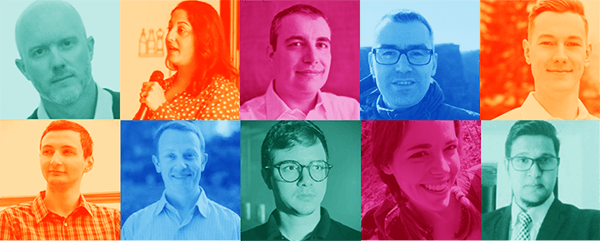
Extract Summit 2020 Speakers

Inspired by the great success of some of the talks during the Web Data Extraction Summit 2019 and feedback from attendees, we are planning a fantastic lineup of speakers this year. Sessions will include talks ranging from basic approaches to scrape to advanced level use of AI and machine learning in data extraction. Along with use cases on how companies from different industries use web extracted data and follow-up sessions on some interesting topics covered last year such as tackling antibots. Our Data Scientists and Product Engineers will also give you a sneak peek of some of the most cutting edge technologies in the web data extraction industry. 

The stellar line-up will share their expert knowledge on topics like Running a Business on Web Scraped Data,  How Venture Capital Firms use Web Data to find Billion-Dollar Companies, and How to Build Your Own Price Monitoring Tool. Along with panels on Legal Compliance in the World of Web Scraping and Cutting Edge Ways to Tackle Anti-Bot Challenges. 

With the range of topics covering everything from advanced-technical discussions to business know-how, at the Extract Summit, there is something for everyone. You can view the agenda here, and stay tuned as more talks are announced!

Don’t miss out on the chance to be amidst hundreds of data lovers and hear from some of the leaders and pioneers of the web scraping and data extraction industry.

Oh, and did we mention it's completely free! 

We will be announcing more talks are we get closer to November 10th, along with some exciting competitions very soon, so make sure you follow us on social media to stay updated!

                                                                   iconmonstr-twitter-3-240               iconmonstr-facebook-3-240                iconmonstr-linkedin-3-240

Try Zyte API

Build your first scraper in minutes

Free trial, no credit card. From a single request to production in an afternoon.

Get started

Continue reading

The harness matters more than the model - Podcast EP07
AI-assisted data extraction

The harness matters more than the model - Podcast EP07

"The model is the engine — but the harness is everything else." In Episode 7, we dig into why the infrastructure layer around your AI model matters more than the model itself, rank the best models available right now, and ask whether the open-weighted revolution is about to make frontier subscriptions obsolete.

John Rooney11 min read
How to build your first Scrapy extension
Developer interest

How to build your first Scrapy extension

My Scrapy project now plays a triumphant fanfare when a crawl finishes clean and a sad trombone when it doesn't, which is also how I finally learned what Scrapy's extension points are actually for.

Ayan Pahwa11 min read
Now what exactly is loop engineering? And where do Anthropic's Fable 5 model and web scraping fit in?
Developer interest

Now what exactly is loop engineering? And where do Anthropic's Fable 5 model and web scraping fit in?

A viral clip from Claude Code's creator put a name to something a lot of us have been circling: loop engineering. Here's why web scraping may be its best-fit domain — and what that means in practice.

Ayan Pahwa12 min read
Automate deployment of your web scraper on VPS with Ubuntu 24.04 cloud-init
Developer interest

Automate deployment of your web scraper on VPS with Ubuntu 24.04 cloud-init

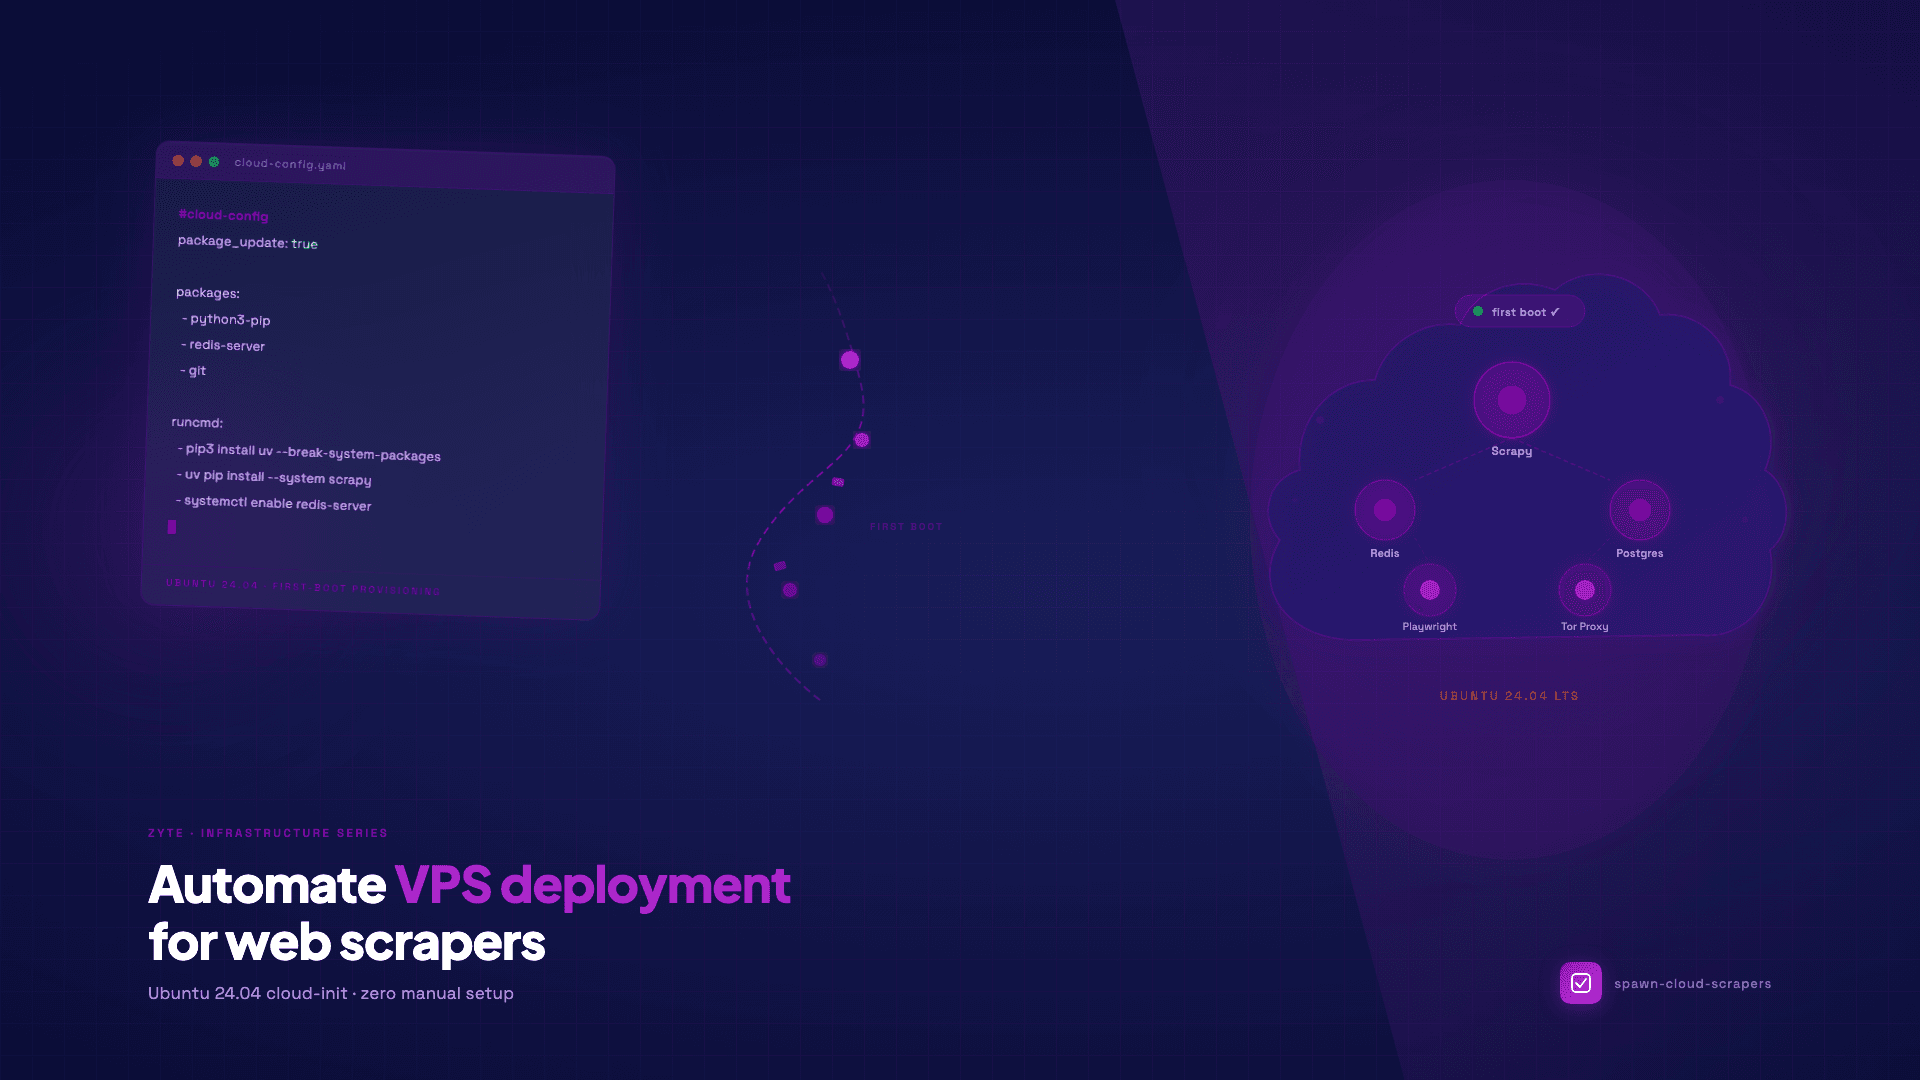
Your VPS is ready, but now you need to work through the same sequence you have run a dozen times before: apt update, apt install python3-pip, pip install scrapy, playwright install chromium, the Chromium dependency list that never installs cleanly on the first try, Redis, possibly Postgres, whatever else this particular project needs.

Ayan Pahwa9 min read
NotAnInterview: “I Have Superpowers Now"
Developer interest

NotAnInterview: “I Have Superpowers Now"

The problem was a project with 12,000 websites to crawl, and there’s no world where you write custom spiders for 12,000 websites, not with a human team and certainly not sustainably. So Javier built a workflow: a set of AI prompts that could analyze a website, figure out its structure, and generate a crawl configuration that a generic spider could then use.

Neha Setia Nagpal9 min read
Flatcar Linux for web scrapers: deploy immutable containers with just one config file
Developer interest

Flatcar Linux for web scrapers: deploy immutable containers with just one config file

The next time you spin up a VPS to give it a persistent home, you spend the better part of an afternoon rebuilding from memory. Here's a tool to help using Flatcar Linux

Ayan Pahwa11 min read

The Community · Newsletter

The best of Zyte and the data web, in your inbox.

One curated edition — new articles, product updates, and the stories shaping the data web. No noise.