PINGDOM_CHECK

Zyte Developers Community Newsletter Issue 3: Celebrating Milestones

Zyte Developers Community Newsletter Issue 3 - Explore the third edition of our newsletter, keeping you informed about the vibrant Zyte developers' community.

Attila Toth

1 min read ·

Zyte Developers Community Newsletter Issue 3: Celebrating Milestones

Zyte Developers Community newsletter issue #3

Hi there,

If you are not signed up already for the Zyte Developers Community newsletter, you can sign up here.

In this issue:

  • Scrapy 2.5.0 is out
  • Recipe scraping app (with source code)
  • Web scraping in Elixir
  • Easy table scraping with R

Scrapy 2.5.0 is out

The first new Scrapy release of the year is here!

Highlights:
- Official Python 3.9 support
- Experimental HTTP/2 support
- New get_retry_request() function to retry requests from spider callbacks
- New headers_received signal that allows stopping downloads early
- New Response.protocol attribute

Release notes here.

Recipe scraping app

@mango_mero - as part of the #100DaysOfCode challenge -  created an awesome django demo app which scrapes recipe information real-time, using beautifulsoup. Source code is available on Github.

Web scraping in Elixir

If you are using Elixir for web dev, and considering a web scraping project, you might want to check out this framework: Crawly, a high-level web crawling & scraping framework for Elixir. Check out the documentation and the quickstart guide.

Easy table scraping with R

Extracting data from HTML tables can be messy. For one-off jobs though, there's an easy alternative. If you're using R Studio, there's an addin which makes it easy to scrape tables: datapasta. You literally just copy the table from the page, paste it into the tool and you get the data in structured form. Here's a tutorial video.

Try Zyte API

Build your first scraper in minutes

Free trial, no credit card. From a single request to production in an afternoon.

Get started

Continue reading

The harness matters more than the model - Podcast EP07
AI-assisted data extraction

The harness matters more than the model - Podcast EP07

"The model is the engine — but the harness is everything else." In Episode 7, we dig into why the infrastructure layer around your AI model matters more than the model itself, rank the best models available right now, and ask whether the open-weighted revolution is about to make frontier subscriptions obsolete.

John Rooney11 min read
How to build your first Scrapy extension
Developer interest

How to build your first Scrapy extension

My Scrapy project now plays a triumphant fanfare when a crawl finishes clean and a sad trombone when it doesn't, which is also how I finally learned what Scrapy's extension points are actually for.

Ayan Pahwa11 min read
Now what exactly is loop engineering? And where do Anthropic's Fable 5 model and web scraping fit in?
Developer interest

Now what exactly is loop engineering? And where do Anthropic's Fable 5 model and web scraping fit in?

A viral clip from Claude Code's creator put a name to something a lot of us have been circling: loop engineering. Here's why web scraping may be its best-fit domain — and what that means in practice.

Ayan Pahwa12 min read
Automate deployment of your web scraper on VPS with Ubuntu 24.04 cloud-init
Developer interest

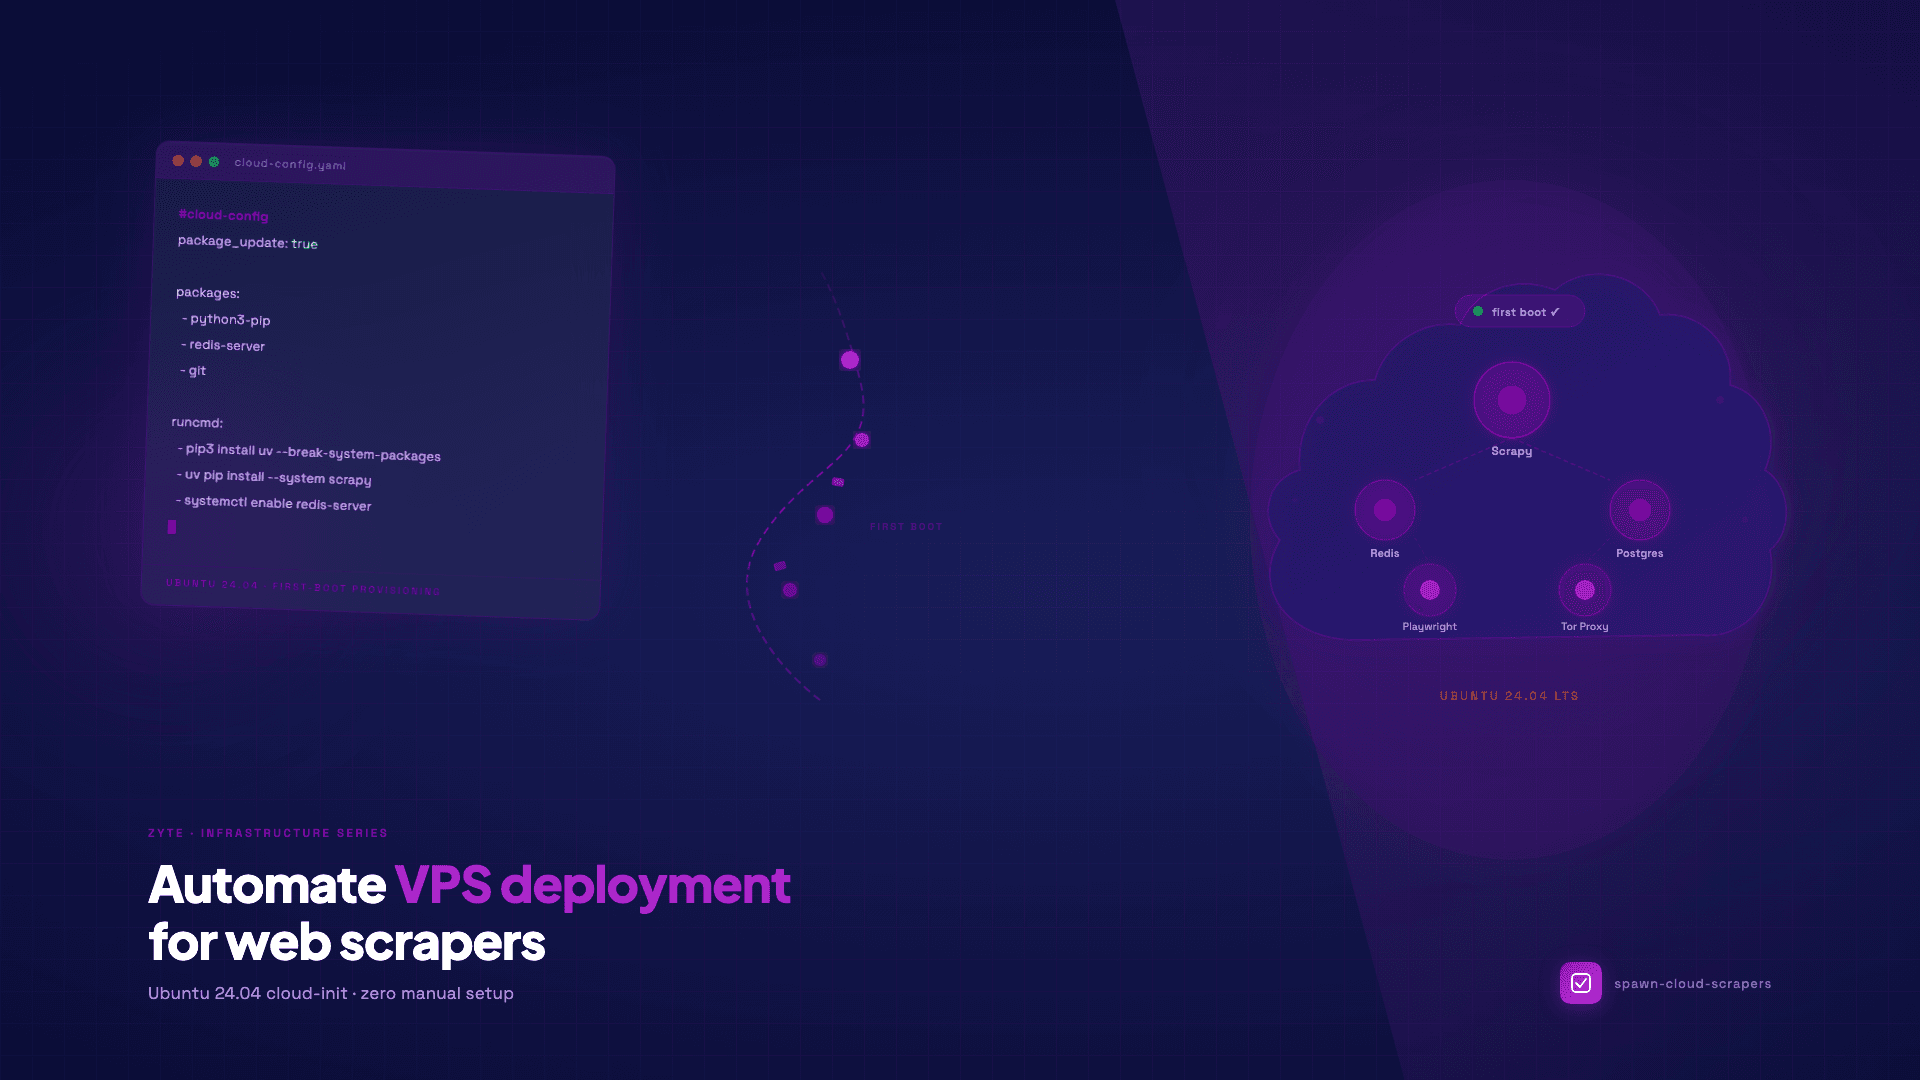
Automate deployment of your web scraper on VPS with Ubuntu 24.04 cloud-init

Your VPS is ready, but now you need to work through the same sequence you have run a dozen times before: apt update, apt install python3-pip, pip install scrapy, playwright install chromium, the Chromium dependency list that never installs cleanly on the first try, Redis, possibly Postgres, whatever else this particular project needs.

Ayan Pahwa9 min read
NotAnInterview: “I Have Superpowers Now"
Developer interest

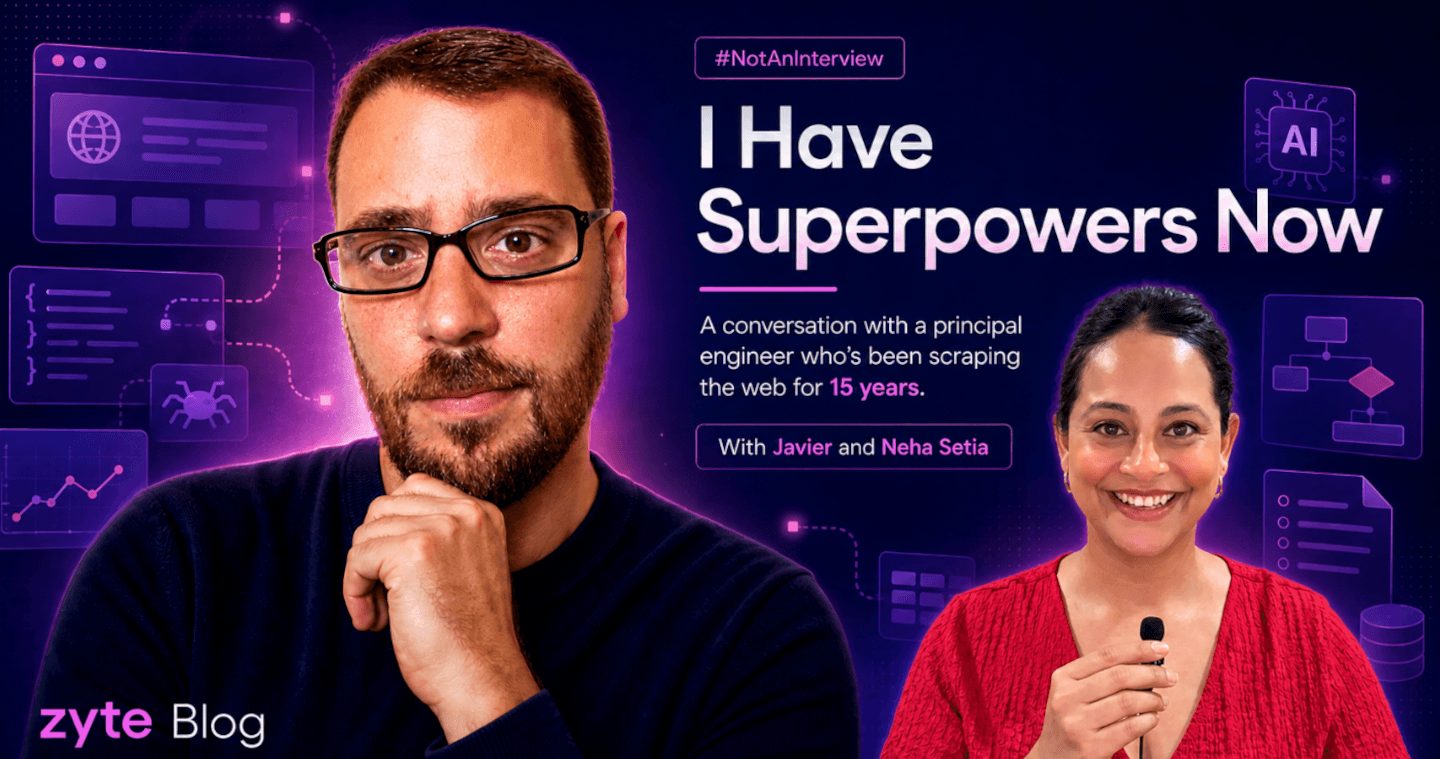
NotAnInterview: “I Have Superpowers Now"

The problem was a project with 12,000 websites to crawl, and there’s no world where you write custom spiders for 12,000 websites, not with a human team and certainly not sustainably. So Javier built a workflow: a set of AI prompts that could analyze a website, figure out its structure, and generate a crawl configuration that a generic spider could then use.

Neha Setia Nagpal9 min read
Flatcar Linux for web scrapers: deploy immutable containers with just one config file
Developer interest

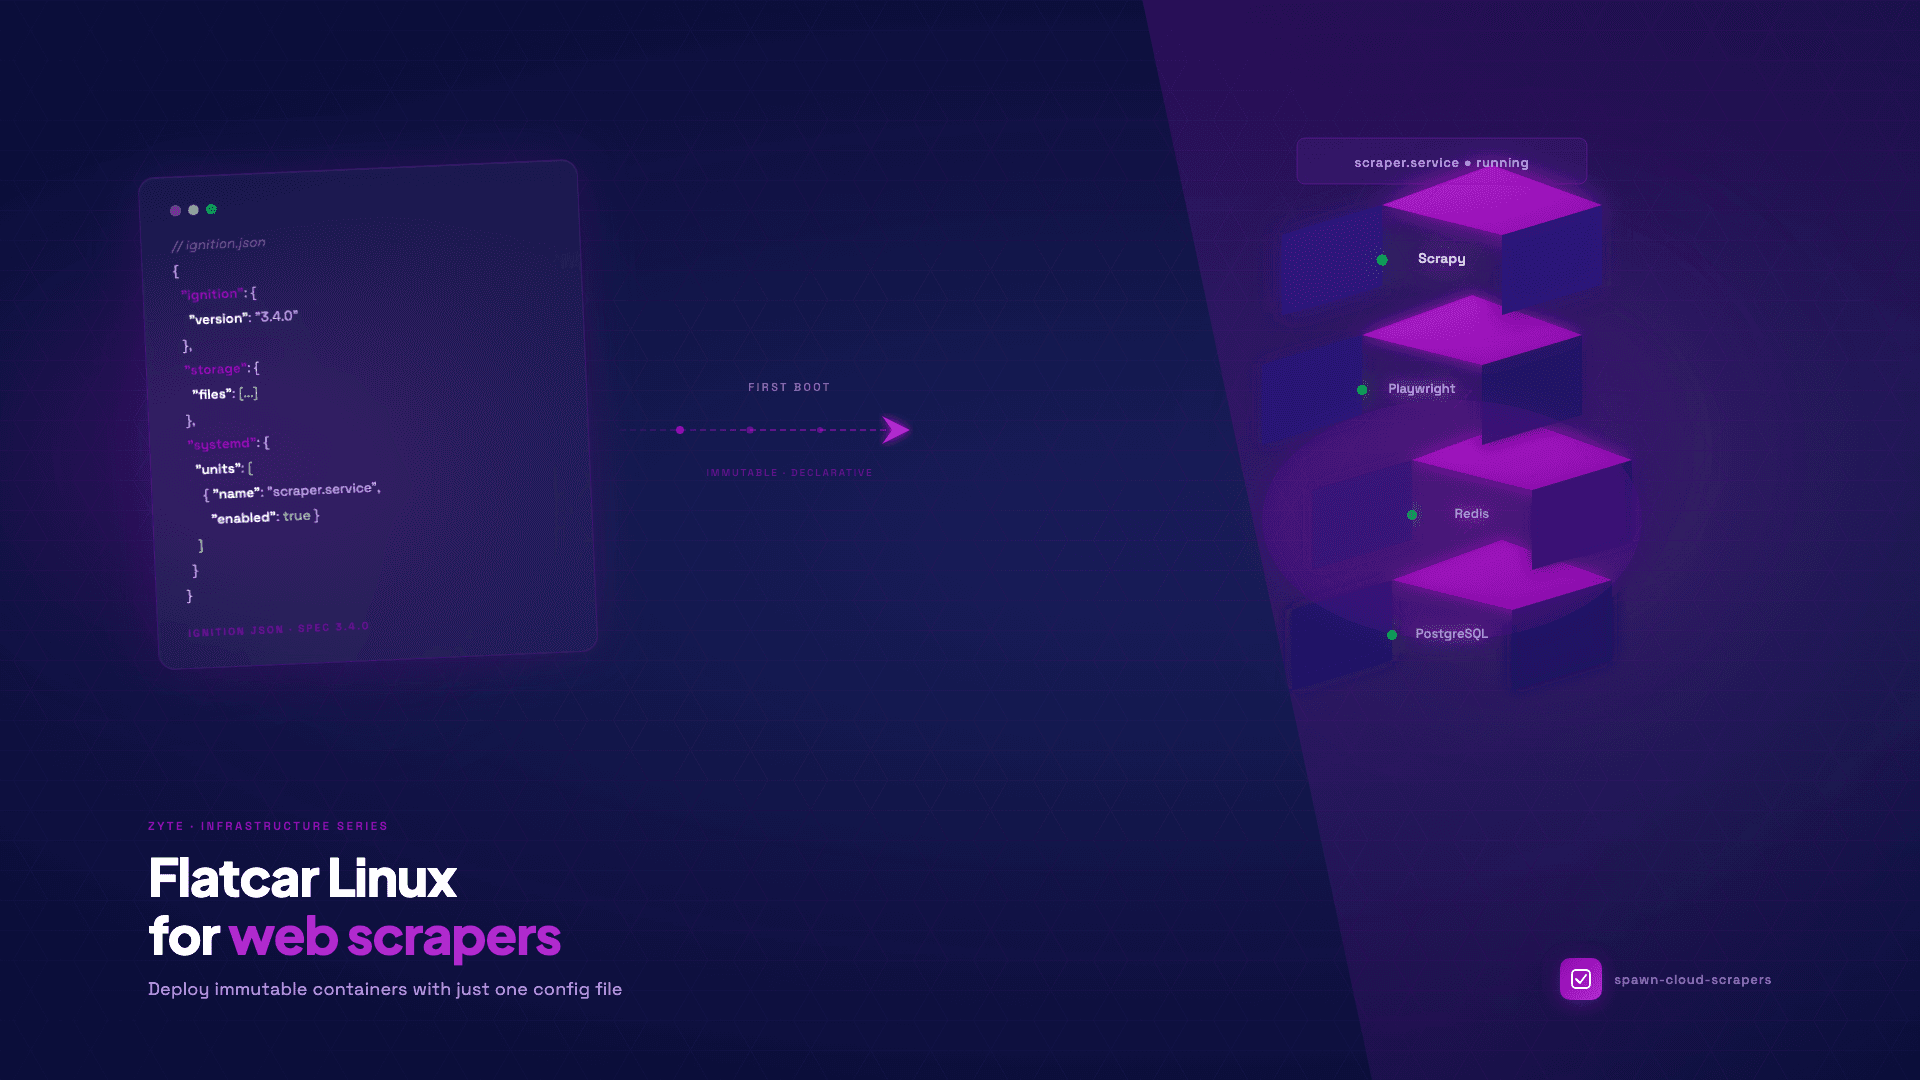
Flatcar Linux for web scrapers: deploy immutable containers with just one config file

The next time you spin up a VPS to give it a persistent home, you spend the better part of an afternoon rebuilding from memory. Here's a tool to help using Flatcar Linux

Ayan Pahwa11 min read

The Community · Newsletter

The best of Zyte and the data web, in your inbox.

One curated edition — new articles, product updates, and the stories shaping the data web. No noise.