Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
0% Hallucination? RAG + Web Scraping (Step-by-Step)
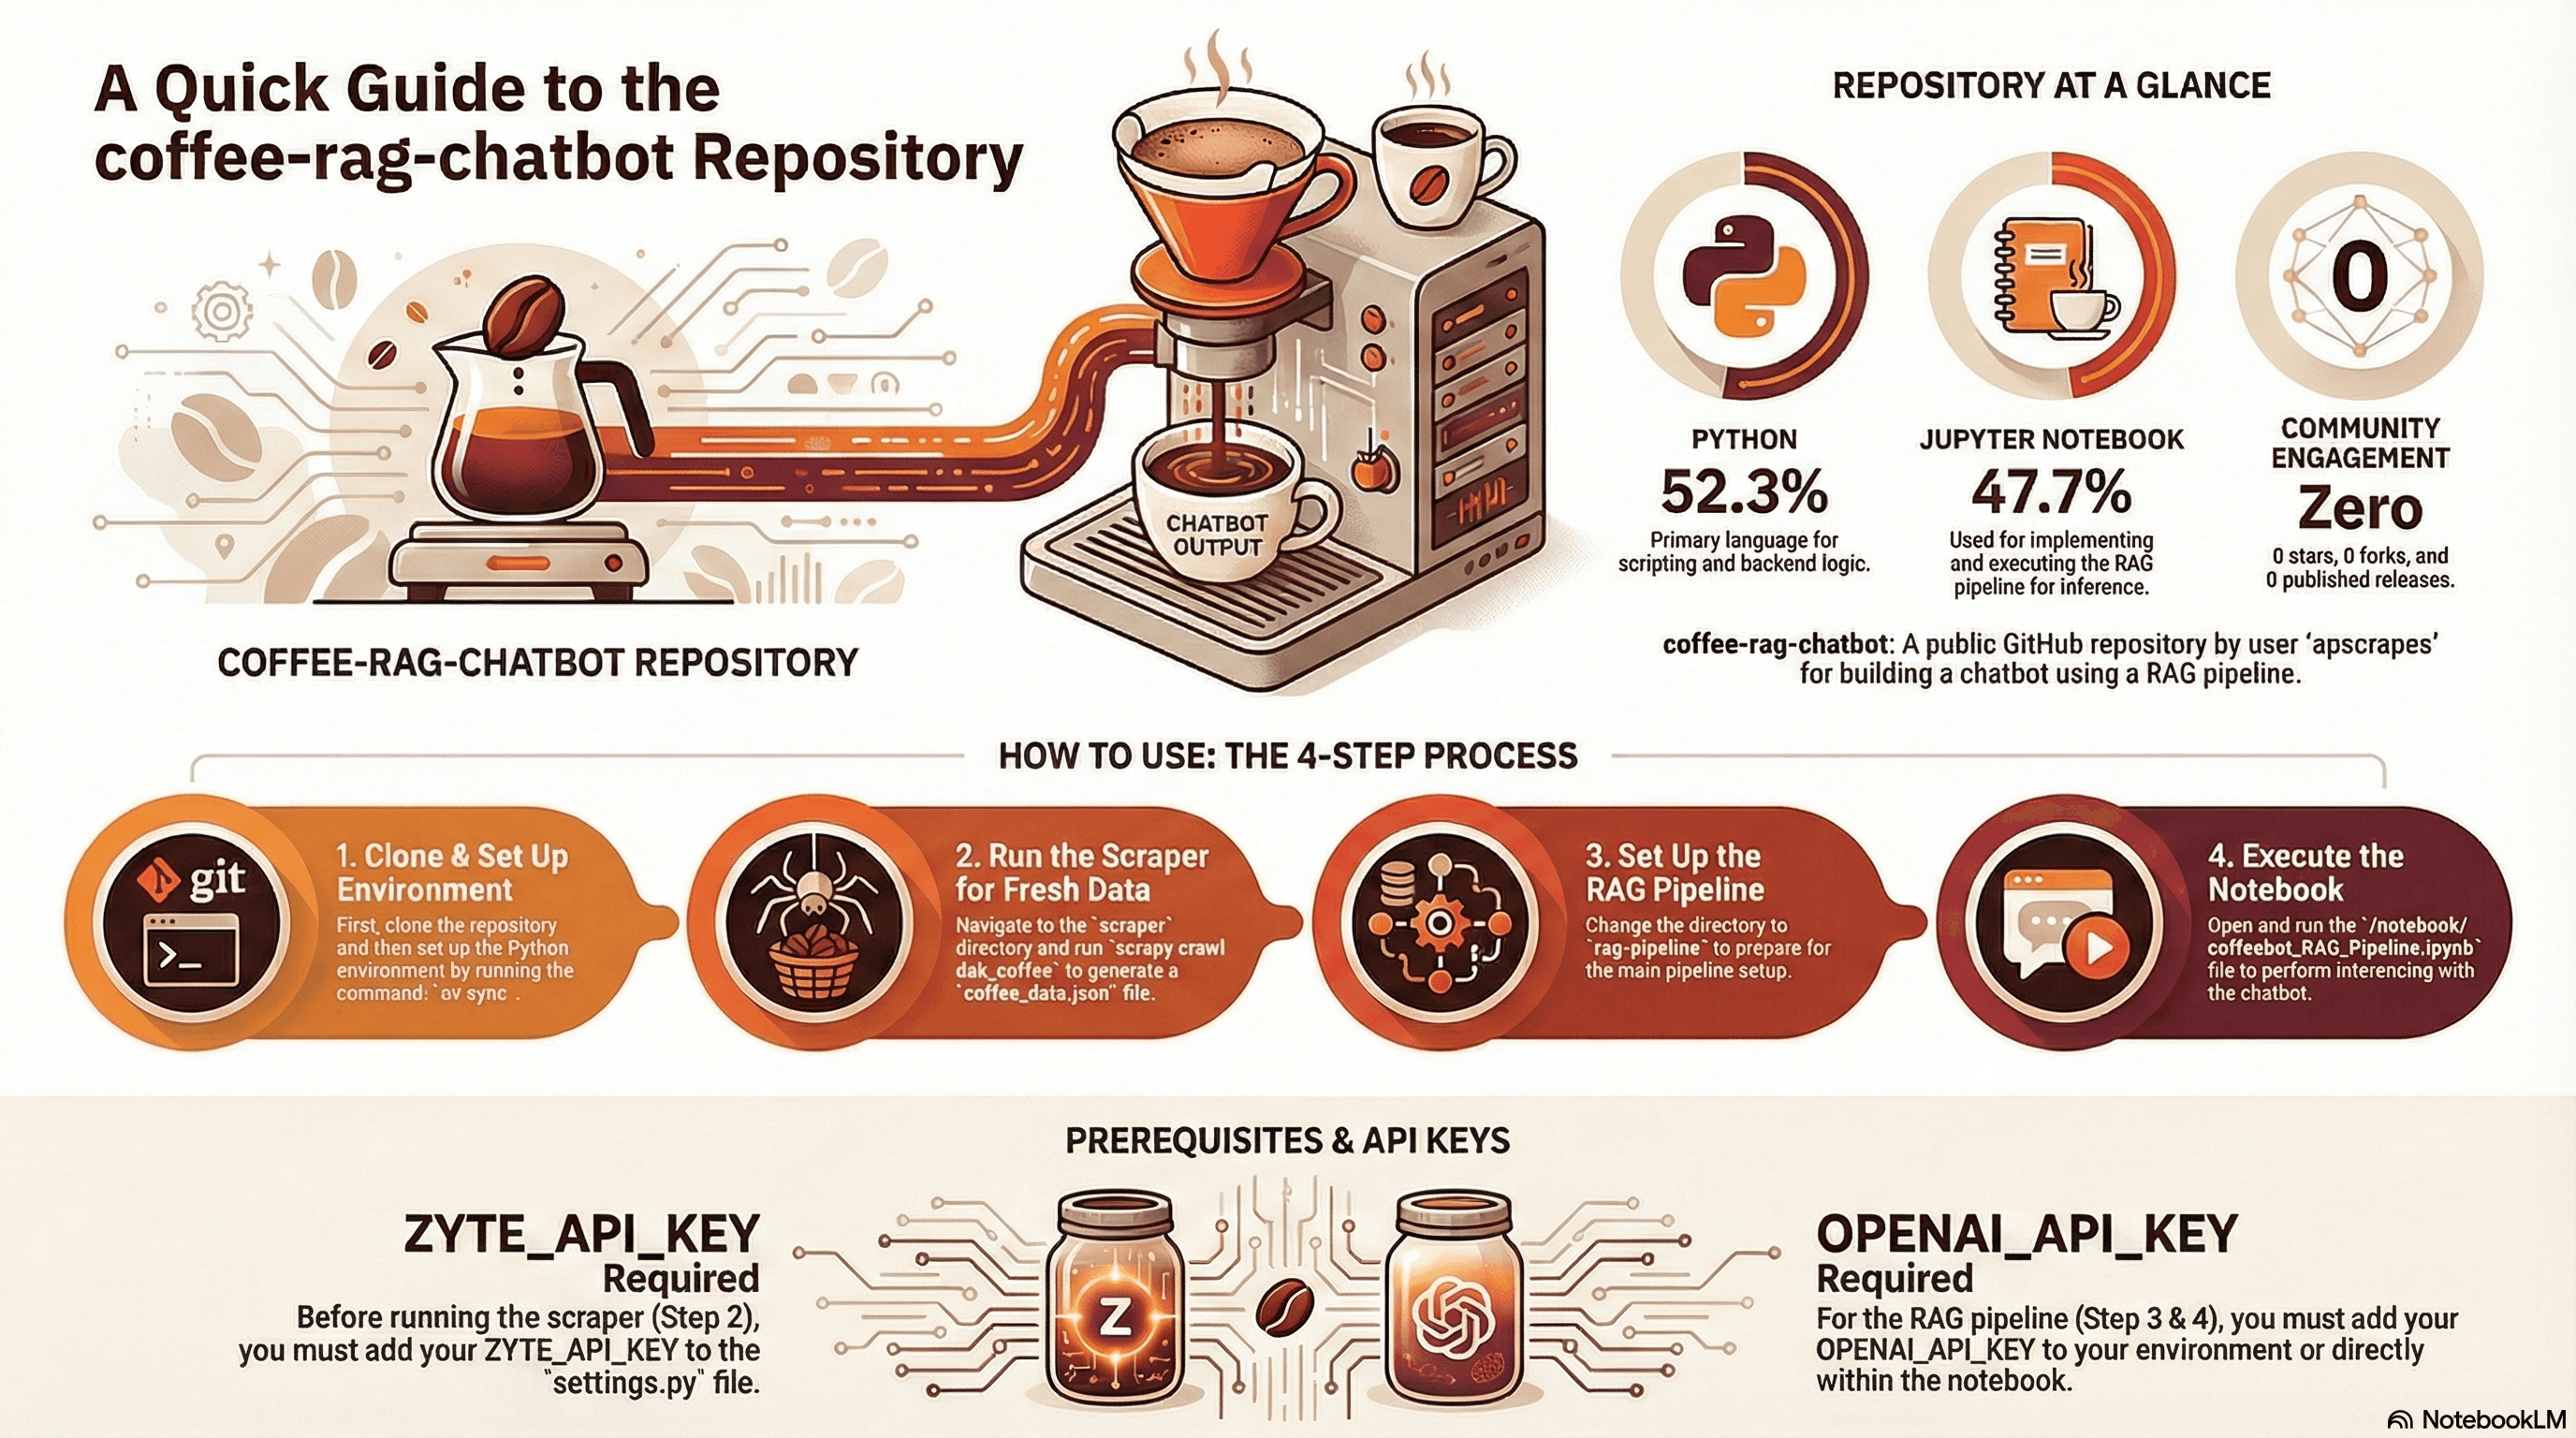
Brewing a bot: RAG and web data fuel the perfect coffee recommendation
Learn how to build a real-time AI chatbot using RAG, web scraping, Zyte API, LangChain, and OpenAI. Scrape JavaScript-heavy websites, store data in a vector database, and generate accurate answers from fresh web data.
Beyond text: Unlocking value on the multimedia web
The web is about more than the written word. Why companies are racing to harness the power of video, audio and pictures.
A data scientist's guide to stress-free product scraping
As a data scientist, your job is to find patterns, build models, and generate insights. To do that, you first need to reliably acquire web data. Competitor pricing, product specifications, consumer reviews - you name it, data scientists need it.
Why Python Requests gets "403 Forbidden"
If you’ve had your HTTP request blocked regardless of using correct headers, cookies, and good IPs, there’s a chance you are running into one of the simplest forms of blocking, and one of the most confusing for beginners.
Building a production-style web scraper with Scrapy, Docker, and PostgreSQL
Demo project scrape2postgresql shows how to scrape structured data with Scrapy, store it in PostgreSQL, and run both the spider and database in separate containers using Docker Compose.
Why Page One SERP data Is no longer enough for SEO and AI systems
Page-one SERP data shows visibility, but deeper results reveal volatility, trends, and opportunity. Learn why SEO platforms and AI systems need full-depth data.
Why pagination logic becomes operational debt at SERP scale
SERP pagination becomes brittle and expensive at scale. Learn why retries, deduplication, and ordering logic turn into operational debt over time.
Why SERP data costs exploded, and why most teams felt it overnight
SERP data costs spiked overnight after bulk access patterns disappeared. Learn what changed, why inefficiency exploded, and what it means for SEO platforms.
SERP data collection at scale and why efficiency matters again
Why has SERP data collection become more expensive? Learn what changed, why efficiency declined, and how it impacts SEO platforms and AI systems at scale.
Teaching AI to scrape like a pro: how we measure LLMs’ data quality
AI-enabled code editors can now conjure scraping code on command. But is it any good? Here’s how Zyte re-engineered LLMs with Web Scraping Copilot to drive best-in-class output.