Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
Web traffic is splintering into access lanes
Explore how AI agents are reshaping web traffic into hostile, negotiated, and invited access lanes. Learn what this means for bots, scraping, and the future of data access.
How online retailers use web data to compete on price, promotion, and availability
Discover how retailers leverage web data to optimize pricing, track competitor stock, detect trends, and improve sales performance.
The recipe for a request: Scaling data extraction through investigation
Learn how an investigative mindset helps scale data extraction from single requests to millions daily by building resilient, efficient scraping systems.
From screenshot to shopping list in 90 seconds
I built a mood board pipeline that starts with a screenshot. Claude Skills and Zyte API for search, product extraction, and image embedding at any scale.
Automation drives power in the data arms race
Anti-bot systems now evolve in minutes, not weeks. Discover why automated, self-healing scraping systems are essential to survive the 2026 data arms race and how to adapt.
Should AI Companies Build Their Own Web Scraping Pipelines?
Should AI companies build their own web scraping pipelines? Learn when in-house scraping makes sense and when it becomes costly and hard to maintain at scale.
What Is AI Data Provenance? Definition & Importance
Learn what AI data provenance is and why it matters. Understand data origin, collection methods, governance, and how provenance supports trust and compliance.
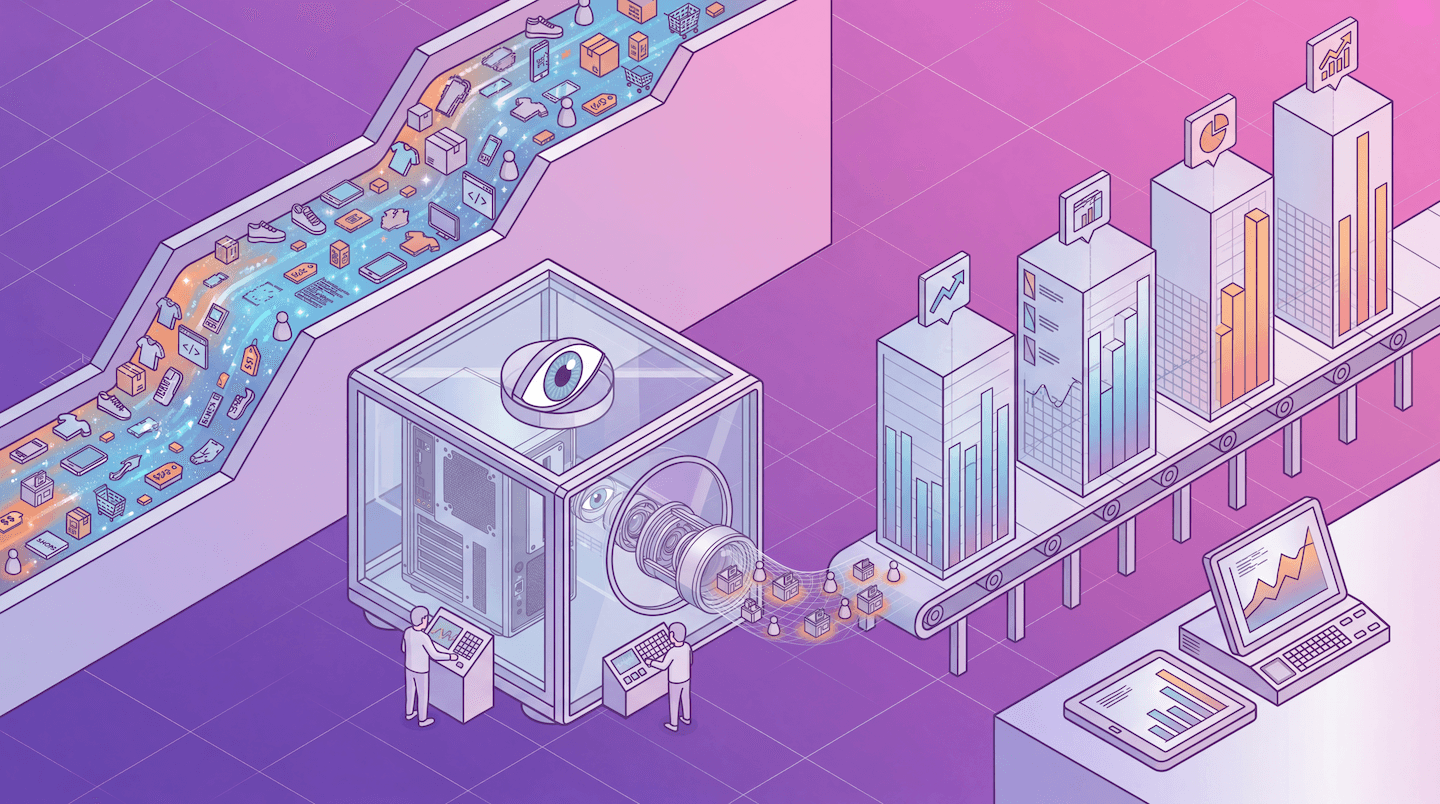
How web data turns e-commerce listings into retail intelligence
Discover how web data enables digital shelf analytics vendors to track prices, availability, and product trends at scale—fueling real-time retail intelligence and competitive advantage.
The seven habits of highly effective data teams
Discover the seven habits that set high-performing data teams apart—from treating data as a product to ensuring data trust, quality, and decision impact. Learn how leading teams scale reliable data systems.
How to ensure data quality in your Scrapy web scraping projects using Spidermon and Claude Code
Spidermon is an open-source monitoring framework for Scrapy. You attach it to your spider, define what "success" looks like, and it automatically checks your crawl results after the spider closes, flagging anything that doesn't meet your standards.
Why your API responses look like gibberish: the gzip decompression trap
The script was working. Requests were going out, responses were coming back with HTTP 200. But the response body was unreadable noise, a wall of binary characters that crashed the JSON parser and reported "no data found". No error code, no timeout, no network failure; just garbage where structured data should be.
Dawn of the autonomous data pipeline
Discover how autonomous, agent-driven data pipelines are transforming web scraping in 2026, enabling self-healing systems, API discovery, and end-to-end automation.