Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
What is a residential proxy?
Learn what residential proxies are, how they compare to datacenter proxies, and why modern web scraping needs more than IP diversity.
How much do rotating proxies cost?
Learn how much rotating proxies cost, what affects pricing, and why total web scraping costs often go beyond proxy subscriptions.
How do rotating proxies work?
Learn how rotating proxies work, when to use them for web scraping, and why IP rotation alone is not enough for reliable data access.
Are proxies legal for web scraping?
Learn whether proxies are legal for web scraping, what compliance factors matter, and why modern teams use automated unblocking beyond proxy management.
Announcing powerful new spending controls and usage insights for Zyte API
Consign bill-shock to the trashcan. New custom spending limits and usage insights put data-gatherers in control.
Meet the new-look Zyte Domain Health Hub: Your command center for data extraction performance
Monitor your data-gathering pipelines like a boss - and act on domain issues in real-time.
NotAnInterview: “I Have Superpowers Now"
The problem was a project with 12,000 websites to crawl, and there’s no world where you write custom spiders for 12,000 websites, not with a human team and certainly not sustainably. So Javier built a workflow: a set of AI prompts that could analyze a website, figure out its structure, and generate a crawl configuration that a generic spider could then use.
Building a self-hosted browser scraping service (is it more hassle than its worth?)
If you want to understand exactly how a browser scraping service works at the infrastructure level, or you have a steady workload that you want running on hardware you already own, building one yourself teaches you things that matter. Here's how I did it
Web scraping on 22 KB of RAM: Fitting the world on an ESP8266 microcontroller
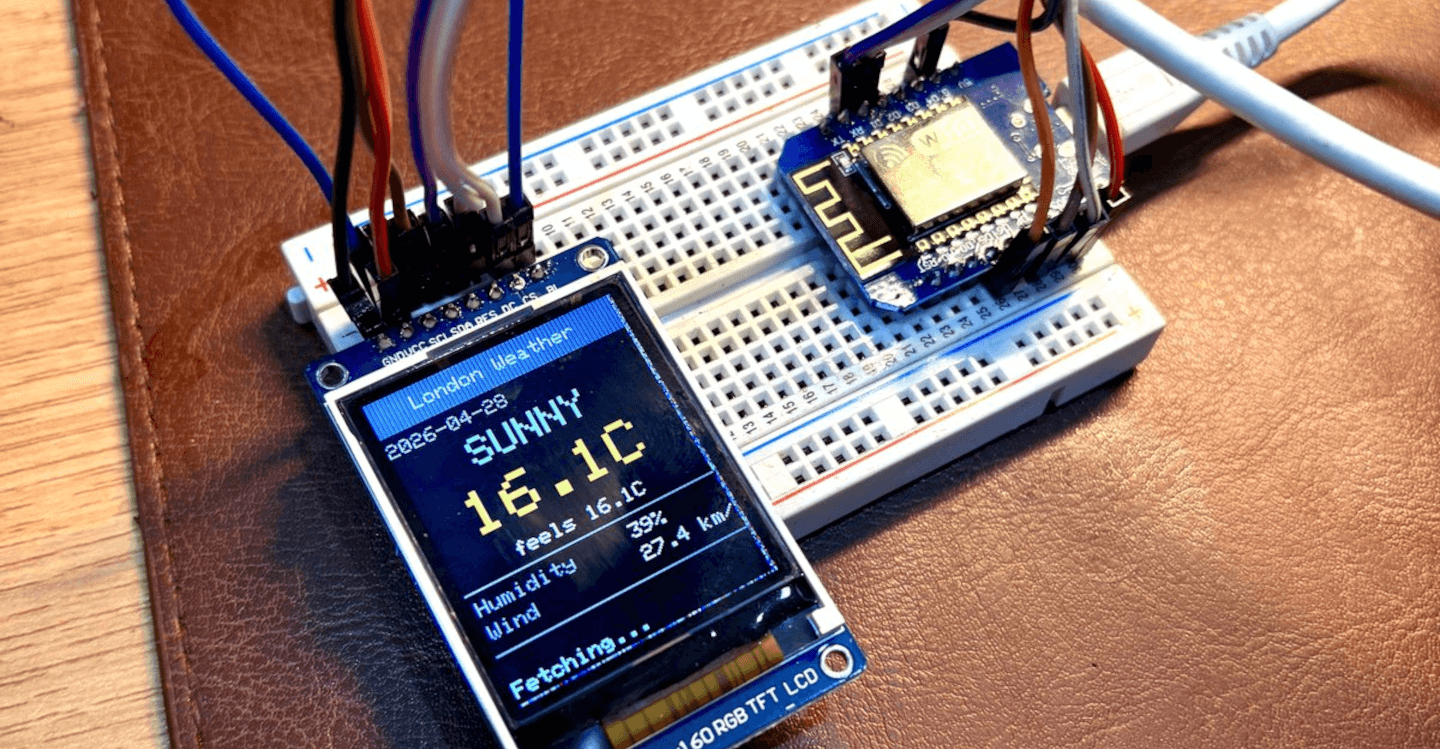
Data-gathering doesn’t have to be memory-intensive. You can fit the world’s weather on a 9cm-square board, when you move the work to a web scraping API.
I built scraping agents for 30 days - here’s what I learned
For the last 30 days, I did one thing almost exclusively: I built scraping systems with AI agents, from the ground up, across real targets, with real deadlines. Not prototypes designed to impress in a demo, not isolated experiments running against a toy website, but production-grade pipelines that needed to ship and keep running.
I'm not the same developer I was before LLMs
I've been running a series of conversations with developers at Zyte to understand what's actually changed in the way they work since LLMs showed up. Not the headlines. The day-to-day. What they delegate, what they don't, what they notice, what surprises them. This one was different on two counts.
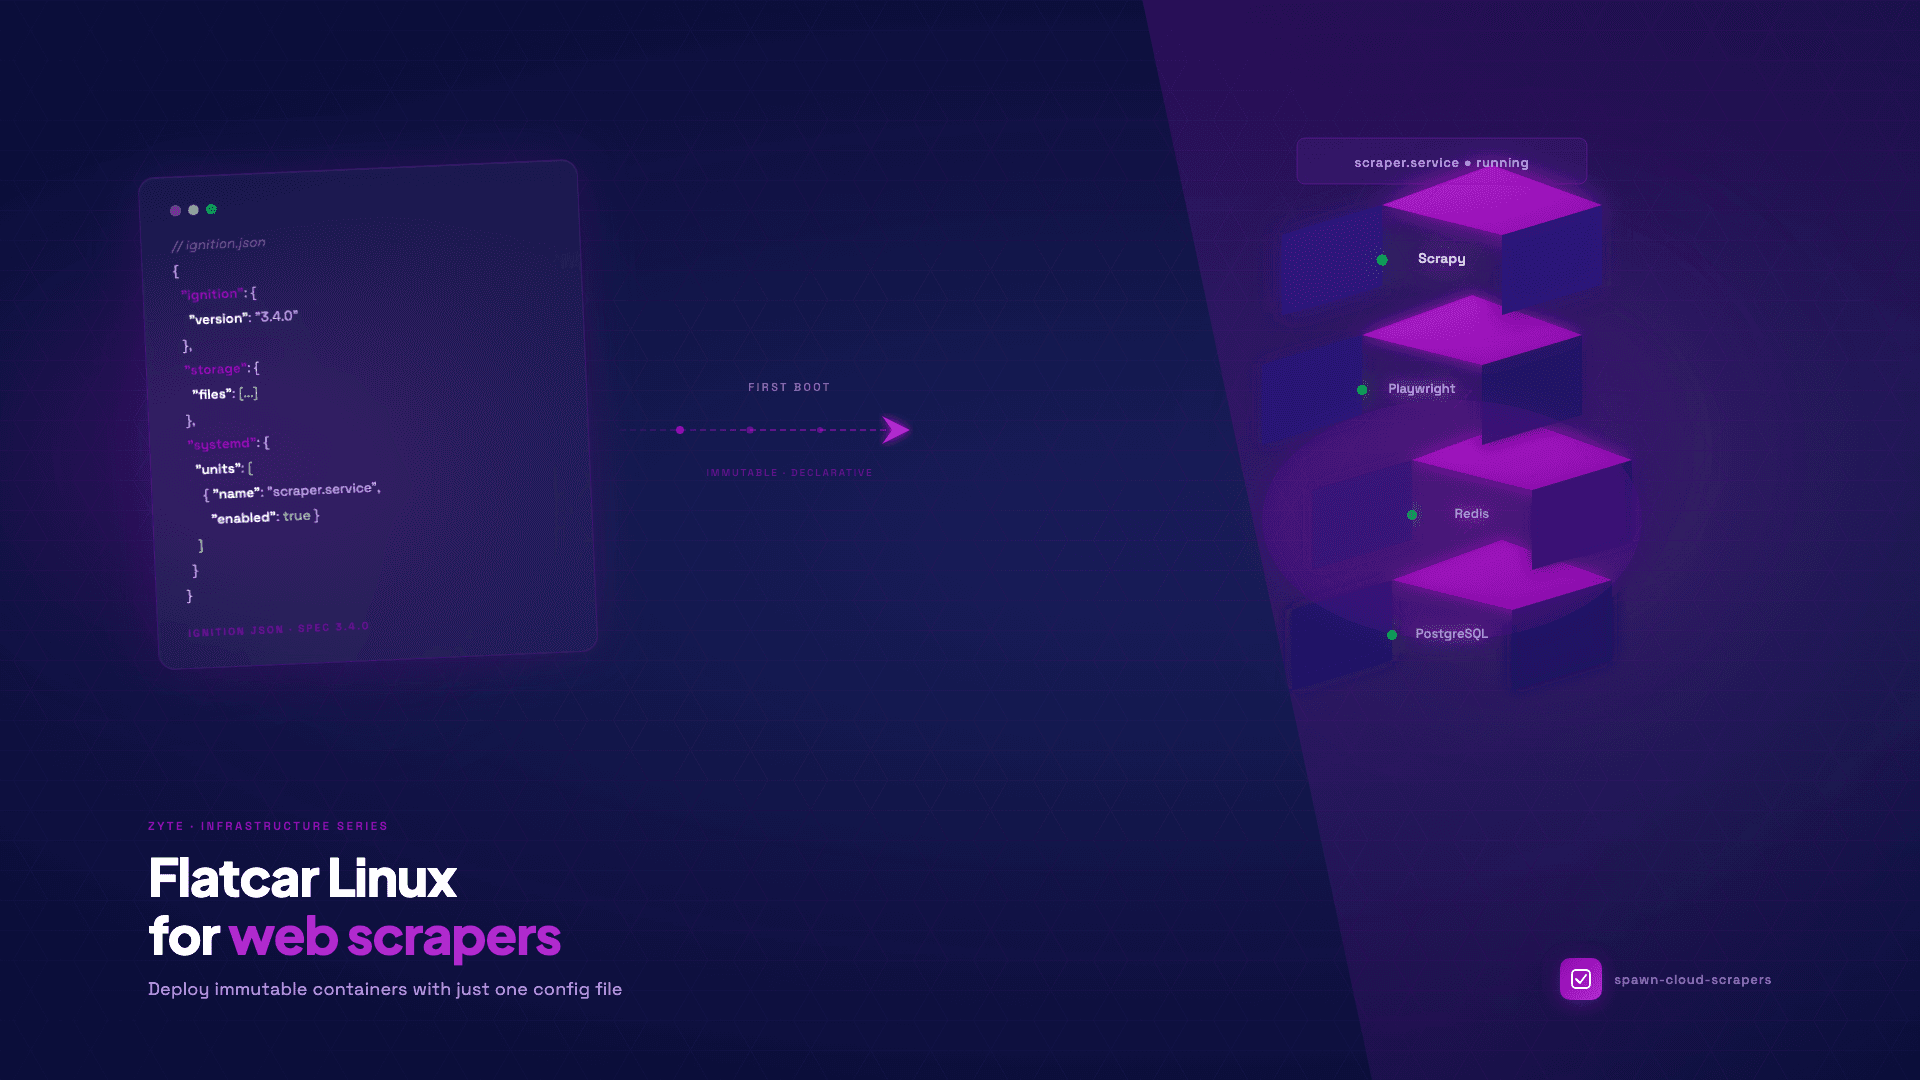
Flatcar Linux for web scrapers: deploy immutable containers with just one config file
The next time you spin up a VPS to give it a persistent home, you spend the better part of an afternoon rebuilding from memory. Here's a tool to help using Flatcar Linux