Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
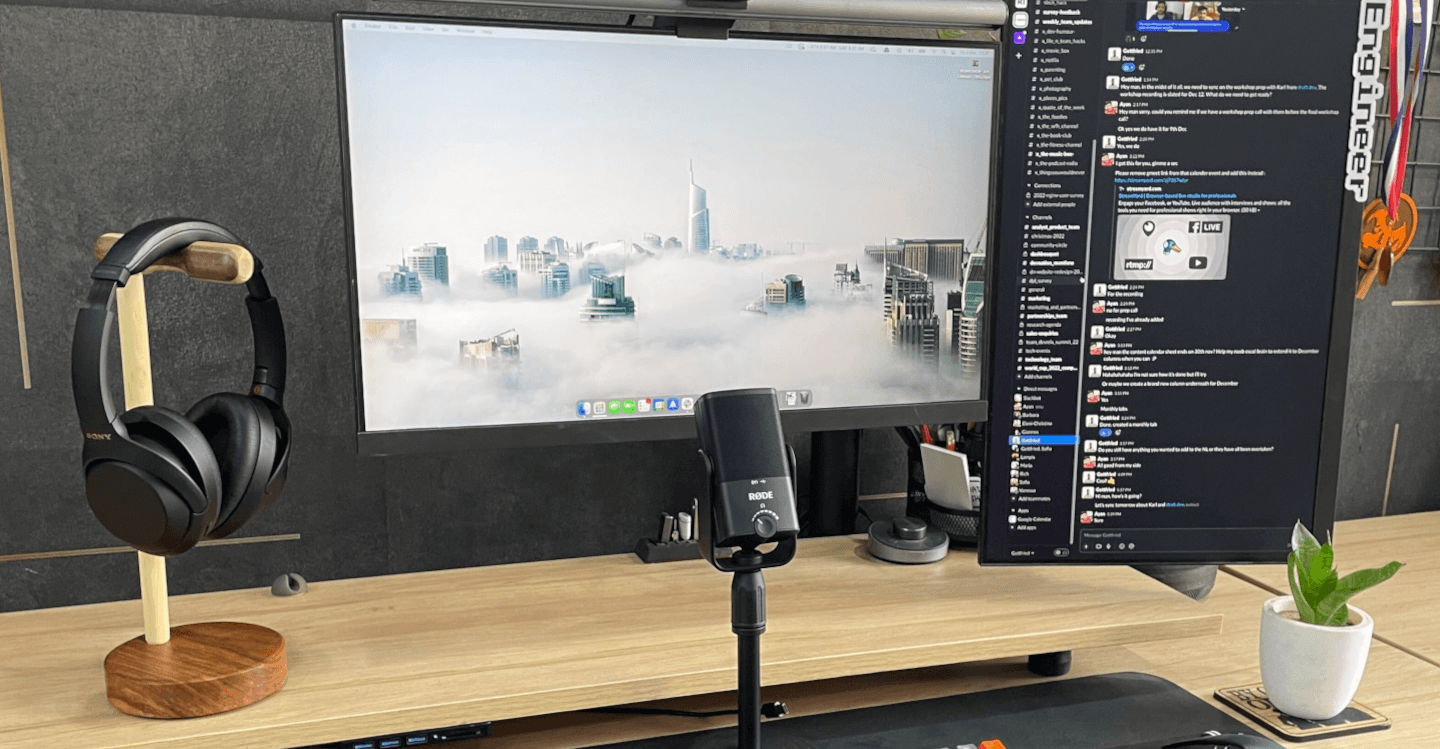
My agentic coding setup: Claude Code, multi-agent orchestration, and how I actually work
Ayan's 4 agent team, using Claude's /goal, and the models and coding agents he uses to code effectively.
llms.txt isn’t dead: How we put dev docs in AI’s spotlight
Marketers are giving up on the idea of plain-text pages - but llms.txt and Markdown are how we’ll get our docs in the hands of LLMs and developers.
The great wall of data: The complexities of web scraping in the Asian market
While the technological arms race of web data access is universal, the battleground in Asia has its own unique rules of engagement.
Actually, web scraping APIs are cheaper
Many data teams still think running a proxy-based scraping stack is most cost-effective. Industry pressures and our research disprove that idea.
The science of compliance: Tech tips for a legal data pipeline
New legal and regulatory compulsions for web data have significant business consequences. So, how can technologists engineer their company’s risk profile lower?
AI won’t fix your data quality (until you answer these three questions)
In our interview, a QA expert warns - before you delegate web scraping quality assurance to AI, make sure you can describe what ‘good’ looks like for yourself.
Why 10 million tokens won’t save your AI agent (and what will)
New models can process larger inputs, and confuse themselves in the process. Context management techniques can solve the problem.
Web scraping APIs vs proxies: A head-to-head comparison
Proxies are essential to scraping at scale. So, how do full-stack web scraping APIs compare?
OpenClaw and Claude helped me buy the perfect sneakers using Zyte API
Quickly compare e-commerce products across any site with an agent, a skill and an AI-powered web scraping API.
Legal clarity comes with compliance demands
Explore how new regulations like the EU AI Act and California AB 2013 are reshaping AI data compliance in 2026. Learn why provenance, transparency, and lawful sourcing are now critical.
Brand visibility in the digital era: How web data help brands see the full picture
Discover how web data helps brands improve visibility, track competitors, monitor availability, and analyze reviews to win on the digital shelf.
Giving spidey-senses to your web scraping spiders using Spidermon
Learn how Spidermon helps you monitor web scraping data quality in real time. Validate items, track field coverage, and get alerts before bad data impacts your pipeline.