Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.

Meet scrapy-spidey-sense: A preflight check for Scrapy spiders
`scrapy-spidey-sense` is an open-source command-line interface (CLI) that checks a Scrapy project before the crawl begins. It performs local, static analysis, reports the production-readiness basics that are present or missing, assigns a score, and connects each finding to a practical fix or relevant documentation
Rendering Javascript pages without giving up Scrapy
How to render dynamic content and work with a browser through playwright and scrapy.
Spider monitoring made easy
How do you know you're collecting all the data you need? And how can you be sure it's actually what you were expecting? Use Spidermon.
I joined the Real Python podcast to talk harnesses and Scrapy
I was recently a guest on the Real Python podcast where host Christopher Bailey opened with the question that has been following me around all year: which matters more, the model or the harness around it? Let's look into it.
Building maintainable spiders with scrapy-poet
Separating your extract and parsing logic out help increase the maintainability and extensibility of your projects, and scrapy-poet makes it easy.
Modern Scrapy for experienced developers: A new series
How to create production ready Scrapy projects to scrape the modern web. In this article we start the process of creating our spider, look at settings, and build a pipeline to help keep our data quality high.
A guide to Scrapy item types
Scrapy supports multiple item types, but which should you use, and why.

New Zyte add-ons: Agent Skills, Codex, GitHub and more updates
A host of additions to Zyte’s agentic scraping toolbelt helps developers go from prompt to working spider code and beyond.
Podcast Ep08 - Scrapy, Python and mushroom soup
Scrapy's core handles crawling well and deliberately leaves almost everything else out: no bundled browser, no opinion about how you shape your data, no built-in answer for every anti-bot wrinkle. What it gives you instead is a clean way to add those things at the edges, exactly when you need them and never before.
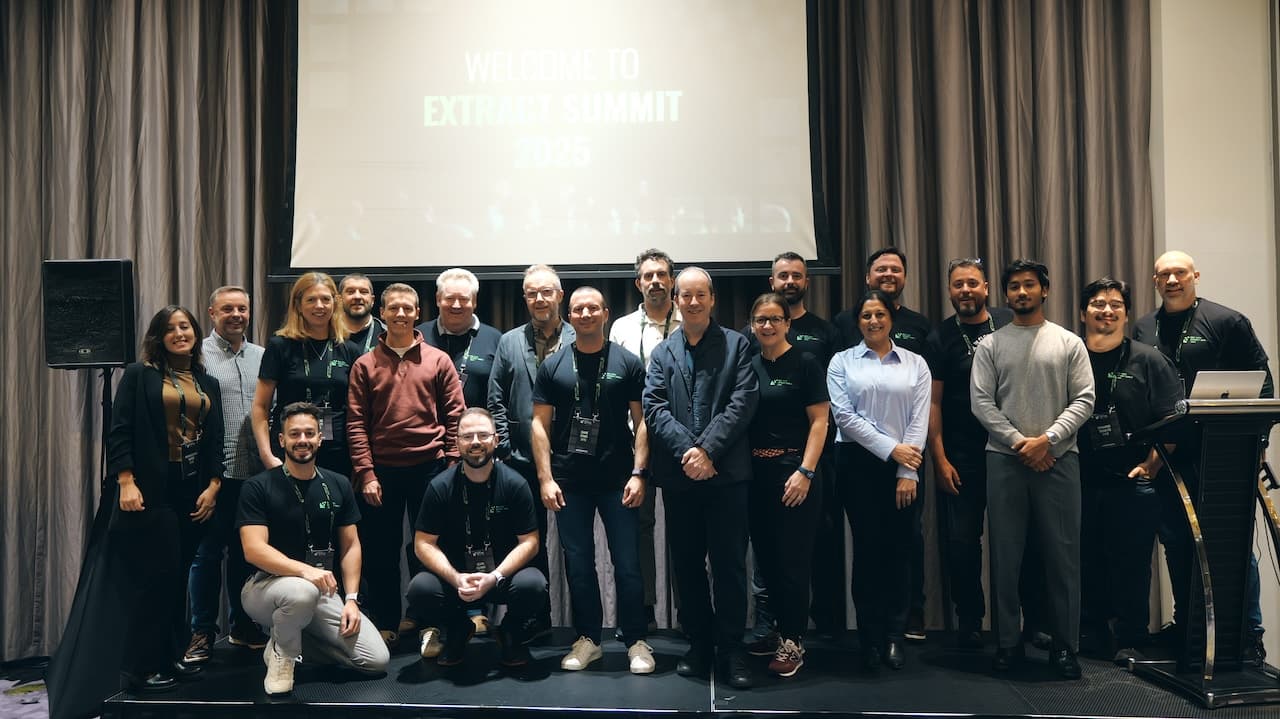
Five reasons to attend this year’s Extract Summit
In its eighth year, Extract Summit is again shaping up to be the web data industry's premier gathering.
The missing middle ground in scrapy-playwright just got filled
You can now choose which Python browser library you want to use with scrapy-playwright. I go through why this is a huge deal for the right scraping demographic.
Harness Engineering #3- Headless mode: the minimal agent harness
What's the smallest harness that still works? Turns out it's already sitting inside almost every coding agent you have installed — headless mode: same loop, tools, and reasoning as the interactive agent, minus the human in the chair. We point it at a web page and pull clean, structured data out the other end in about ten lines.