Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
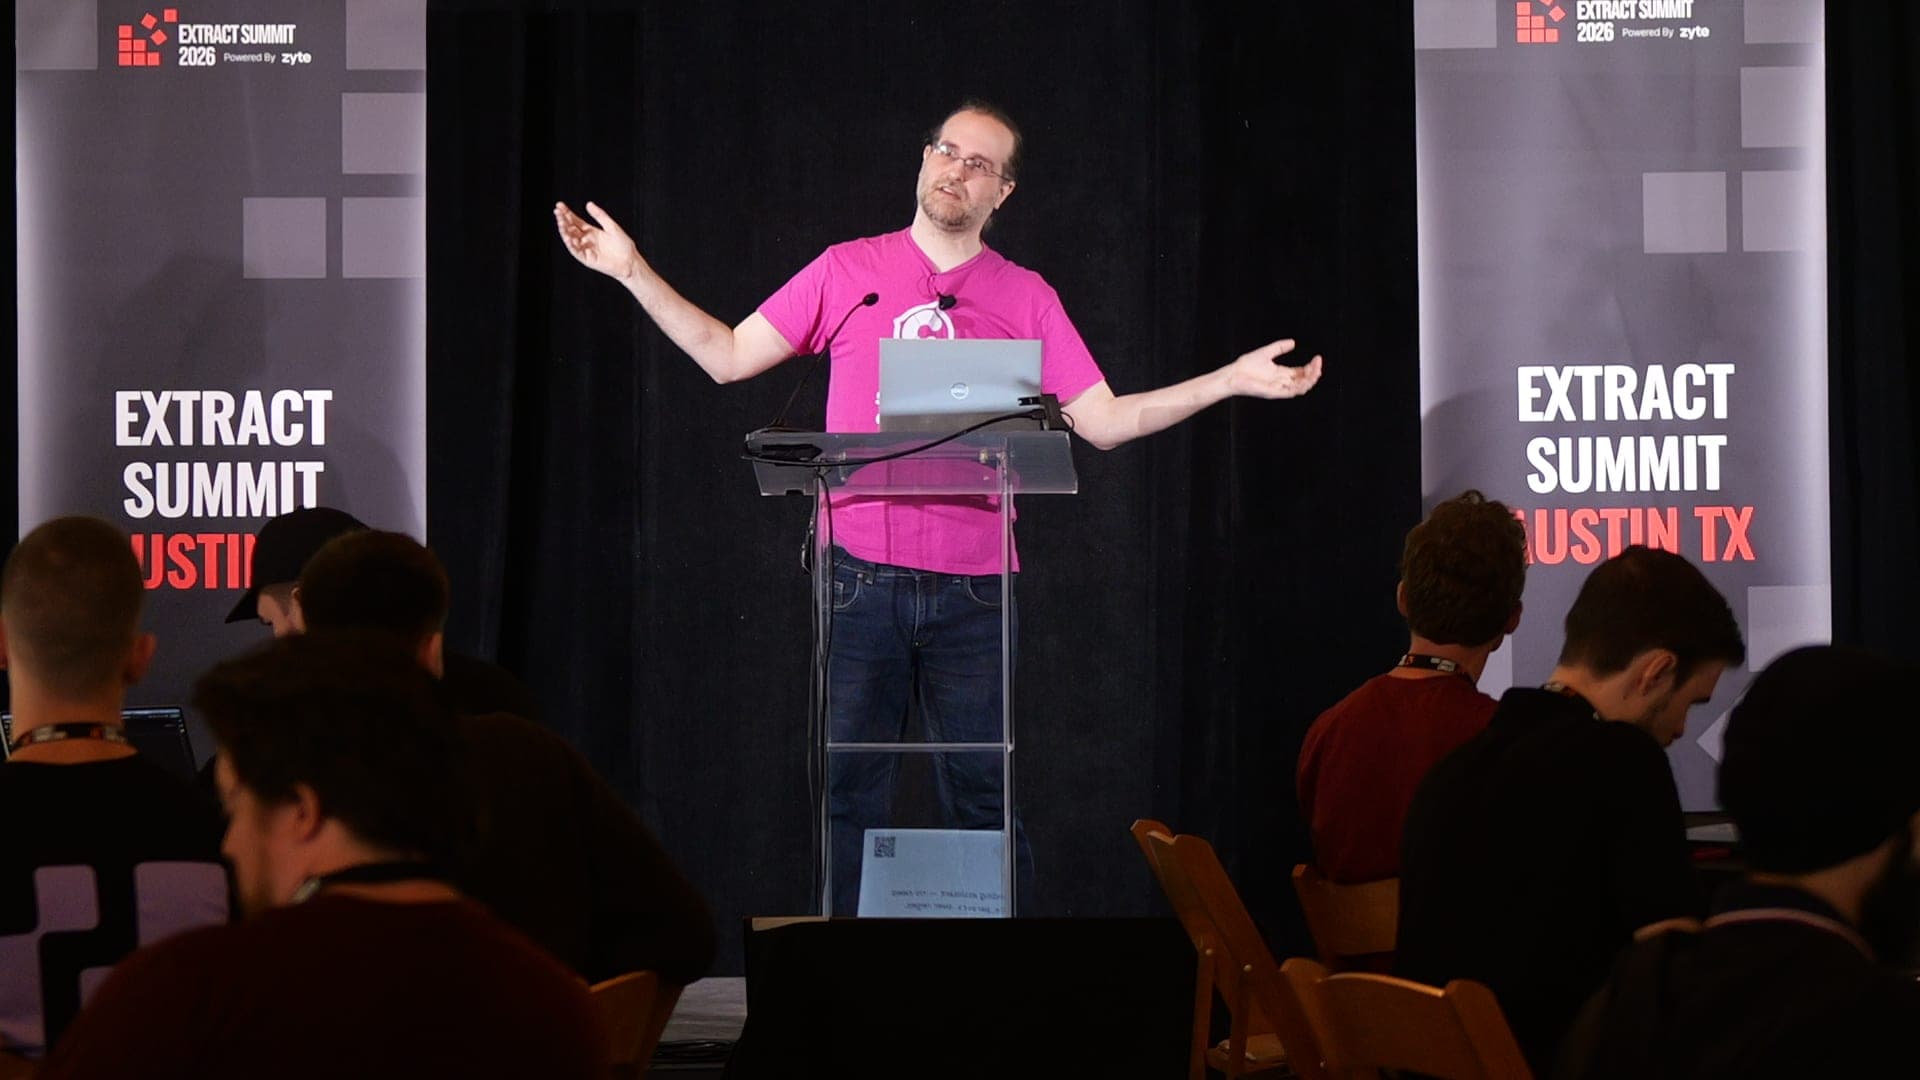
Five takeaways from Extract Summit 2026 Austin
AI is making web scraping faster - but dependable data takes more than working code. Quality, provenance, self-repair, access and responsibility are the new edge.
Rate limiting is a roadblock, not a speed limit
Rate limiting sounds like a speed limit, but 93.7% of rate-limited sites block on the very first request. It is an identity check, not a throttle.
Dateparser: a date parsing library for Python
Dateparser turns "3 days ago", "15 Mar 2022" and non-English month names into a Python datetime. What it handles, how to set it, and where it needs help.
Introducing Zyte MCP: Powerful web data gathering for your agent
Zyte MCP brings live web access, structured extraction and Scrapy Cloud operations into coding agents such as Claude Code, Cursor and Codex.
AI web scraping and scalable data collection
AI changes extraction, adaptation and the cost of adding a source. It does not change access. What is genuinely different, with the arithmetic.
CAPTCHA is more than just a puzzle piece
The famously awkward security mechanism has quietly become an invisible behavioral scoring system. Two vendors enable 89% of CAPTCHAs, and the smallest sites use it most.
Zyte Developer Community Meetup #2: the recap, slides, and recordings
Recordings, slides, and a rundown of Zyte's second Developer Community Meetup with Humanbound: a live prompt injection attack on a price agent, Zyte CDP managed browsers, and the launch of harness-run.
Inside Scrapy's RemoteControl extension
Scrapy 2.19's RemoteControl extension runs a small authenticated HTTP server inside every crawl. How it starts, how it's secured, what the code you send can reach, and what you can do with it on a live crawl, plus the traps and what changes under scrapy-zyte-api.
Scrapy MCP: debug your crawl while it runs
Scrapy MCP connects an AI agent to a running Scrapy crawl, using the new Remote Control extension in Scrapy 2.19 to let the agent discover jobs, check status and run Python against the live crawler, all without restarting it.
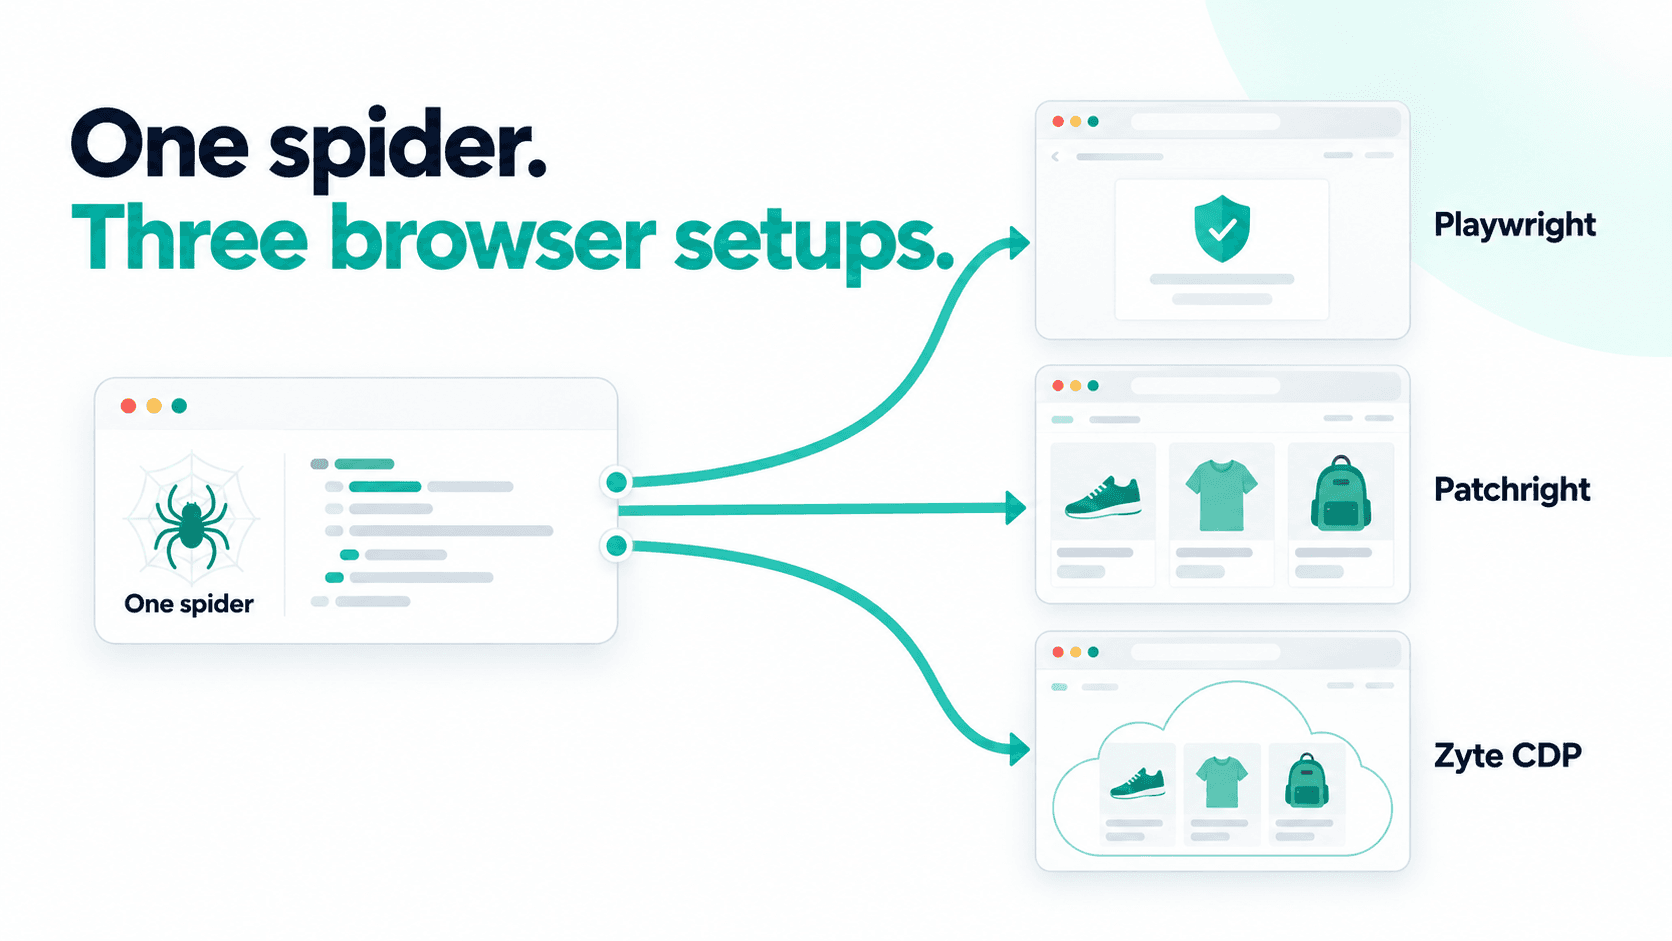
One Scrapy Spider, Three Browser Setups: Playwright, Patchright, and Zyte
One Scrapy spider, three browser setups: stock Playwright, Patchright via the new PLAYWRIGHT_BROWSER_PROVIDER hook, and a remote browser on Zyte over CDP. Same spider and selectors throughout, only the browser changes.
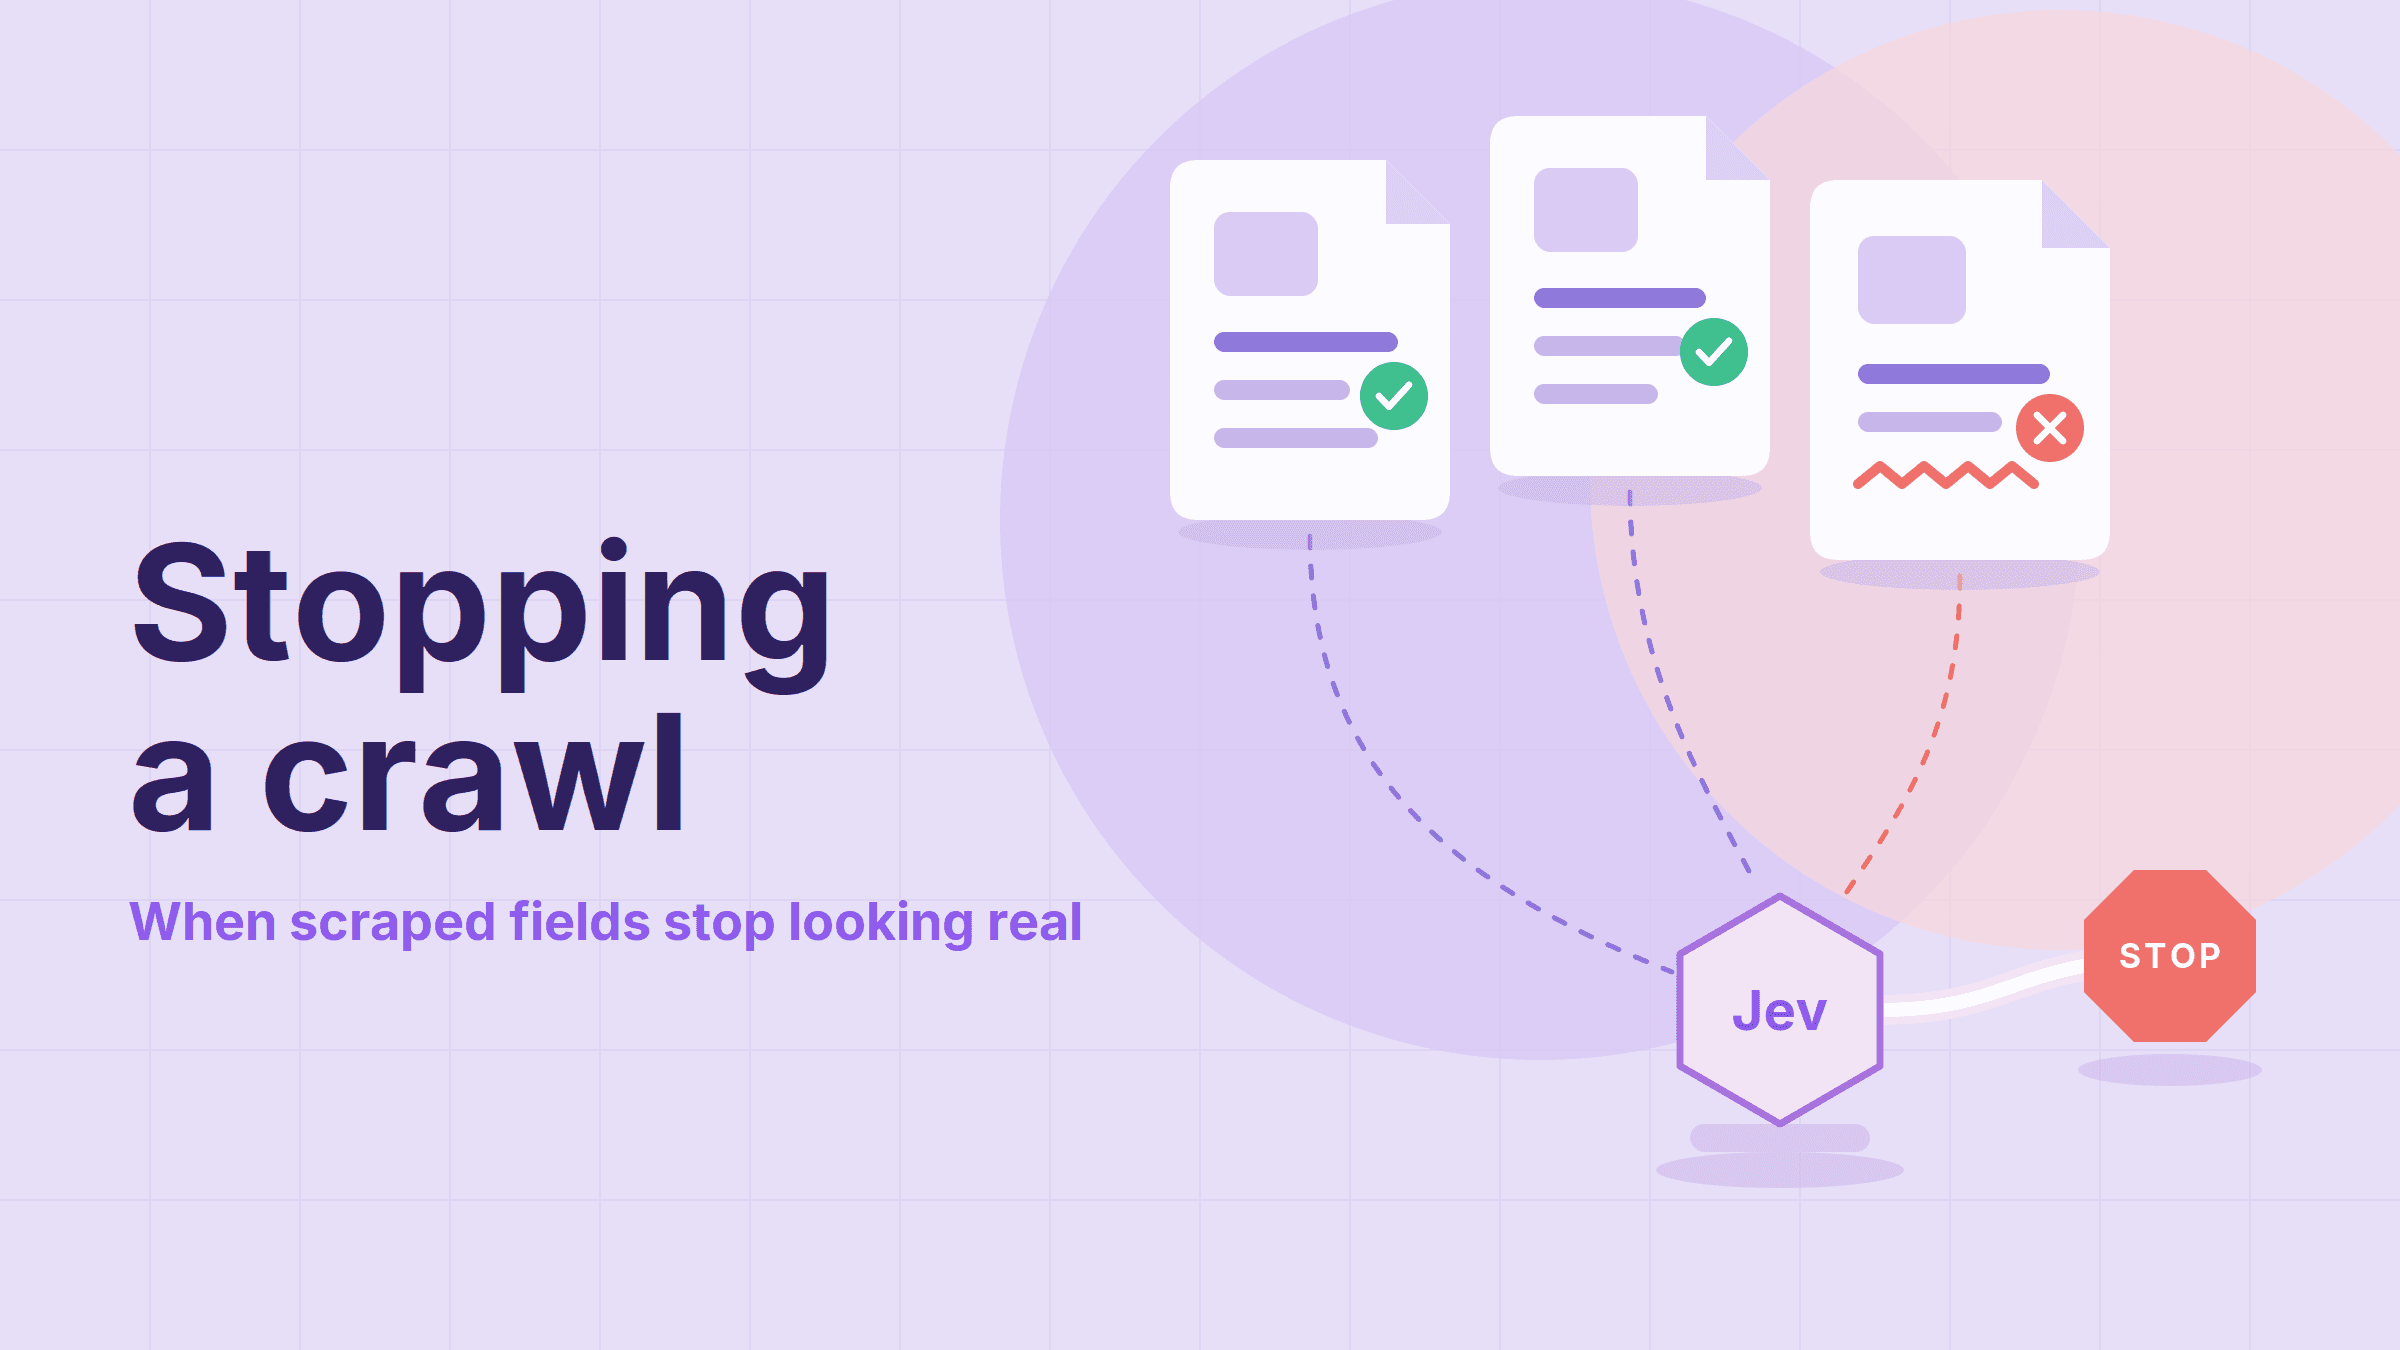
Stopping a crawl when the data stops looking real with Jev
A Scrapy pipeline that asks a fast, calibrated AI model whether each scraped field still looks real, and stops the crawl when too many don't. What it caught, what it misses, and whether building it was worth it.
Jev, the model that cannot write a word, and where it fits in web scraping(does it?)
Jev by TypeFace AI cannot generate a string, so it cannot extract a field. What it is, how it differs from an LLM, and the one job it earns in a scraping pipeline.