How To
Articles from the Zyte blog about How To.
Use cURL for web scraping: A Beginner's Guide
cURL simplifies data collection from websites via its command-line interface, making it essential for APIs, file transfers, and web scraping.
Scrapy Cloud secrets: Hub Crawl Frontier and how to use it
Our scrapy cloud secrets help you deal with real cases that put your data extraction pipeline at risk. You have to be fully prepared for every scenario.
How Web Scraping and Graph Databases Can Power Recommendation Engines
I recently had the pleasure of participating in the third episode of Graphversation, a monthly live stream series that brings together graph experts and Neo4j enthusiasts for engaging and enlightening discussions about the captivating world of graphs.
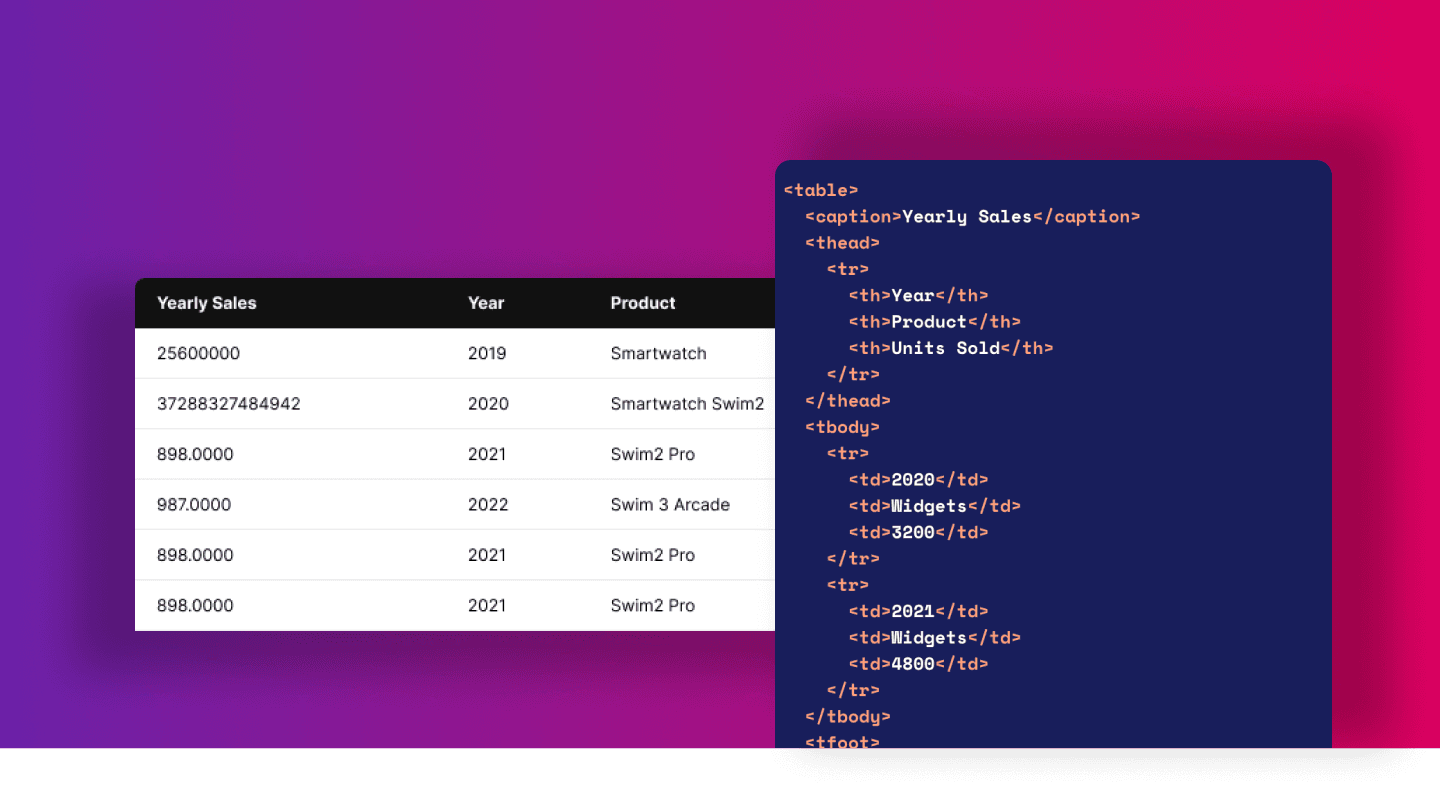
How to Extract Data From HTML Table
Learn how to extract data from a HTML table with step-by-step instructions. Get all the tips on extracting data from an HTML table in Python and Scrapy.
OnDemand: How to integrate Zyte data with +60 services, databases or APIs using YepCode
Learn how to use Zyte and YepCode together to quickly create automations and test new ideas.
Storing and Curating Your Web Crawling Data
Web crawlers are becoming increasingly popular in the era of big data, especially now with the advent of Large Language Models (LLMs) such as ChatGPT and LLaMA. The sheer amount of data that is publicly available from the web has a wide variety of applications including market research, sentiment analysis, and predictive modeling.
4 simple Steps for effective Automated Data QA Process
Learn how to develop an automated data QA process. Improve your web data quality applying a process that communicates with all your internal system procedures.
Data Parsing: How To Reduce Noise In The Data
Data parsing aims at reducing noise and structuring data. It is a very effective process when looking to work with structured and accurate data.
How to Extract Data From Website
Find out how can you actually extract data from websites? And what’s this thing called ‘web scraping’?
The Importance Of Web Data And How To Easily Access It
Web data touches every aspect of our lives. Extracting meaningful data from the web – reliably and at scale – can play a vital role to help companies succeed.
Advance Guide for Large Scale Web Scraping
From inconsistent website layouts to badly written HTML. Being able to scale web scraping comes with its share of difficulties. Follow this guide for help.