How To
Articles from the Zyte blog about How To.
Inside Scrapy's RemoteControl extension
Scrapy 2.19's RemoteControl extension runs a small authenticated HTTP server inside every crawl. How it starts, how it's secured, what the code you send can reach, and what you can do with it on a live crawl, plus the traps and what changes under scrapy-zyte-api.
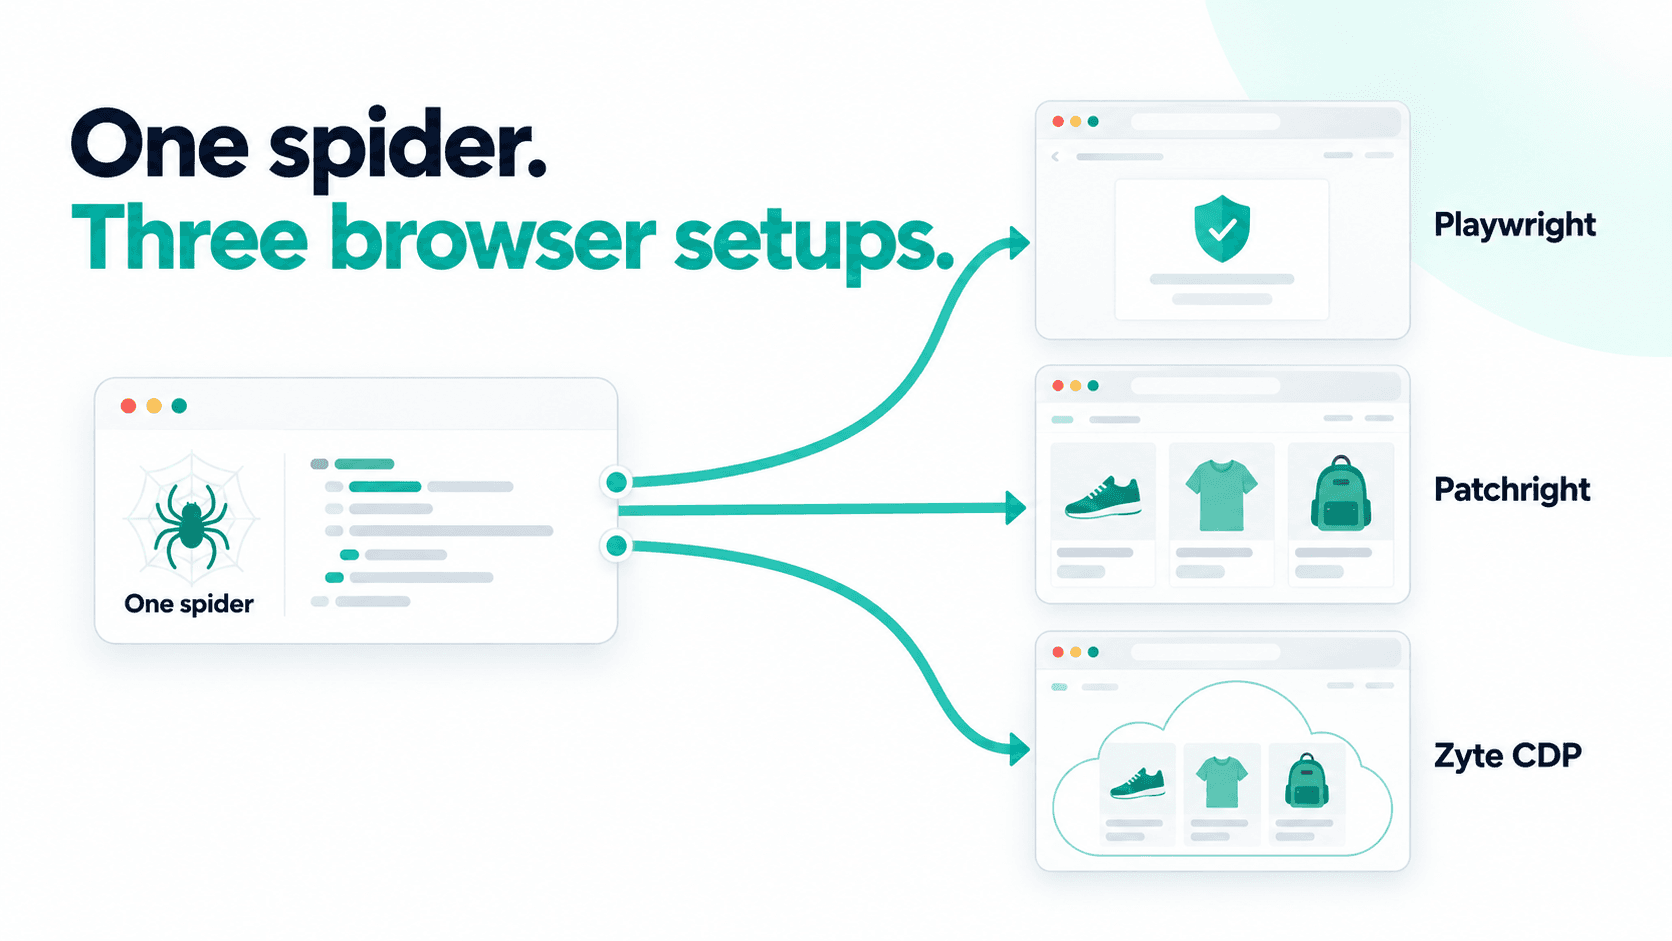
One Scrapy Spider, Three Browser Setups: Playwright, Patchright, and Zyte
One Scrapy spider, three browser setups: stock Playwright, Patchright via the new PLAYWRIGHT_BROWSER_PROVIDER hook, and a remote browser on Zyte over CDP. Same spider and selectors throughout, only the browser changes.

Running Playwright at scale: connecting to the Zyte CDP browser
We've released our CDP Browser, ideal for those with existing Playwright scripts looking for better access, as well as developers who need granular control over a browser, but don't want the hassle of running locally.
Harness Engineering #3- Headless mode: the minimal agent harness
What's the smallest harness that still works? Turns out it's already sitting inside almost every coding agent you have installed — headless mode: same loop, tools, and reasoning as the interactive agent, minus the human in the chair. We point it at a web page and pull clean, structured data out the other end in about ten lines.
AI generated these Scrapy projects - why I won't ship them
What happens if you let AI create a Scrapy project from just a simple prompt? Here's what I got and what I had to fix.
Web scraping for pricing intelligence: how to track competitor prices at scale
Compare the best headless browsers for web scraping in 2026. Learn when to use Playwright, Puppeteer, Selenium, or Zyte API’s managed CDP browser for scalable, anti-ban scraping.
Best headless browsers for web scraping in 2026
Compare the best headless browsers for web scraping in 2026. Learn when to use Playwright, Puppeteer, Selenium, or Zyte API’s managed CDP browser for scalable, anti-ban scraping.
Best proxy providers for web scraping in 2026 | Zyte
Compare the best proxy providers for web scraping in 2026. Learn which residential, ISP, and mobile proxies work best—and when teams move beyond proxies to automation.
Hybrid Scraping: The Architecture for the Modern Web
The Modern Web Scraping Method You NEED to Know
Learn how to scrape data in json format from a websites API
Scrape, Analyze & Visualize Web Data with Streamlit
Join Hyder Khan | Data Engineer, @ Flipdish as he shares how to extract, clean, analyze, and visualize web data using a seamless workflow with Streamlit.

Sustainability in Open Source | Fireside Chat
Learn how successful open-source projects balance community value with sustainable growth. Industry leaders share insights on monetization, maintenance, and building thriving communities.
More articles on How To
- Automate deployment of your web scraper on VPS with Ubuntu 24.04 cloud-init
- I'm not the same developer I was before LLMs
- Flatcar Linux for web scrapers: deploy immutable containers with just one config file
- Teaching AI to scrape like a pro: how we measure LLMs’ data quality
- AI Web Scraping as the Future of Scalable Data Collection
- Browser bother: Three painkillers for headless scraping headaches
- Leveraging Web Scraping and Big Data: The New Frontier in Optimized Delivery Solutions
- Inside Zyte's System Design Process: How We Build Scalable, Reliable Solutions
- Analyze web data quickly with Jupyter Notebooks and Zyte API
- Overcoming web scraping challenges of Puppeteer and Playwright
- How Session Management Minimizes Bans and Enhances Data Quality in Web Scraping
- Best web scraping methods for JavaScript-heavy websites
- Selenium, Puppeteer, Playwright: Which tool is right for web scraping at scale?
- Why are Sessions Crucial in Web Data Extraction?
- Geo-blocking solutions for digital shelf analytics
- Extract localized data with Zyte API’s extended geolocation
- Scrapy Cloud secrets: Hub Crawl Frontier and how to use it
- How Web Scraping and Graph Databases Can Power Recommendation Engines
- 4 simple Steps for effective Automated Data QA Process
- How To Avoid Web Scraping Blocks and Bans
- Manage website bans with Zyte Data API Smart Browser
- Data Parsing: How To Reduce Noise In The Data
- How Scrapy makes web crawling easy and accurate
- Extract JSONs Like A Pro With Chompjs And JMESPath
- The Importance Of Web Data And How To Easily Access It
- Advance Guide for Large Scale Web Scraping
- A Practical Guide to Web Data QA (Part V): Navigating Broad Crawls
- News & article data extraction: Open source vs closed source
- A Practical Guide To Web Data QA Part IV
- Scrapy Cloud Secrets: Hub Crawl Frontier And How To Use It
- Web Scraping | A Guide To Reliably Extract Data
- Guide To Web Data QA Part III: Holistic Data
- Product Reviews API (beta): Extract Product Reviews At Scale
- Custom Crawling & News API: Design A Web Scraping Solution
- Vehicle API (beta): Extract Automotive Data At Scale
- A Practical Guide To Web Data Extraction QA Part II
- A Practical Guide To Web Data QA Part I: Validation Techniques
- Scrapy & Zyte Automatic Extraction API Integration
- How to design a well-optimized web scraping solution
- Accessing the technical feasibility of your web scraping project
- How to define the scope of your web scraping project
- Deploy Your Scrapy Spiders From GitHub | Scrapy Cloud
- How To Run Python Scripts In Scrapy Cloud
- How To Deploy Custom Docker Images For Your Web Crawlers
- Scraping Infinite Scrolling Pages
- How To Debug Your Scrapy Spiders
- Machine Learning With Web Scraping: New MonkeyLearn Addon
- Scrapy Tips from the Pros (Part 1): Expert Advice for Better Scraping
- Link Analysis Algorithms Explained
- XPath Tips From The Web Scraping Trenches
- Extract Schema.Org Microdata with Scrapy Selectors
- Optimizing Memory Usage Of Scikit-Learn Models Using Succinct Tries
- Git Workflow For Scrapy Projects
- Spiders Activity Graphs
- Finding Similar Items